scattering list of objects causes poor memory management
- Dominant language
- Python
- Stars
- 1.7k
- Forks
- 778
- Avg merge
- 2h 50m
- Merged PRs (30d)
- 3
Description
distributed git tip as of today (56aed4489288fc95f36e9fe11f29a452c39de4ac), Linux x64
# Use case
I perform a single call to ``distributed.Client.scatter`` and pass to it a list of objects that is larger than what the cluster can accommodate.
# Issue
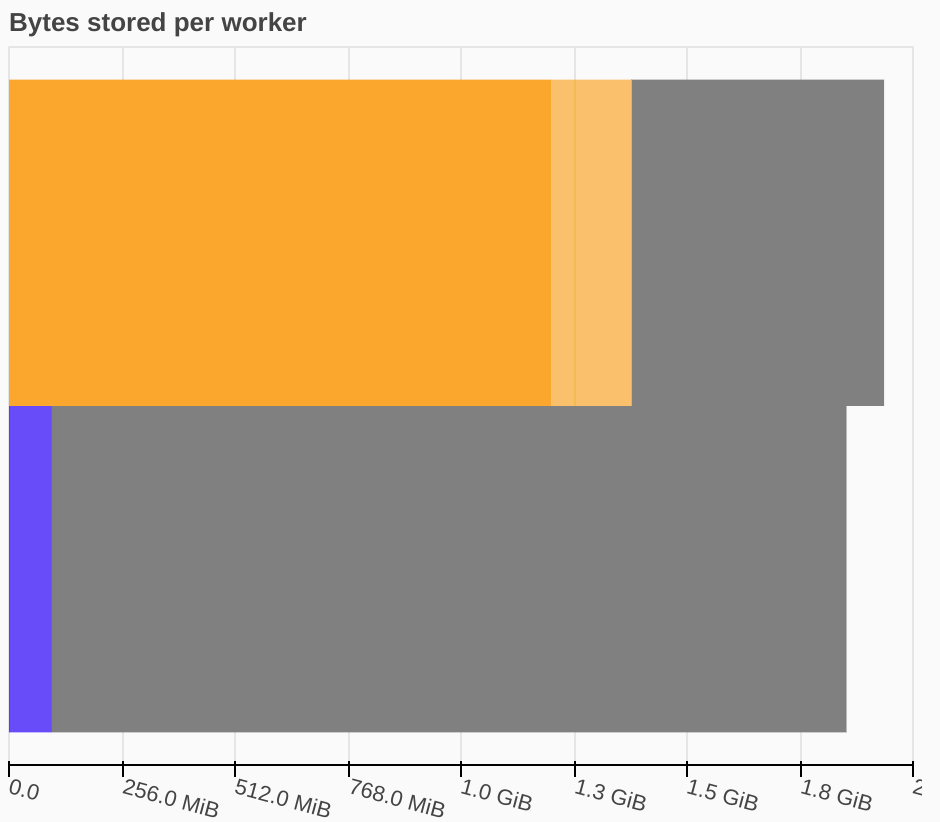
The whole list is spilled to disk instead of just the excess elements.
# Workaround
Break down the list into chunks and perform a burst of calls to scatter().
# POC
```python
import distributed
c = distributed.Client(n_workers=2, threads_per_worker=1, memory_limit="2 GiB")
c.wait_for_workers(2)
w0, w1 = c.has_what()
N = 1800
f0 = c.scatter(["x" * 2**20 for _ in range(N)], workers=[w0], hash=False)
f1 = []
for _ in range(N // 100):
f1 += c.scatter(["x" * 2**20 for _ in range(100)], workers=[w1], hash=False)
assert len(f0) == len(f1)
for ws in c.cluster.scheduler._workers.values():
print(ws.address)
print("=" * 40)
print(ws.memory)
```
Output:
```
tcp://127.0.0.1:40781
========================================
Managed by Dask : 1.76 GiB
- in process memory : 0 B
- spilled to disk : 1.76 GiB
Process memory (RSS) : 94.32 MiB
- managed by Dask : 0 B
- unmanaged (old) : 68.09 MiB
- unmanaged (recent): 26.23 MiB
tcp://127.0.0.1:44371
========================================
Managed by Dask : 1.74 GiB
- in process memory : 1.37 GiB
- spilled to disk : 372.02 MiB
Process memory (RSS) : 1.37 GiB
- managed by Dask : 1.37 GiB
- unmanaged (old) : 0 B
- unmanaged (recent): 0 B
```
Contributor guide
Assessment
This issue has not been assessed yet.