cockroachdb / cockroachdb/cockroach-operator
With RocksDB, Unable to Recover from Error State When Upgrading 20.2->21.1
- Dominant language
- Go
- Stars
- 318
- Forks
- 104
- Avg merge
- 1d 6h
- Merged PRs (30d)
- 1
Description
**Overview:**
In doing a negative test case when upgrading from `cockroachdb/cockroach:v20.2.7` to `cockroachdb/cockroach-unstable:v21.1.0-rc.2`, I receive an error, and I'm unable to bring one node out of its error state with the Operator.
**Error:**
```
ERROR: invalid argument "rocksdb" for "--storage-engine" flag: invalid storage engine: rocksdb (possible values: rocksdb, pebble)
Failed running "start"
```
**Reproduction Steps:**
1. Create a new GKE cluster
2. Apply CustomResourceDefinition: `kubectl apply -f config/crd/bases/crdb.cockroachlabs.com_crdbclusters.yaml`
3. Install the Operator `kubectl apply -f manifests/operator.yaml`
4. Install CockroachDB v20.2.7 with RocksDB set as storage engine in the additionalArg field, `kubectl apply -f examples/example.yaml`:
```
apiVersion: crdb.cockroachlabs.com/v1alpha1
kind: CrdbCluster
metadata:
name: cockroachdb
spec:
additionalArgs:
- "--storage-engine=rocksdb"
dataStore:
pvc:
spec:
accessModes:
- ReadWriteOnce
resources:
requests:
storage: "60Gi"
volumeMode: Filesystem
tlsEnabled: true
image:
name: cockroachdb/cockroach:v20.2.7
nodes: 3
```
4. Verify that CockroachDB is installed and running with RocksDB and open a SQL shell
5. Upgrade to v21.1.x with the RocksDB still set as storage engine:
apiVersion: crdb.cockroachlabs.com/v1alpha1
kind: CrdbCluster
metadata:
name: cockroachdb
spec:
additionalArgs:
- "--storage-engine=rocksdb"
dataStore:
pvc:
spec:
accessModes:
- ReadWriteOnce
resources:
requests:
storage: "60Gi"
volumeMode: Filesystem
tlsEnabled: true
image:
name: cockroachdb/cockroach-unstable:v21.1.0-rc.2
nodes: 3
6. I expect to see an error. To fix the cluster, I declaratively change the additionalArg by removing --storage-engine=rocksdb
**Expected Result:**
I expect the Operator to observe my new desired state of the storage engine to be set to Pebble. To do this, the Operator would bring down one pod at a time and bring the cluster back to a running state.
**Actual Results:**
- One pod stays in an error state:
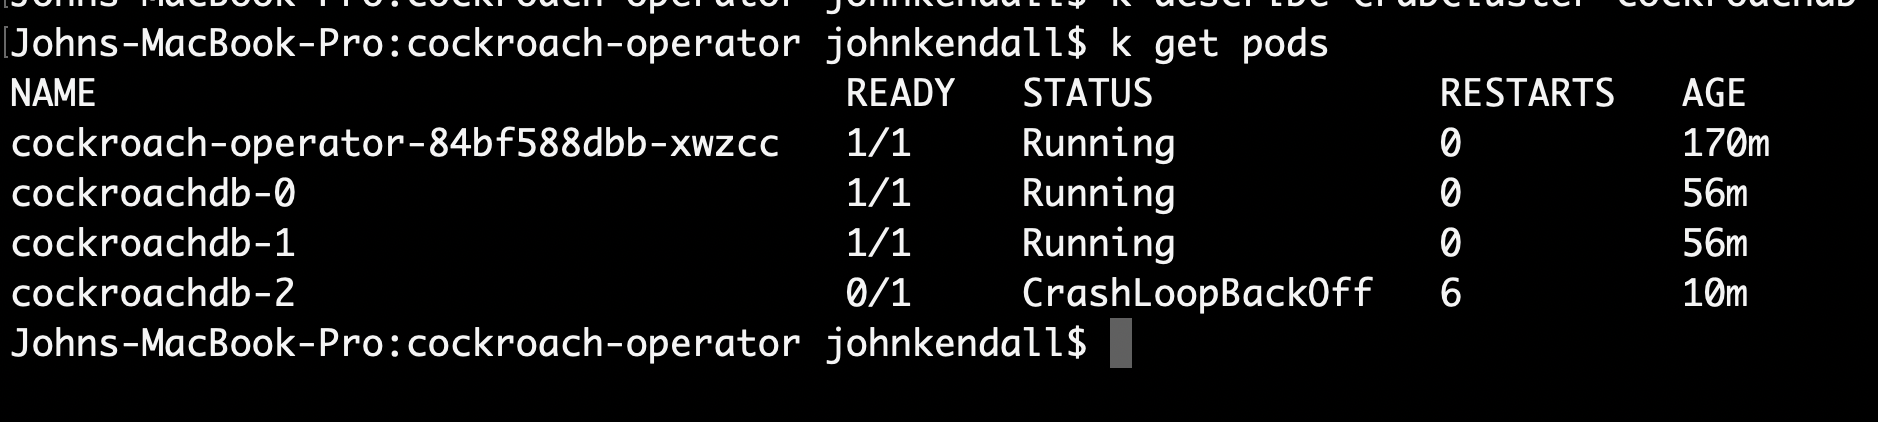
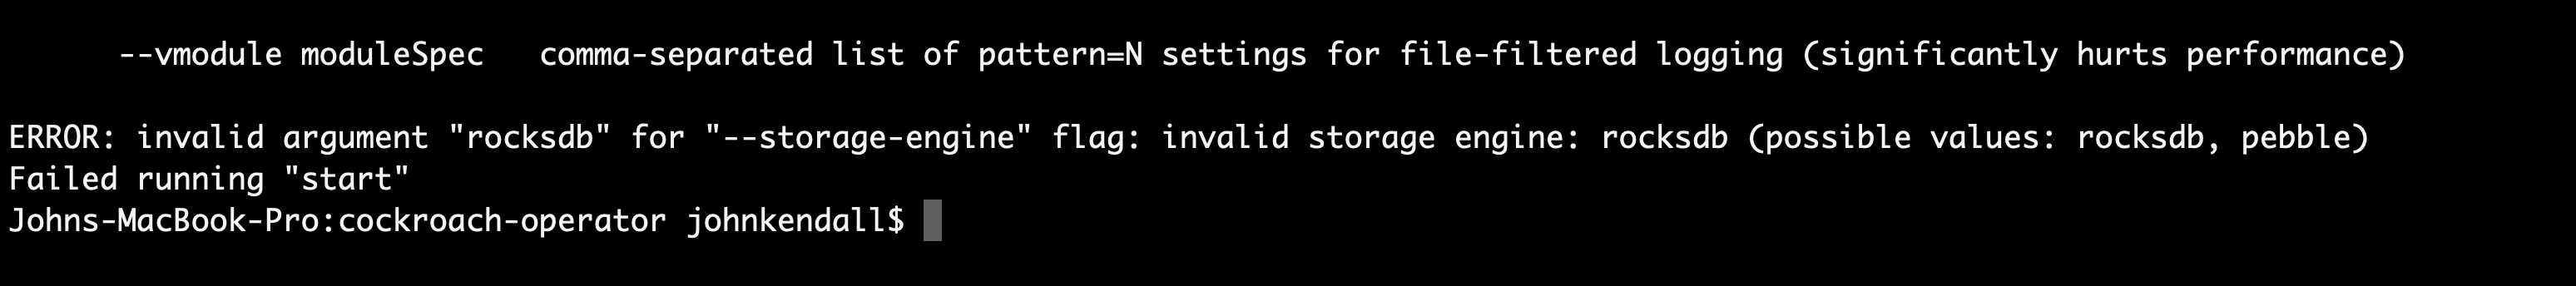
- and when prompted to change storage-engine to default by removing --storage-engine=rocksdb, it doesn't attempt to do a rolling update.
Contributor guide
No contributing guide indexed for this repository
Assessment
This issue has not been assessed yet.