Web scraper doesn't parse email links properly
Open
- Dominant language
- TypeScript
- Stars
- 427
- Forks
- 66
- PR merge metrics
- No merged PRs in 30d
Description
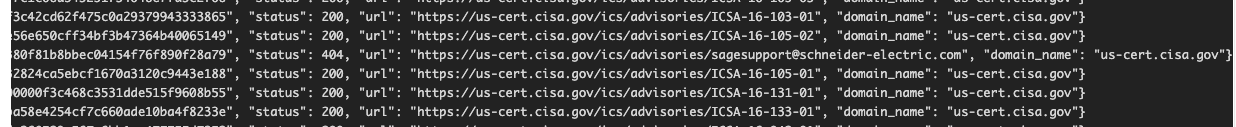
Email addresses should probably be ignored instead of being treated as they are currently:
Contributor guide
No contributing guide indexed for this repository
Research direction
The issue identifies the web scraper and includes a screenshot, but names no source file, test, or entry point. Find where the scraper handles links, reproduce the email-link behavior shown, and verify that email addresses are ignored rather than processed as web links.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- typescript
- Domain
- backend
- Issue type
- Bug
- Difficulty
- 3/5
- Estimated time
- 1-2 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 45/100