在作者模型上训练后再次训练报错
Open
- Dominant language
- Python
- Stars
- 36.9k
- Forks
- 5.2k
- PR merge metrics
- No merged PRs in 30d
Description
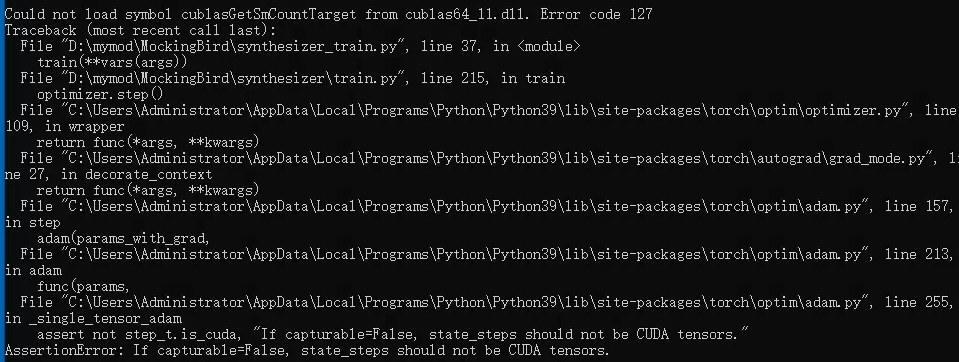
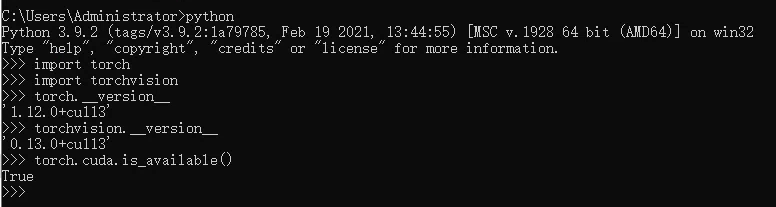
从cuda11.6降到cuda11.3还是不可以
Contributor guide
No contributing guide indexed for this repository
Research direction
The issue provides only screenshots and reports that retraining an author model fails, including after downgrading CUDA from 11.6 to 11.3. No source files, tests, traceback text, or entry points are mentioned. First reproduce the second-training failure and capture the full error and environment details; done means identifying a repeatable cause and confirming that retraining completes.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, pytorch
- Domain
- machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100