One long workload tasks prevents the entire instance to get new tasks (stuck on PENDING)
- Dominant language
- Shell
- Stars
- 5.4k
- Forks
- 334
- PR merge metrics
- No merged PRs in 30d
Description
Hello all.
Because this is something makes our production instances to be unstable in getting new tasks, and it harms our production workloads, I'm opening it here also.
## The problem
We're facing lately a strange practice from ECS about tasks that prevent from new tasks to run in an instance.
A little about our case -
We have some tasks that need to complete their activities and then exit by themselves in a stopTask command. That means we have a gracefull-shutdown process, that sometimes takes some time to complete (more than a few seconds and even some long minutes).
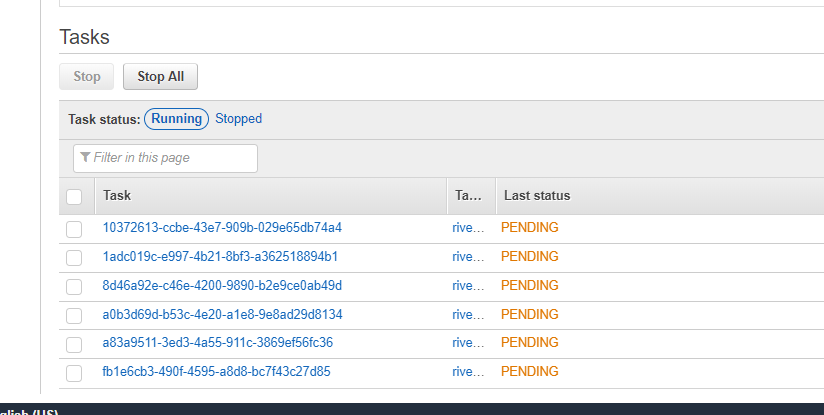
However, when a stopTask is sent over these tasks, they do not appear anymore in the tasks at ECS console (which is fine), but they also make all other tasks in the same instance that are trying to change their state from PENDING to RUNNING.
## The Effect
For example, you can see a typical production workloads desire/running gap:

The Green layer is the gap between the desired and the running (orange layer) tasks. The blue is the PENDING tasks in the cluster. You can see a constant gap between these two parameters. No deployment was made today and this is something we're encountering in scaling up mechanism.
Think about the situation we're encountering. We have new tasks in our queue (SQS), and therefore we're asking from the ECS to run new tasks (means - desire tasks increasing).
Each workload is a task in the ECS, and all of them split between the servers.
When we have some workload take more than some time to complete (and there are many of them because we're asking for the workload to end it's task before it ends and then die) one workload blocks the entire instance to get new one workload, even there are free resources in the instance.
The ECS agent schedule new workloads to that instance, and then hits the one task that is still working. For the agent - he made its job - he scheduled new tasks. But the tasks are stuck in PENDING state, for hours in some cases, makes this instance to be unusable because they're just not working yet. Now think about, that you need to raise the more 100 tasks in some hours to complete quick workloads in the line, and you have 5-6 instances with one task blocks each one, and it becomes to be a mass.
We also must say we encounter this in the last year only, after some upgrade of the agent a year or year and a half ago. We must say this is something that prevents our workloads to grow accordingly to our tasks, and there are situations this behavior actually stuck our production servers, something that can be a no-go (or no-continue in our case) using ECS in prod.
We need every day to ask for more instances in our workloads in order to open the block. This is not how a production service in AWS should be maintained, and we're facing that again and again in this case, every day.
Please help us to continue using ECS as our production orchestrator. We love this product and want it to succeed, but as it seems, it doesn't fit long-working tasks.
## The solution
The best thing will be that the stopped task will appear in the console until it really stopped in the instance, and the state changing from PENDING to RUNNING won't be affected by other tasks in the same instance.
I hope you can fix that behavior as soon as possible,
Thanks!
Alon
Contributor guide
Research direction
The issue names no repository files, tests, or code entry points; begin by reviewing the ECS agent scheduling and task state behavior described in the report. Reproduce the PENDING-to-RUNNING blockage with a long graceful shutdown and available instance capacity, then verify that placement is no longer blocked by stopping tasks.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- aws
- Domain
- cloud, infrastructure
- Issue type
- Bug
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100