[ECS] [request]: Updating capacity provider to be AWS should give a failure message when it fails.
- Dominant language
- Shell
- Stars
- 5.4k
- Forks
- 334
- PR merge metrics
- No merged PRs in 30d
Description
### Community Note
* Please vote on this issue by adding a 👍 [reaction](https://blog.github.com/2016-03-10-add-reactions-to-pull-requests-issues-and-comments/) to the original issue to help the community and maintainers prioritize this request
* Please do not leave "+1" or "me too" comments, they generate extra noise for issue followers and do not help prioritize the request
* If you are interested in working on this issue or have submitted a pull request, please leave a comment
**Tell us about your request**
What do you want us to build?
Notifications that an AWS managed autoscaling group won't be autoscaled if there is already a dynamic scaling policy.
**Which service(s) is this request for?**
ECS
**Tell us about the problem you're trying to solve. What are you trying to do, and why is it hard?**
What outcome are you trying to achieve, ultimately, and why is it hard/impossible to do right now? What is the impact of not having this problem solved? The more details you can provide, the better we'll be able to understand and solve the problem.
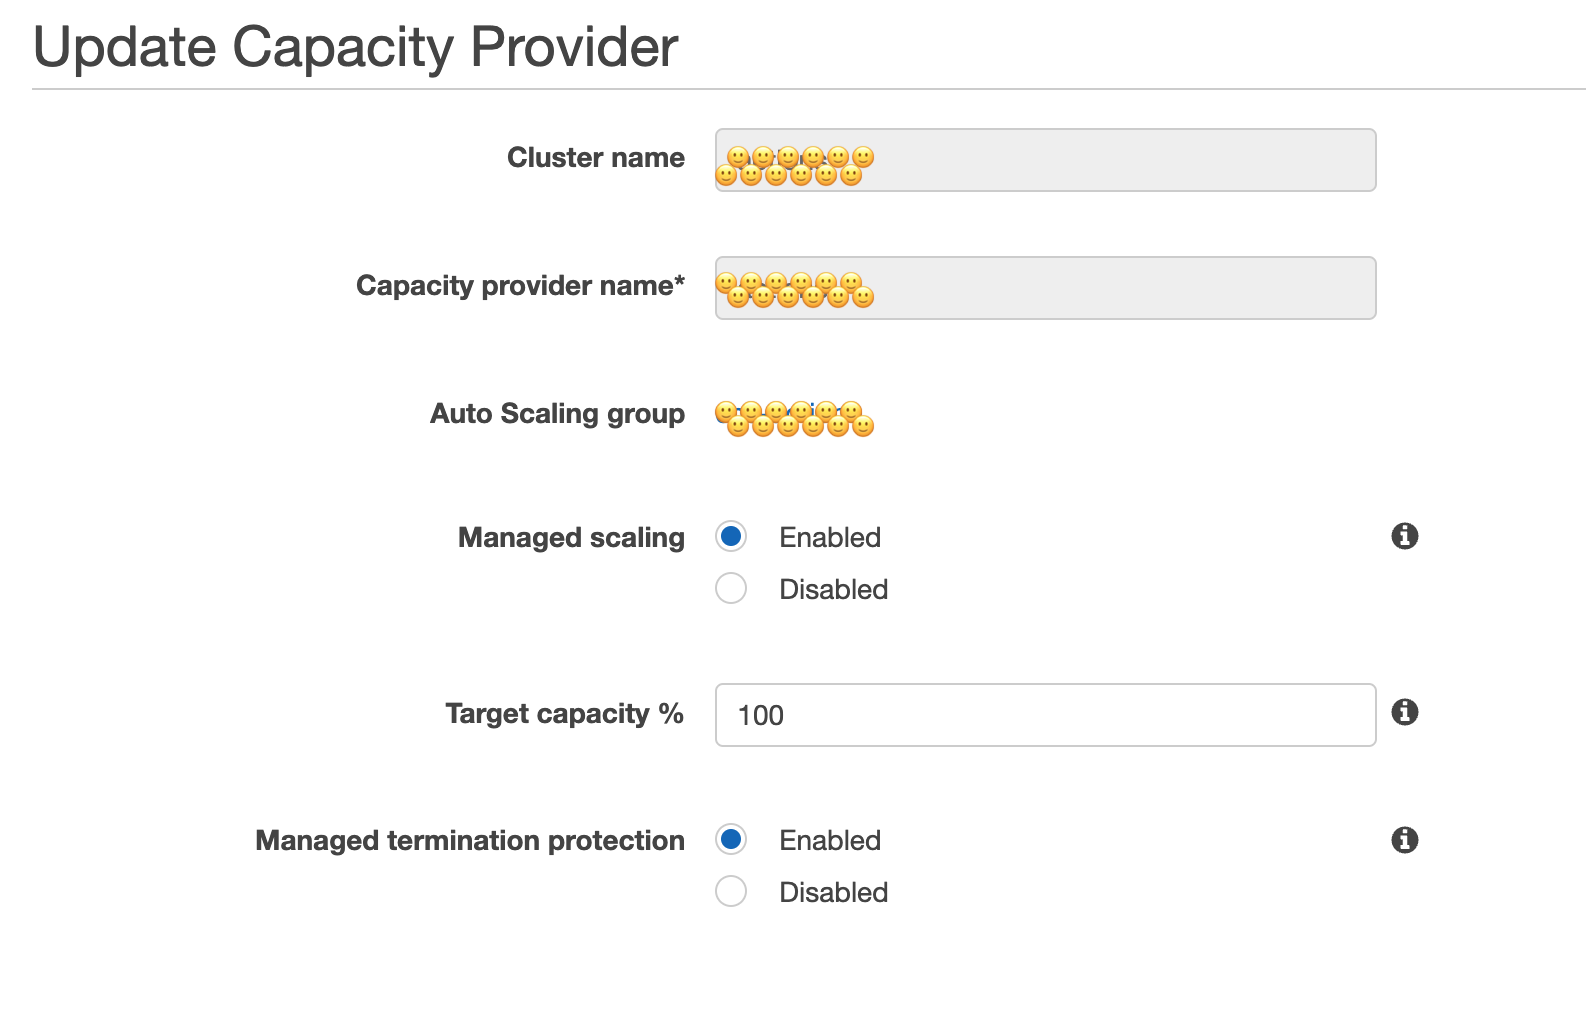
When converting old ASGs over to AWS managed via CAS, there are two alarms in cloudwatch and a dynamic scaling policy added the ASG. If there is already a dynamic scaling policy in place, it looks like the management request succeeded but nothing happens.
**Are you currently working around this issue?**
How are you currently solving this problem?
Deleting the existing dynamic scaling policy before turning auto-management on.
**Additional context**
Anything else we should know?
The problem occurs in the old interface, when in the "Update Capacity Provider" section of the capacity provider page.
Contributor guide
Research direction
Start in the old interface's Update Capacity Provider section and reproduce the conversion with an existing dynamic scaling policy on the Auto Scaling group. Confirm the request currently appears successful without changing management state; done means the failure is clearly reported when AWS cannot enable managed autoscaling.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- aws
- Domain
- cloud
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100