[ECS] [request]: Improve Task Scheduling Fairness
- Dominant language
- Shell
- Stars
- 5.4k
- Forks
- 334
- PR merge metrics
- No merged PRs in 30d
Description
### Community Note
* Please vote on this issue by adding a 👍 [reaction](https://blog.github.com/2016-03-10-add-reactions-to-pull-requests-issues-and-comments/) to the original issue to help the community and maintainers prioritize this request
* Please do not leave "+1" or "me too" comments, they generate extra noise for issue followers and do not help prioritize the request
* If you are interested in working on this issue or have submitted a pull request, please leave a comment
**Tell us about your request**
When multiple services that use the same EC2 Capacity Provider scale up at the same time, ECS does not always schedule tasks for these services fairly.
**Which service(s) is this request for?**
ECS
**Tell us about the problem you're trying to solve. What are you trying to do, and why is it hard?**
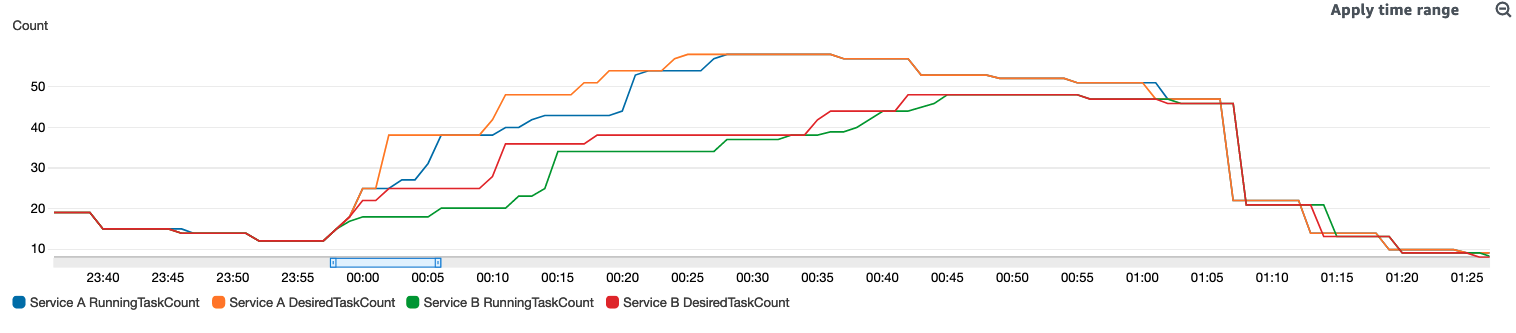
We have two services that require a GPU. These two services share a Capacity Provider. These services scale based on the same metric, so they almost always scale up and down at the same time (give or take a few seconds).
When multiple scaling activities occur, we occasionally see ECS schedule many more tasks for one service than the other. I've attached a concrete example from one of our environments. You can see that the desired count for both services increases right around 23:57. By 00:05, service A has scheduled 20+ new tasks, service B has only scheduled 3 new tasks. Around 00:15, this happens again, albeit with service B getting more scheduling attention than service A.
When this happens, we see significant performance degradation from the service that ECS decides not to schedule.
**Are you currently working around this issue?**
We do not have a workaround in place. Theoretically, creating service-specific Capacity Providers would solve this issue.
**Additional context**
- Our GPU Capacity Provider makes use of single-GPU instances.
- Our app autoscaling policies on these services have 60-second cooldowns
**Attachments**
Contributor guide
Research direction
The issue names ECS task scheduling, EC2 Capacity Providers, and two GPU-backed services but provides no repository files, tests, or implementation entry point. Start by reviewing the reported scaling scenario and attached scheduling example. Done would require a maintainer-defined change to scheduling behavior and evidence that simultaneous scale-ups across shared GPU Capacity Providers are handled more fairly.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- aws
- Domain
- cloud
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100