aws-samples / aws-samples/sm-data-wrangler-mlops-workflows
1-sagemaker-pipelines example is training with headers in the dataset and using the index as the label
- Dominant language
- Jupyter Notebook
- Stars
- 18
- Forks
- 6
- PR merge metrics
- No merged PRs in 30d
Description
Hi,
I have been following the example notebooks in the [1-sagemaker-pipelines](https://github.com/aws-samples/sm-data-wrangler-mlops-workflows/tree/main/1-sagemaker-pipelines) directory to create a Sagemaker pipeline that uses a Data Wrangler flow.
I am trying to get my head around how the Sagemaker XGBoost library ingest the training data created in Data Wrangler. After running the pipeline, I downloaded the training dataset generated by Data Wrangler and noticed that:
- The header is still in the CSV file
- The first column of the dataset is the index
However, in the [Sagemaker XGBoost algorithm documentation](https://docs.aws.amazon.com/sagemaker/latest/dg/xgboost.html#InputOutput-XGBoost), it states that
> For CSV training, the algorithm assumes that the target variable is in the first column and that the CSV does not have a header record.
I can confirm the header is ingested into the training dataset by checking the logs in the training job. The job is reporting 5001 rows in the training dataset when it should be 5000 without the header.
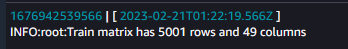
Furthermore, I know the index column is used as a label because I can train a `multi:softmax` model with 5001 classes. If I try and create a `multi:softmax` model with 5000 classes, I get the error ` SoftmaxMultiClassObj: label must be in [0, num_class).`
Contributor guide
Assessment
This issue has not been assessed yet.