Boolean DocValues Codec Implementation [LUCENE-8689]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 88
Description
To avoid issues where some products become available/unavailable at some point in time after being out-of-stock, e-commerce search system designers need to embed up-to-date information about inventory availability right into the search engines. Key requirement is to be able to accurately filter out unavailable products and use availability as one of ranking signals. However, keeping availability data up-to-date is a non-trivial task. Straightforward implementation based on a partial updates of Lucene documents causes Solr cache trashing with negatively affected query performance and resource utilization.
As an alternative solution we can use DocValues and build-in in-place updates where field values can be independently updated without touching inverted index, and while filtering by DocValues is a bit slower, overall performance gain is better. However existing long based docValues are not sufficiently optimized for carrying boolean inventory availability data:
- All DocValues queries are internally rewritten into org.apache.lucene.search.DocValuesNumbersQuery which is based on direct iteration over all column values and typically much slower than using TermsQuery.
- On every commit/merge codec has to iterate over DocValues a couple times in order to choose the best compression algorithm suitable for given data. As a result for 4K fields and 3M max doc merge takes more than 10 minutes
This issue is intended to solve these limitations via special bitwise doc values format that uses internal representation of org.apache.lucene.util.FixedBitSet in order to store indexed values and load them at search time as a simple long array without additional decoding. There are several reasons for this:
- At index time encoding is super fast without superfluous iterations over all values to choose the best compression algorithm suitable for given data.
- At query time decoding is also simple and fast, no GC pressure and extra steps
- Internal representation allows to perform random access in constant time
Limitations are:
- Does not support non boolean fields
- Boolean fields must be represented as long values 1 for true and 0 for false
- Current implementation does not support advanced bit set formats like org.apache.lucene.util.SparseFixedBitSet or org.apache.lucene.util.RoaringDocIdSet
In order to evaluate performance gain I've wrote a simple JMH based benchmark [SynteticDocValuesBench70.java](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/SynteticDocValuesBench70.java) which allows to estimate a relative cost of DF filters. This benchmark creates 2 000 000 documents with 5 boolean columns with different density, where 10, 35, 50, 60 and 90 is an amount of documents with value 1. Each method tries to enumerate over all values in synthetic store field in all available ways:
- baseline – in almost all cases Solr uses FixedBitSet in filter cache to keep store availability. This test just iterates over all bits.
- docValuesRaw – iterates over all values of DV column, the same code is used in "post filtering", sorting and faceting.
- docValuesNumbersQuery – iterates over all values produced by query/filter store:1, actually there is the only query implementation for DV based fields - DocValuesNumbersQuery. This means that Lucene rewrites all term, range and filter queries for non indexed filed into this fallback implementation.
- docValuesBooleanQuery – optimized variant of DocValuesNumbersQuery, which support only two values – 0/1
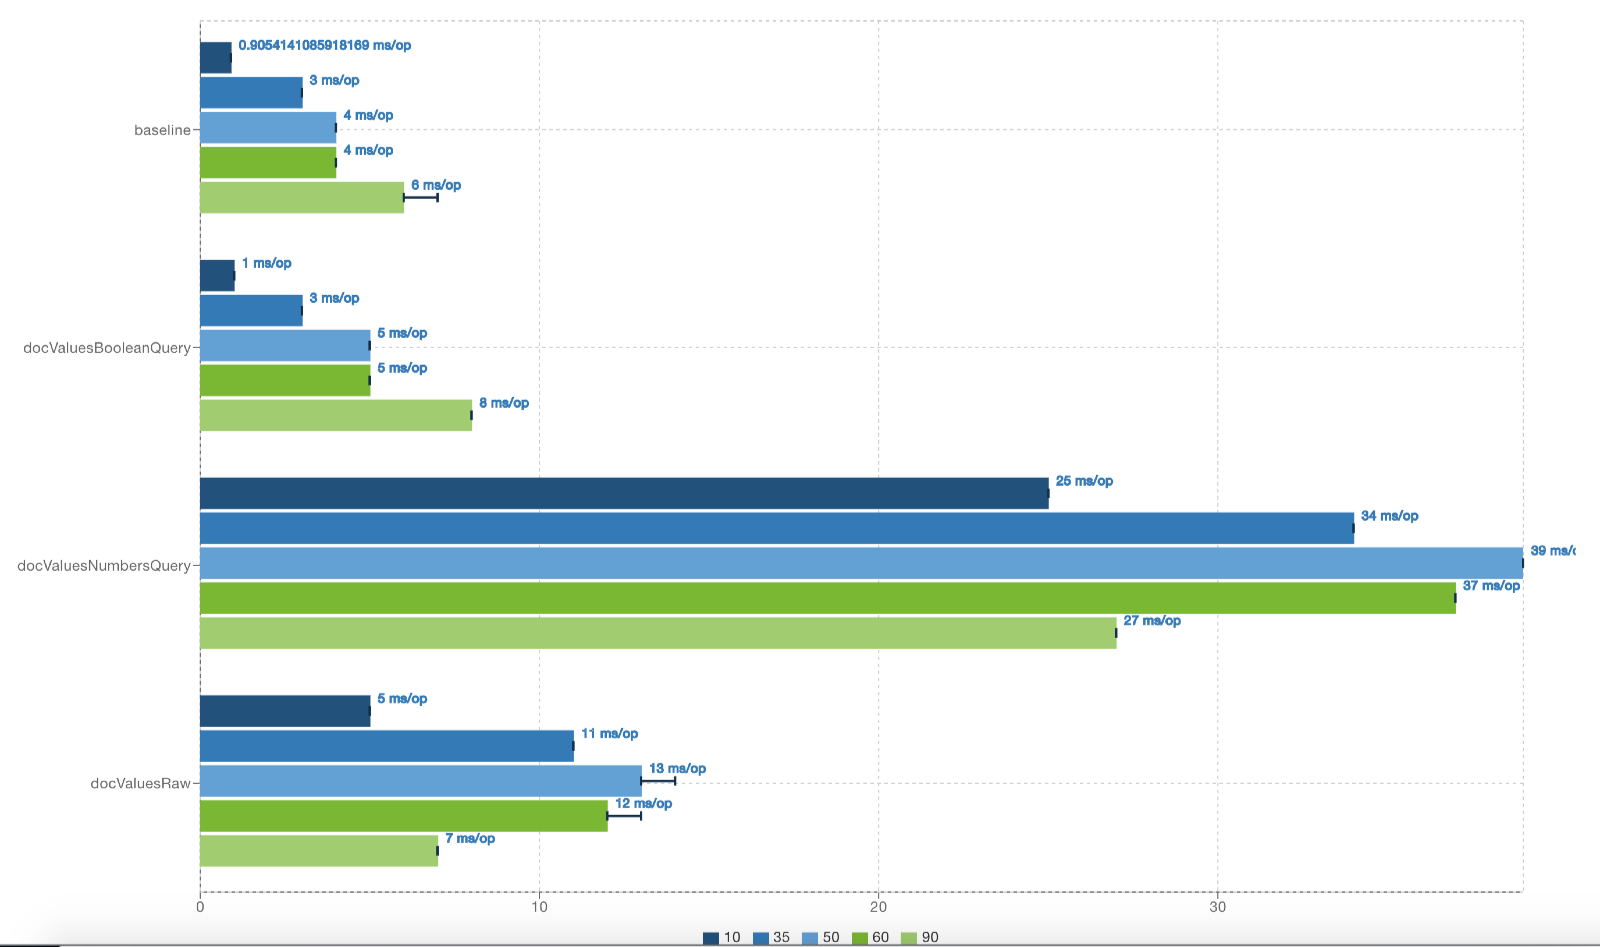
Query latency is similar to FixedBitSet with negligible overhead 1-2 ms. DocValuesNumbersQuery 6-7 times slower compared to boolean query. Raw doc values iterator is also not so fast as it performs on-the-fly decoding.
Attached patch contains two parts:
- bitwise codec and all required structures and producers/consumers
- boolean query which removes TwoPhaseIterator, AllBits approximation and missing docs lookup
- docValues codec test green except non long values cases
SynteticDocValuesBench70.java
```java
package org.apache.lucene.codec;
import org.apache.lucene.codecs.bool.Boolean70Codec;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.*;
import org.apache.lucene.search.*;
import org.apache.lucene.store.FSDirectory;
import org.apache.lucene.util.FixedBitSet;
import org.openjdk.jmh.annotations.*;
import org.openjdk.jmh.profile.GCProfiler;
import org.openjdk.jmh.profile.LinuxPerfAsmProfiler;
import org.openjdk.jmh.profile.StackProfiler;
import org.openjdk.jmh.results.format.ResultFormatType;
import org.openjdk.jmh.runner.Runner;
import org.openjdk.jmh.runner.options.Options;
import org.openjdk.jmh.runner.options.OptionsBuilder;
import org.openjdk.jmh.runner.options.VerboseMode;
import java.io.File;
import java.io.IOException;
import java.util.List;
import java.util.Random;
import java.util.concurrent.TimeUnit;
/**
* This benchmark compares latency of different lucene's filter query implementations.
* Of course there are a lot of trade-offs and pitfalls when you are trying to compare abstract solution
* in one small benchmark.
* This benchmark is intended to show the difference for one particular and important e-commerce use case:
* inventory availability. In this case we have quite huge set of dense columns/fields, with the only flow:
* filter and sort by availability.
*
* In general we have only two approaches to apply filter query: use filter cache or use doc values.
* Filter cache is fast enough and it keeps filters in quite compact bitset structure. For DocValues
*/
@BenchmarkMode(Mode.AverageTime)
@OutputTimeUnit(TimeUnit.MILLISECONDS)
@Warmup(iterations = 3, time = 3)
@Measurement(iterations = 2, time = 2)
@Fork(value = 1)
@State(Scope.Benchmark)
public class SynteticDocValuesBench70 {
private static final String TEMPORARY_PATH = "/tmp/bench";
private static final String STORE_AS_IS = "store_";
private static final String BOOLEAN_STORE = "boolean_store_";
private LeafReaderContext leafReaderContext;
private DirectoryReader reader;
private IndexSearcher searcher;
@Param({"10", "35", "50", "60", "90"})
private int density;
private FixedBitSet bitSet;
private int maxDoc = 2000000;
private String store;
public static void main(String[] args) throws Exception {
Options options = new OptionsBuilder()
.include(SynteticDocValuesBench70.class.getName())
.forks(2)
.verbosity(VerboseMode.NORMAL)
.resultFormat(ResultFormatType.JSON) // https://jmh.morethan.io in order to visualize this report
.build();
new Runner(options).run();
}
@Setup
public void init() throws IOException {
createIndex();
FSDirectory directory = FSDirectory.open(new File(TEMPORARY_PATH).toPath());
reader = DirectoryReader.open(directory);
searcher = new IndexSearcher(reader);
List leaves = reader.leaves();
leafReaderContext = leaves.get(0);
maxDoc = reader.numDocs();
store = getStore(STORE_AS_IS);
System.out.printf("evalNumbersIterator %s %d%n", store, evalIterator(getResultSetNumbers(store)));
System.out.printf("evalBooleanIterator %s %d%n", store, evalIterator(getResultSetBoolean("boolean_" + store)));
System.out.printf("evalDocValIterator %s %d%n", store, evalDocValues(store));
}
/**
* Creates a small density index with different column variations.
*/
private void createIndex() throws IOException {
Random random = new Random();
FSDirectory directory = FSDirectory.open(new File(TEMPORARY_PATH).toPath());
IndexWriterConfig conf = new IndexWriterConfig(null);
conf.setOpenMode(IndexWriterConfig.OpenMode.CREATE);
conf.setUseCompoundFile(false);
conf.setMaxBufferedDocs(500000);
conf.setRAMBufferSizeMB(1024);
conf.setCodec(new Boolean70Codec());
IndexWriter writer = new IndexWriter(directory, conf);
bitSet = new FixedBitSet(maxDoc);
float probability = density / 100f;
for (int i = 0; i < maxDoc; i++) {
if (random.nextFloat() < probability) {
bitSet.set(i);
}
}
for (int i = 0; i < maxDoc; i++) {
Document doc = new Document();
doc.add(new StringField("id", "" + i, Field.Store.NO));
int value = bitSet.get(i) ? 1 : 0;
if (value == 0 && random.nextBoolean()) {
continue; //to check different compression
}
doc.add(new NumericDocValuesField(STORE_AS_IS + density, value));
doc.add(new NumericDocValuesField(BOOLEAN_STORE + density, value));
writer.addDocument(doc);
}
// writer.forceMerge(1);
writer.commit();
}
private String getStore(String storePrefix) {
return storePrefix + density;
}
private int evalIterator(DocIdSetIterator iterator) throws IOException {
int result = 0;
while (iterator.nextDoc() != DocIdSetIterator.NO_MORE_DOCS) {
result++;
}
return result;
}
private int evalDocValues(String columnName) throws IOException {
int result = 0;
NumericDocValues numericDocValues = DocValues.getNumeric(leafReaderContext.reader(), columnName);
while (numericDocValues.nextDoc() != DocIdSetIterator.NO_MORE_DOCS) {
if (numericDocValues.longValue() == 1)
result += 1;
}
return result;
}
/**
* In almost all cases Solr uses FixedBitSet in filter cache to keep store availability filters.
* This data structure is dense and fast due to optimizations at CPU level(it checks the whole long in 1 popcnt
* instruction)
* So we can use this as a baseline, i.e. as the fastest implementation.
*/
@Benchmark
@OutputTimeUnit(TimeUnit.MILLISECONDS)
public int baseline() {
int result = 0;
//actually this is how filter works in Solr. It iterates through all values and delegates search to downstream collectors
for (int ord = bitSet.nextSetBit(0); ord != DocIdSetIterator.NO_MORE_DOCS; ord = ord + 1 >= bitSet.length() ? DocIdSetIterator.NO_MORE_DOCS : bitSet.nextSetBit(ord + 1)) {
result++;
}
return result;
}
@Benchmark
@OutputTimeUnit(TimeUnit.MILLISECONDS)
public int docValuesNumbersQuery() throws IOException {
return evalIterator(getResultSetNumbers(store));
}
@Benchmark
@OutputTimeUnit(TimeUnit.MILLISECONDS)
public int docValuesBooleanQuery() throws IOException {
return evalIterator(getResultSetBoolean("boolean_" + store));
}
@Benchmark
@OutputTimeUnit(TimeUnit.MILLISECONDS)
public int docValuesRaw() throws IOException {
return evalDocValues(store);
}
private DocIdSetIterator getResultSetNumbers(String storeName) throws IOException {
Query query = new DocValuesNumbersQuery(storeName, 1L);
query = query.rewrite(reader);
Weight weight = query.createWeight(searcher, false, 1);
Scorer scorer = weight.scorer(leafReaderContext);
return scorer.iterator();
}
private DocIdSetIterator getResultSetBoolean(String storeName) throws IOException {
Query query = new DocValuesBooleanQuery(storeName);
query = query.rewrite(reader);
Weight weight = query.createWeight(searcher, false, 1);
Scorer scorer = weight.scorer(leafReaderContext);
return scorer.iterator();
}
}
```
---
Migrated from [LUCENE-8689](https://issues.apache.org/jira/browse/LUCENE-8689) by Ivan Mamontov, 3 votes, updated May 20 2019
Attachments: [benchmark_dense.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/benchmark_dense.png), [boolean_vs_dense_vs_sparse_indexing.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/boolean_vs_dense_vs_sparse_indexing.png), [boolean_vs_dense_vs_sparse_updates.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/boolean_vs_dense_vs_sparse_updates.png), [dense_vs_sparse_querying.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/dense_vs_sparse_querying.png), [LUCENE-8689.patch](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/LUCENE-8689.patch) (versions: 2), [results2.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/results2.png), [SynteticDocValuesBench70.java](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/SynteticDocValuesBench70.java), [SynteticDocValuesBench80.java](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-8689/SynteticDocValuesBench80.java)
Contributor guide
Research direction
Start with SynteticDocValuesBench70.java and compare the existing DocValuesNumbersQuery path with DocValuesBooleanQuery and Boolean70Codec. Review the attached codec structures and producers/consumers, then verify the boolean codec and query behavior with the codec tests; completion should address the stated non-boolean limitations and the remaining non-long test cases.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- backend, search
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100