More efficient way to transform a RegExp to an Automaton [LUCENE-7921]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 88
Description
Consider the following example:
```Java
public static void main(String[] args) {
org.apache.lucene.util.automaton.RegExp regExp =
new org.apache.lucene.util.automaton.RegExp("[a-z]{1,13}x[a-z][a-z]?[a-z]?[a-z]?[a-z]?[a-z]{0,8}");
org.apache.lucene.util.automaton.Automaton automaton = regExp.toAutomaton();
System.out.println("states: " + automaton.getNumStates());
System.out.println("transitions: " + automaton.getNumTransitions());
System.out.println("-------------------------------");
try {
regExp = new org.apache.lucene.util.automaton.RegExp("[a-z]{1,13}x[a-z]{1,13}");
automaton = regExp.toAutomaton();
System.out.println("Will not happen...");
} catch (org.apache.lucene.util.automaton.TooComplexToDeterminizeException e) {
automaton = regExp.toAutomaton(1_000_000);
System.out.println("states: " + automaton.getNumStates());
System.out.println("transitions: " + automaton.getNumTransitions());
System.out.println("-------------------------------");
}
}
```
Both regular expressions are equivalent, but it's much more efficient to "unroll" the repetition. It might be possible to optimize the Regex#toAutomaton() method to handle this repetition without going over the default number of determinized states, and using less memory and CPU?
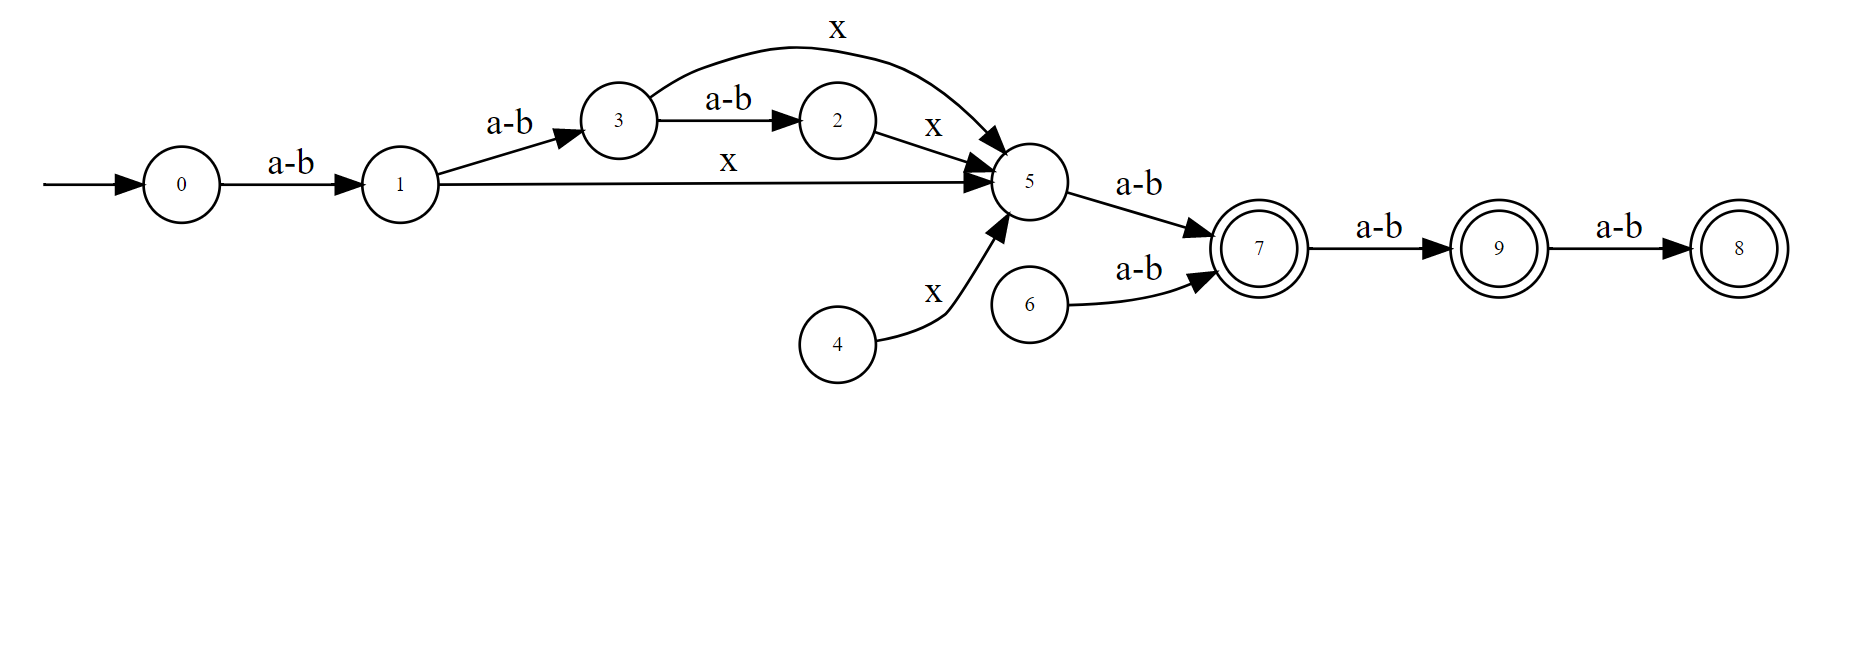
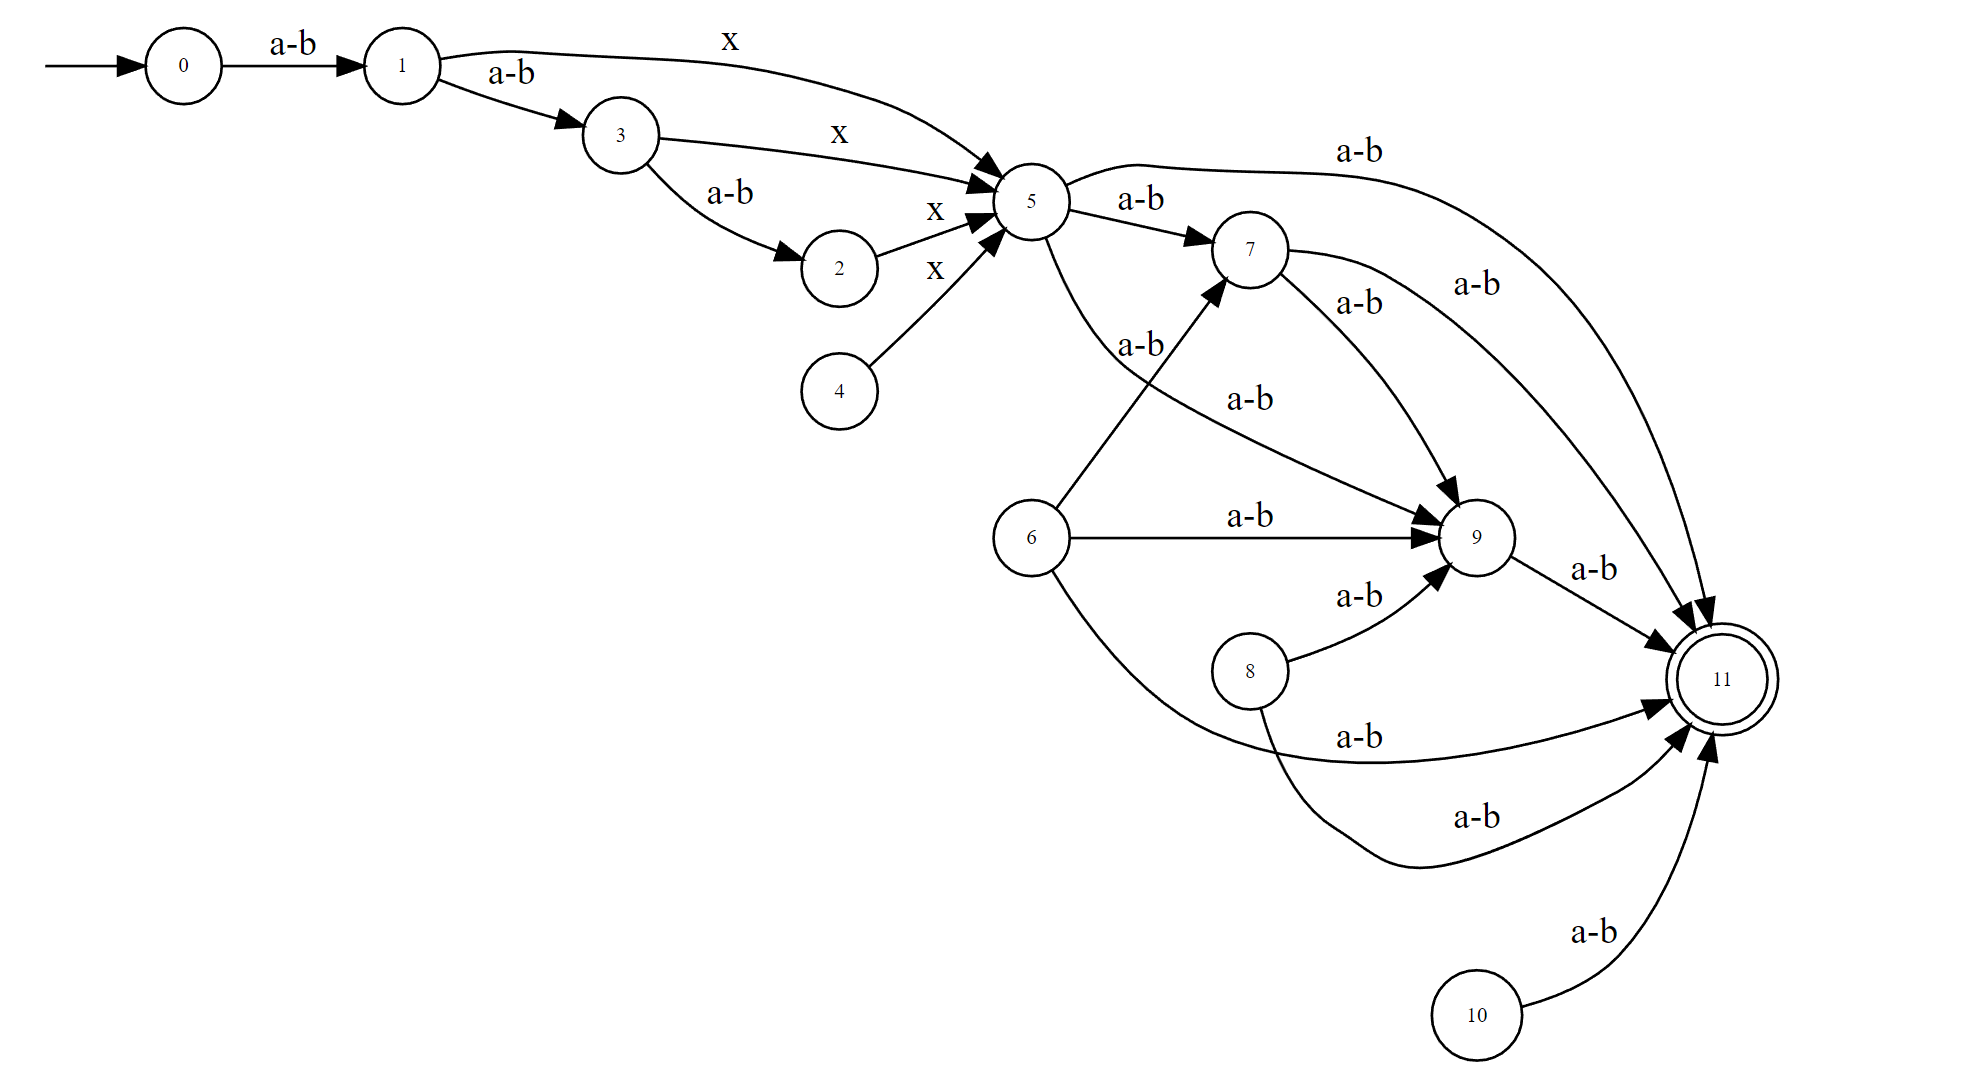
---
Migrated from [LUCENE-7921](https://issues.apache.org/jira/browse/LUCENE-7921) by Thomas Poppe
Attachments: [capture-7.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-7921/capture-7.png), [capture-8.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-7921/capture-8.png)
Contributor guide
Research direction
Start at org.apache.lucene.util.automaton.RegExp#toAutomaton() and reproduce the two regular-expression examples from the issue. Compare their determinization behavior, state counts, transitions, memory, and CPU. Done means the equivalent repetition is handled more efficiently without exceeding the default determinized-state limit.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- search
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100