Duplicate strings in FieldInfo#attributes contribute significantly to heap usage at scale [LUCENE-10677]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 88
Description
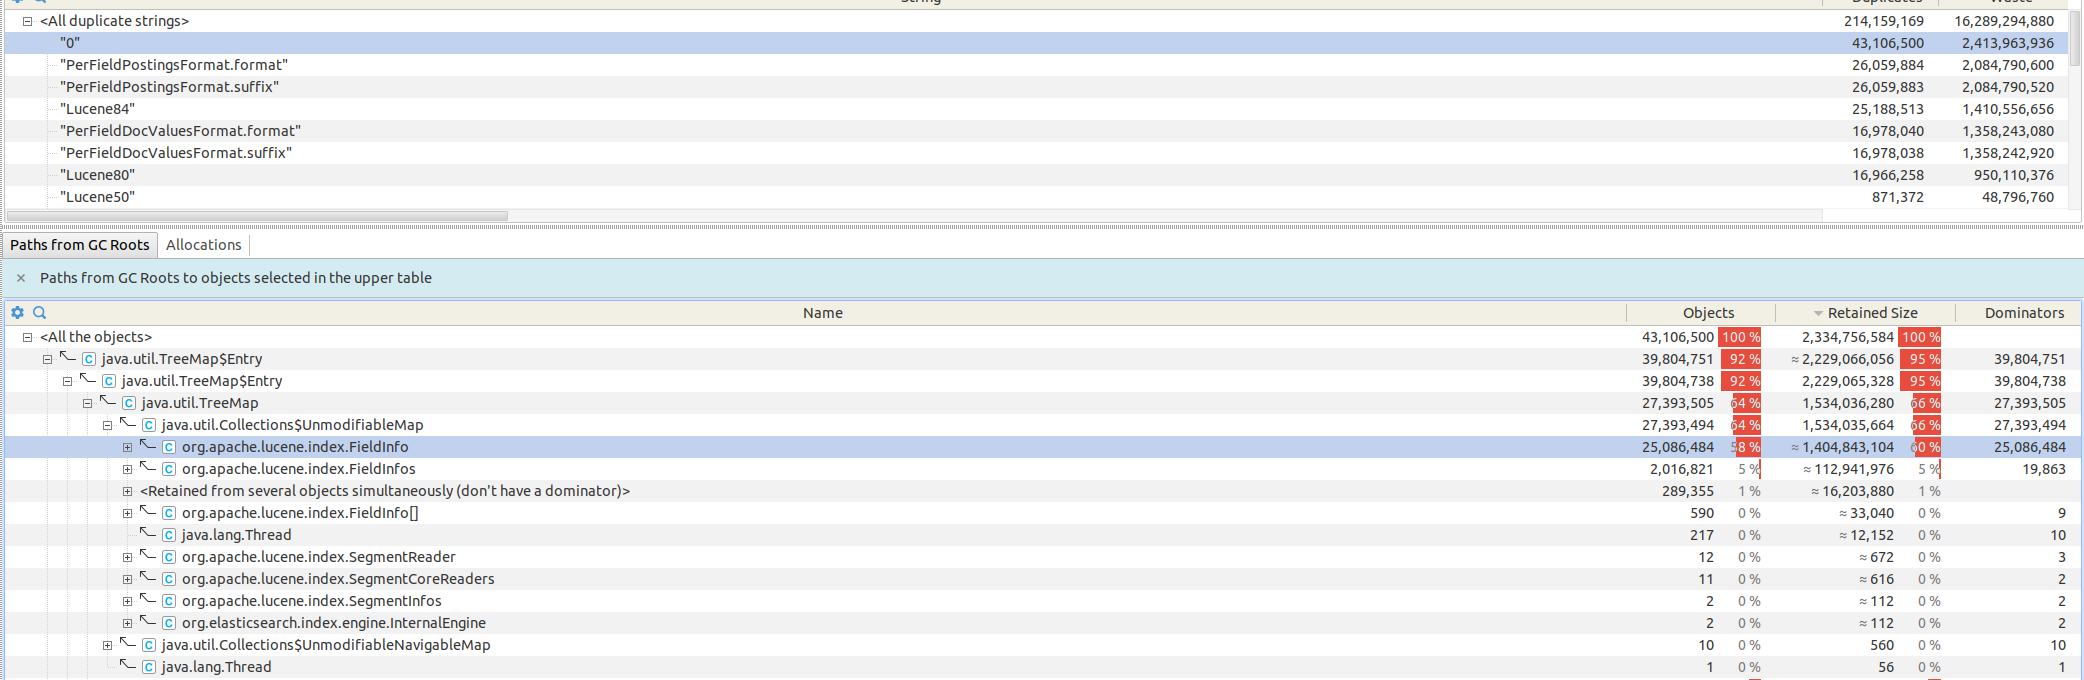
This has the same origin as issue #11711 . Running a single process with thousands of fields across many indexes will lead to a lot of duplicate strings retained as keys and values in the `attributes` map. This can amount to GBs of heap for thousands of fields across a few thousand segments. The strings in the below heap dump analysis account for more than half (roughly 2/3 and the field names are somewhat unusually long in this example) the duplicate strings from `FieldInfo` instances.
If we could deduplicate theses obvious known strings when reading `FieldInfo` we could save GBs of heap for use cases like this.
---
Migrated from [LUCENE-10677](https://issues.apache.org/jira/browse/LUCENE-10677) by Armin Braun (@original-brownbear), updated Aug 10 2022
Attachments: [lucene_duplicate_fields.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-10677/lucene_duplicate_fields.png)
Contributor guide
Research direction
Start by reading FieldInfo#attributes and the related issue #11711, then trace how FieldInfo reads and retains attribute keys and values. Use the heap-dump analysis in the issue as context. Done means the known duplicate strings are deduplicated during FieldInfo reading and the retained heap is reduced for many fields and segments.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- search
- Issue type
- Refactor
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100