Error condition used to judge whether hits are sparse in StringValueFacetCounts [LUCENE-10281]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 88
Description
Description:
In construction method StringValueFacetCounts(StringDocValuesReaderState state, FacetsCollector facetsCollector), if facetsCollector was provided, a condition of **(totalHits < totalDocs / 10)** used to judge whether using IntIntHashMap which means sparse to store term ord and count 。
But per totalHits doesn't means it must be containing SSDV , and so is totalDocs. so the right calculation should be **( totalHits has SSDV) / (totalDocs has SSDV) .( totalDocs has SSDV)** was easy to get by SortedSetDocValues#getValueCount(), **totalHits has SSDV** is hard to get because we can only read index by docId provided by FacetsCollector, but the way of getting **totalHits has SSDV** is slow and redundant.
Solution:
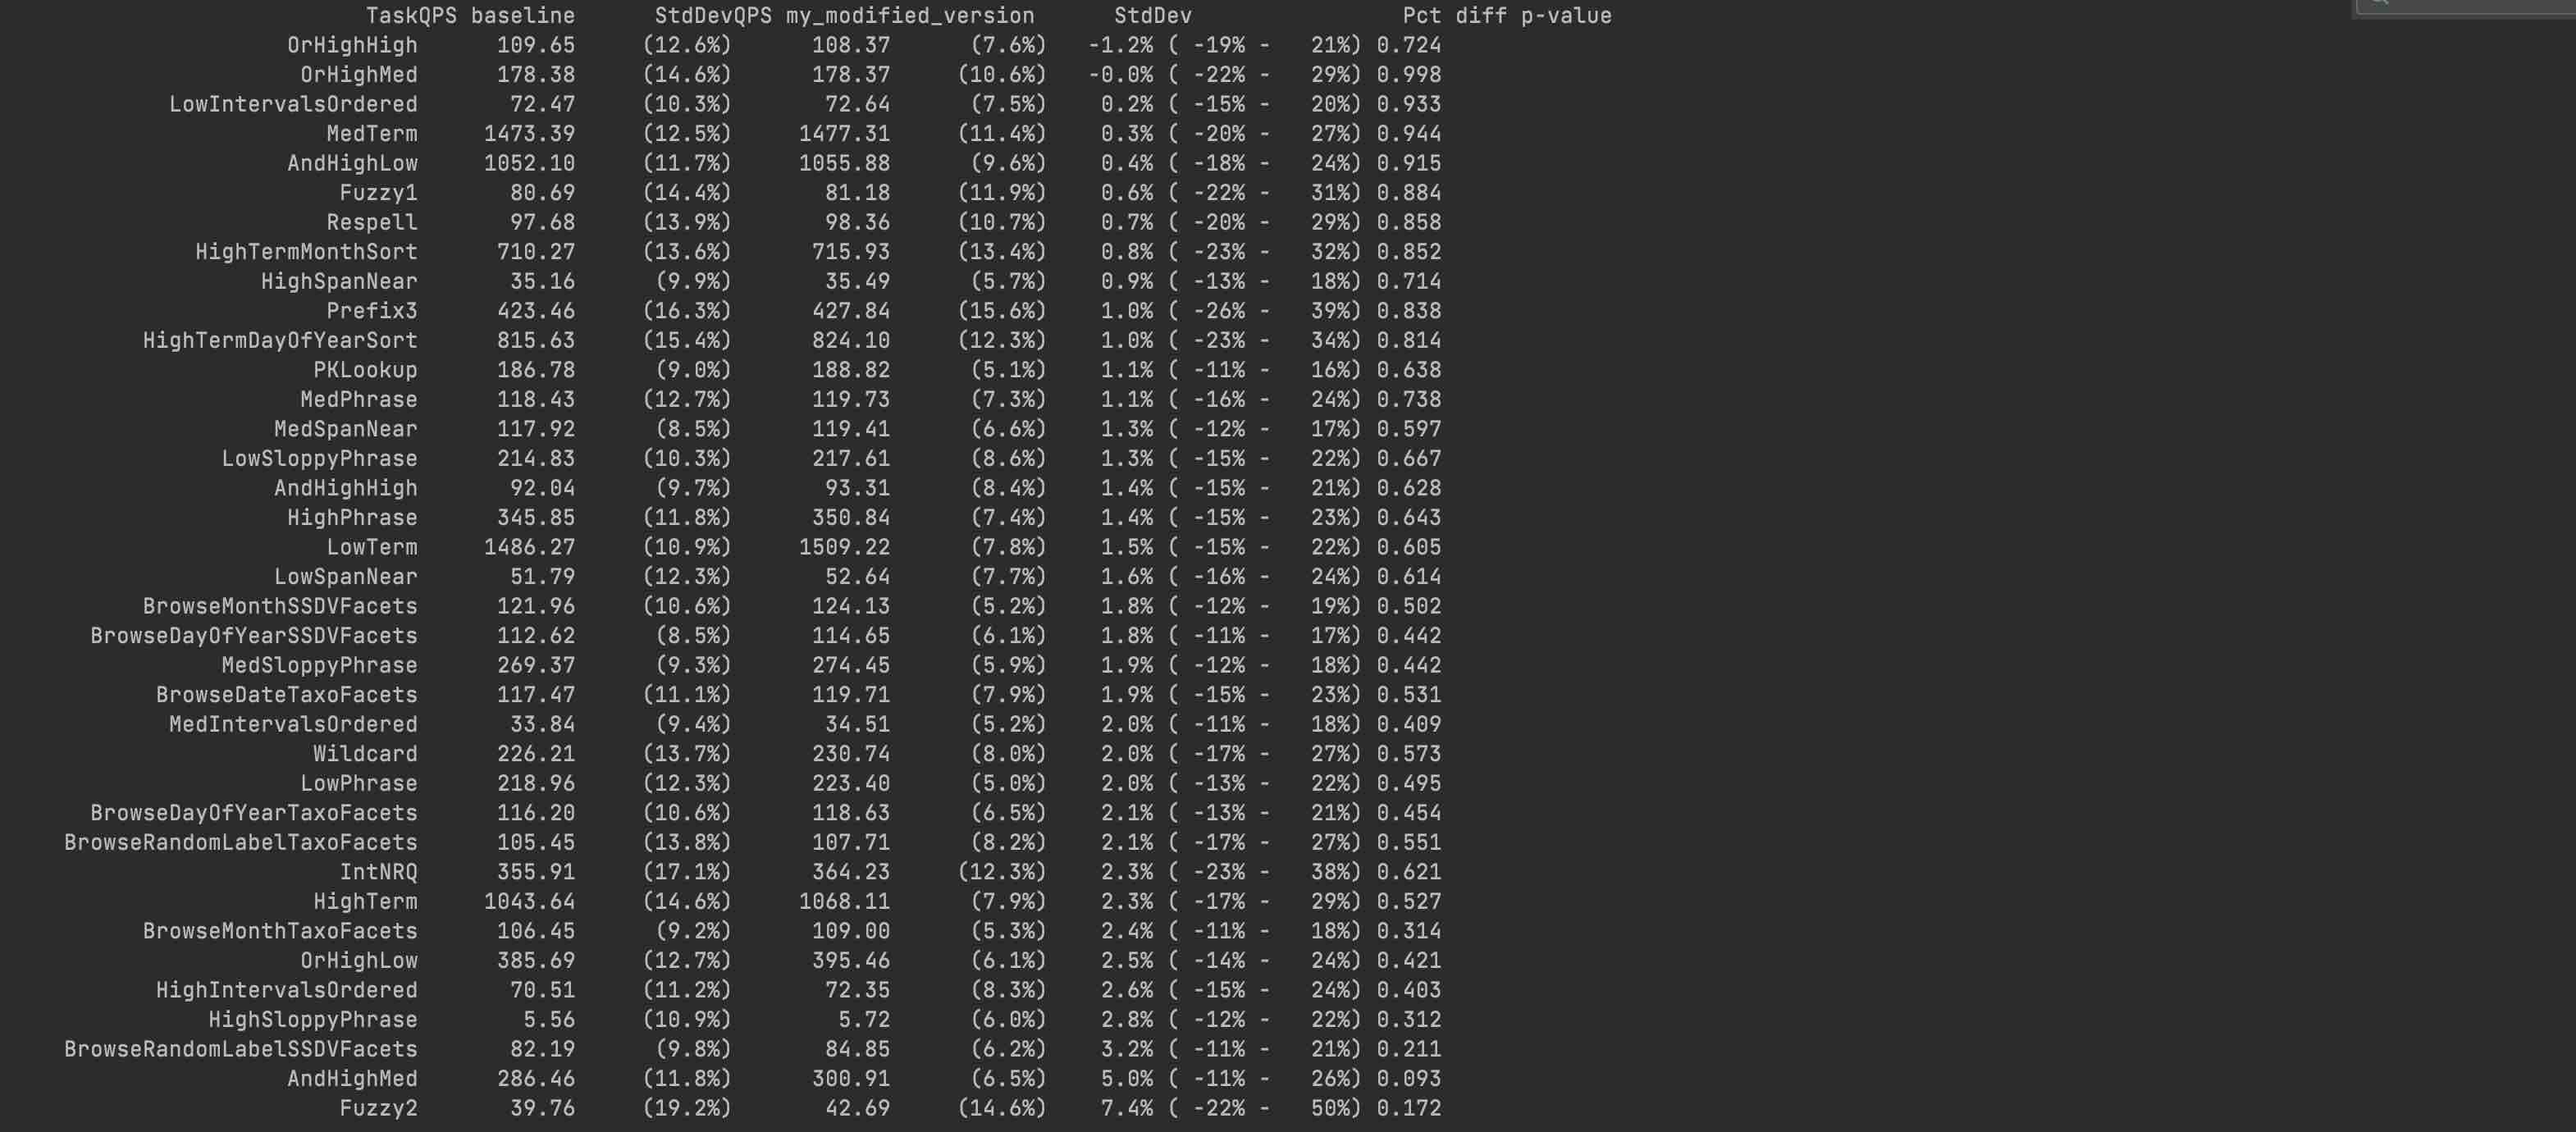
if we don't wanna to break the old logic that using denseCounts while cardinality < 1024 and using IntIntHashMap while 10% threshold and using denseCounts while the rest of the case, then we could still use denseCounts if cardinality < 1024, if not , using IntIntHashMap. when 10% of the unique term collected,then change to use denseCounts.
---
Migrated from [LUCENE-10281](https://issues.apache.org/jira/browse/LUCENE-10281) by Lu Xugang (@LuXugang), updated May 15 2022
Attachments: [1.jpg](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-10281/1.jpg)
Pull requests: https://github.com/apache/lucene/pull/511
Contributor guide
Research direction
Start by locating StringValueFacetCounts and its StringValueFacetCounts(StringDocValuesReaderState state, FacetsCollector facetsCollector) constructor, then inspect how FacetsCollector hits and SortedSetDocValues cardinality affect the sparse-count choice. Done means the sparse-versus-dense decision uses the collected unique-term threshold described in the issue without unnecessary SSDV scanning, with existing facet-count behavior preserved.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- backend, search
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100