large indexing slowdown after increasing HNSW beam width [LUCENE-10128]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 12h
- Merged PRs (30d)
- 86
Description
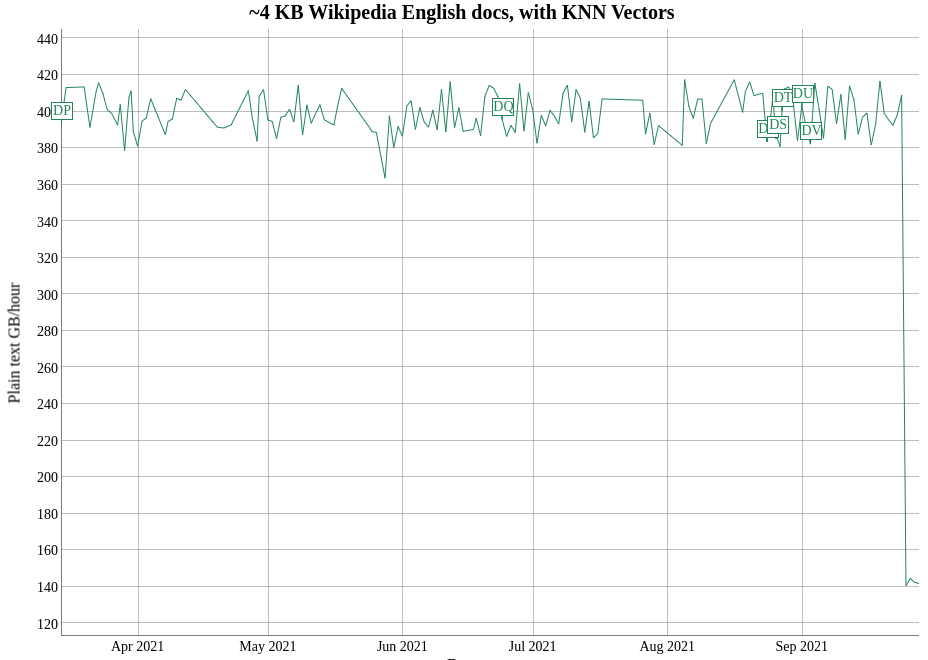
Just opening a ticket in case there is anything we could/should do about it. Looking at Mike's nightly benchmarks, I see a large (like 4x) drop in indexing perf with vectors after #11146.
There's some new stuff in the top CPU offenders:
```
PERCENT CPU SAMPLES STACK
19.93% 821395 org.apache.lucene.util.VectorUtil#dotProduct()
13.80% 568786 org.apache.lucene.util.LongHeap#downHeap()
11.06% 455711 org.apache.lucene.codecs.KnnVectorsWriter$VectorValuesMerger$MergerRandomAccess#vectorValue()
9.84% 405678 org.apache.lucene.util.LongHeap#upHeap()
6.72% 276931 java.util.concurrent.atomic.AtomicLong#get()
5.30% 218564 org.apache.lucene.util.LongHeap$2#lessThan()
2.69% 110872 java.util.Arrays#binarySearch0()
2.58% 106294 org.apache.lucene.util.hnsw.HnswGraph#search()
1.90% 78254 org.apache.lucene.util.LongHeap#push()
```
compared to before where the profile stacks looked like this:
```
PERCENT CPU SAMPLES STACK
13.58% 171575 org.apache.lucene.util.VectorUtil#dotProduct()
10.13% 127904 org.apache.lucene.util.LongHeap#downHeap()
9.84% 124257 org.apache.lucene.util.LongHeap#upHeap()
6.26% 79125 java.util.ArrayList#elementData()
4.34% 54831 java.util.Random#nextInt()
3.98% 50255 org.apache.lucene.util.BytesRefHash#equals()
3.69% 46594 org.apache.lucene.util.ByteBlockPool#allocSlice()
2.62% 33118 org.apache.lucene.util.BytesRefHash#findHash()
2.24% 28275 org.apache.lucene.analysis.standard.StandardTokenizerImpl#getNextToken()
2.14% 27033 org.apache.lucene.analysis.standard.StandardTokenizer#incrementToken()
```
At a glance, it seems to me that although some perf differences should be expected, merging itself may have become more costly. Maybe there is some stuff we can optimize about it.
---
Migrated from [LUCENE-10128](https://issues.apache.org/jira/browse/LUCENE-10128) by Robert Muir (@rmuir), updated Oct 02 2021
Attachments: [LUCENE-10128_remove_sparse_fixed_bitset_reflection.patch](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-10128/LUCENE-10128_remove_sparse_fixed_bitset_reflection.patch), [Screen_Shot_2021-09-28_at_09.10.15.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-10128/Screen_Shot_2021-09-28_at_09.10.15.png)
Contributor guide
Research direction
Start by reproducing the vector indexing benchmark before and after #11146, then inspect the profiling hotspots in HnswGraph#search, VectorValuesMerger, VectorUtil, and LongHeap. Compare the attached profiles and determine whether merging accounts for the regression. Done means identifying and validating an optimization that improves the reported indexing slowdown.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- search
- Issue type
- Bug
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100