Lucene 8 causing app server threads to hang due to high rate of network usage [LUCENE-9961]
- Dominant language
- Java
- Stars
- 3.6k
- Forks
- 1.4k
- Avg merge
- 2d 11h
- Merged PRs (30d)
- 88
Description
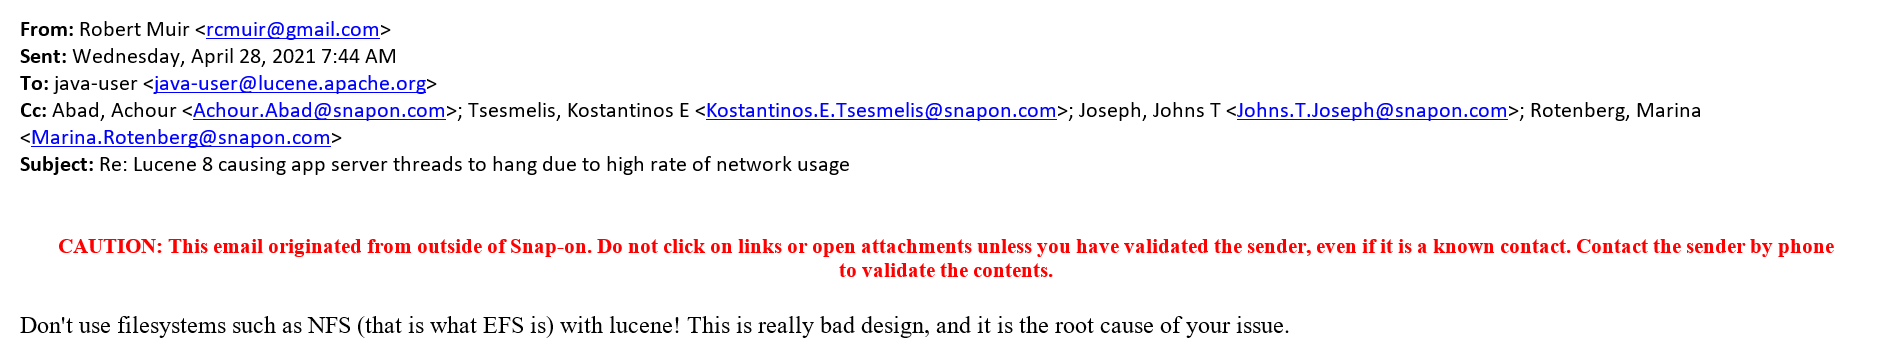
**Issue**: Lucene 8 causing app server threads to hang due to high rate of network usage.
**Further details**: Recently we migrated from Lucene 7.5.0 to Lucene 8.6.3 and we have encountered severe performance issues after this upgrade. Our Lucene index has multilingual terms, is large in size, and is hosted on a network file storage (EFS at AWS). Our Lucene queries construct a lot of Boolean term queries, and we suspect the off-heap FST introduced with Lucene 8 could be the root cause. The specific issue we are facing after the Lucene upgrade is that, when a user searches for any given term, the tomcat server thread will hang while reading the bytes from an unexpectedly huge inbound flow of data from the Lucene Index on network storage. We have seen inbound data flows ranging from 5% up to 45% of the total index size for a single search, primarily when searching for a term in a different language. This issue does not occur with Lucene 7.
Here is a typical call stack highlighting the point of contention in the Tomcat threads when we encounter this performance issue:
org.apache.lucene.search.IndexSearcher.search(IndexSearcher.java:432)
org.apache.lucene.search.IndexSearcher.searchAfter(IndexSearcher.java:421)
org.apache.lucene.search.IndexSearcher.search(IndexSearcher.java:574)
org.apache.lucene.search.IndexSearcher.search(IndexSearcher.java:445)
org.apache.lucene.search.IndexSearcher.search(IndexSearcher.java:658)
org.apache.lucene.search.BooleanWeight.bulkScorer(BooleanWeight.java:330)
org.apache.lucene.search.Weight.bulkScorer(Weight.java:181)
org.apache.lucene.search.BooleanWeight.scorer(BooleanWeight.java:344)
org.apache.lucene.search.BooleanWeight.scorerSupplier(BooleanWeight.java:379)
org.apache.lucene.search.BooleanWeight.scorerSupplier(BooleanWeight.java:379)
org.apache.lucene.search.BooleanWeight.scorerSupplier(BooleanWeight.java:379)
org.apache.lucene.search.Weight.scorerSupplier(Weight.java:147)
org.apache.lucene.search.TermQuery$TermWeight.scorer(TermQuery.java:115)
org.apache.lucene.codecs.blocktree.SegmentTermsEnum.impacts(SegmentTermsEnum.java:1017)
org.apache.lucene.codecs.lucene84.Lucene84PostingsReader.impacts(Lucene84PostingsReader.java:272)
org.apache.lucene.codecs.lucene84.Lucene84PostingsReader$BlockImpactsDocsEnum.<init>(Lucene84PostingsReader.java:1061)
org.apache.lucene.codecs.lucene84.Lucene84SkipReader.init(Lucene84SkipReader.java:103)
org.apache.lucene.codecs.MultiLevelSkipListReader.init(MultiLevelSkipListReader.java:208)
org.apache.lucene.codecs.MultiLevelSkipListReader.loadSkipLevels(MultiLevelSkipListReader.java:229)
org.apache.lucene.store.DataInput.readVLong(DataInput.java:190)
org.apache.lucene.store.DataInput.readVLong(DataInput.java:205)
org.apache.lucene.store.ByteBufferIndexInput.readByte(ByteBufferIndexInput.java:80)
org.apache.lucene.store.ByteBufferGuard.getByte(ByteBufferGuard.java:99)
When researching found the LUCENE JIRA #9681 (which is referenced in section ‘Moving the terms dictionary off-heap’). Would this help the issue?
Please advise.
---
Migrated from [LUCENE-9961](https://issues.apache.org/jira/browse/LUCENE-9961) by Kathleen Hilston
Attachments: [image-2021-05-17-10-47-42-245.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-9961/image-2021-05-17-10-47-42-245.png), [image-2021-05-17-10-48-35-739.png](https://apache.github.io/lucene-jira-archive/attachments/LUCENE-9961/image-2021-05-17-10-48-35-739.png)
Contributor guide
Research direction
Start with the reported stack through IndexSearcher, BooleanWeight, Lucene84PostingsReader, and ByteBufferIndexInput, then compare the Lucene 7.5.0 and 8.6.3 behavior for multilingual Boolean term queries on AWS EFS. The issue is complete only when the cause of the excessive network reads is identified and a concrete recommendation or fix is established.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- aws, java
- Domain
- backend, performance, search
- Issue type
- Bug
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100