[SUPPORT]Spark on K8s can not stop pod by setting set hoodie.write.concurrency.mode=optimistic_concurrency_control;
- Dominant language
- Java
- Stars
- 6.2k
- Forks
- 2.5k
- Avg merge
- 2d 8h
- Merged PRs (30d)
- 111
Description
Hello, I have meet some error for **spark-on-k8s-operator**.
My hudi version is 0.13,spark version is 3.3.2
I find the pod logs show the task is Successfully,but pod status is still Running?
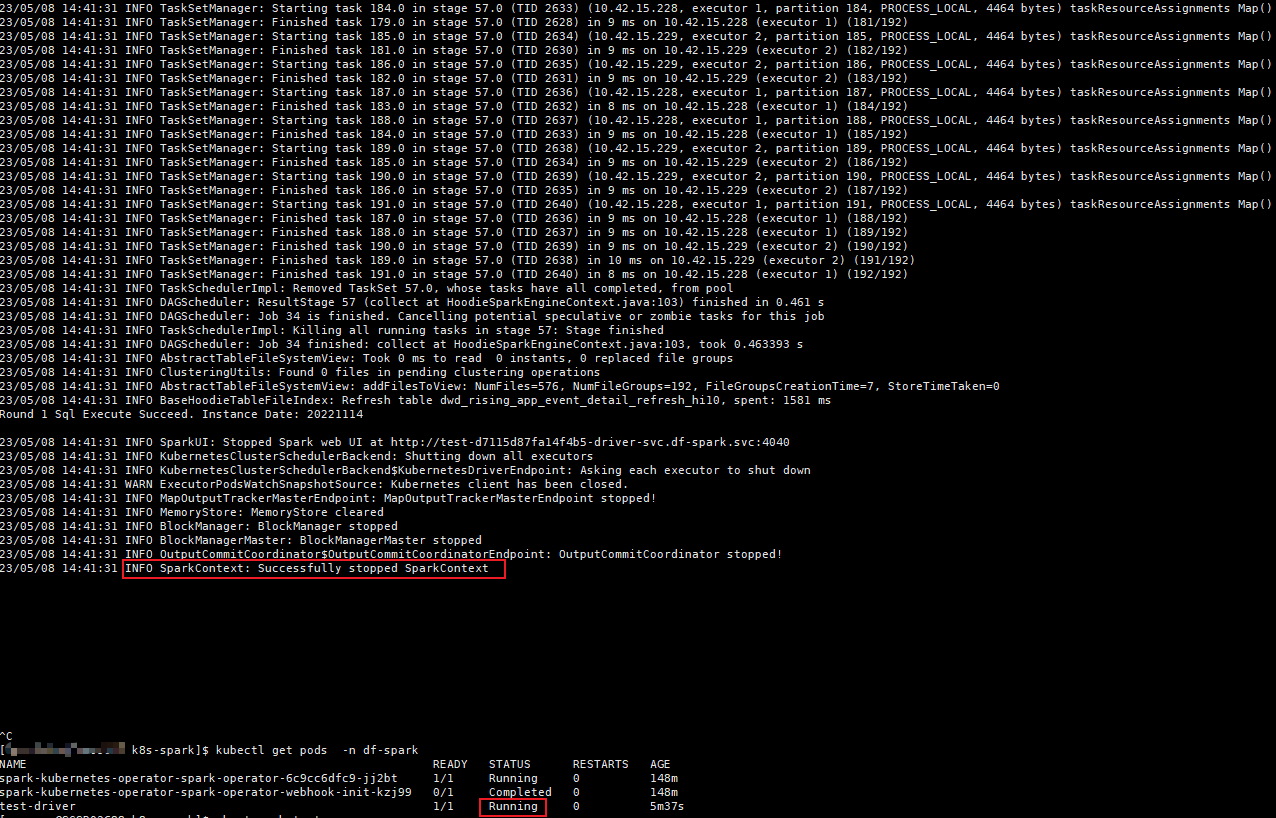
my sql setting is
`set spark.sql.shuffle.partitions=600;
set hoodie.insert.shuffle.parallelism=600;
set hoodie.upsert.shuffle.parallelism=600;
set hoodie.write.concurrency.mode=optimistic_concurrency_control;
set hoodie.cleaner.policy.failed.writes=LAZY;
set hoodie.write.lock.provider=org.apache.hudi.hive.transaction.lock.HiveMetastoreBasedLockProvider;
set hoodie.write.lock.hivemetastore.database=zone_test;
set hoodie.write.lock.hivemetastore.table=dwd_event_detail_refresh_hi5;`
if my sql setting is only
`set spark.sql.shuffle.partitions=600;
set hoodie.insert.shuffle.parallelism=600;
set hoodie.upsert.shuffle.parallelism=600;`
it can worker stop normal.
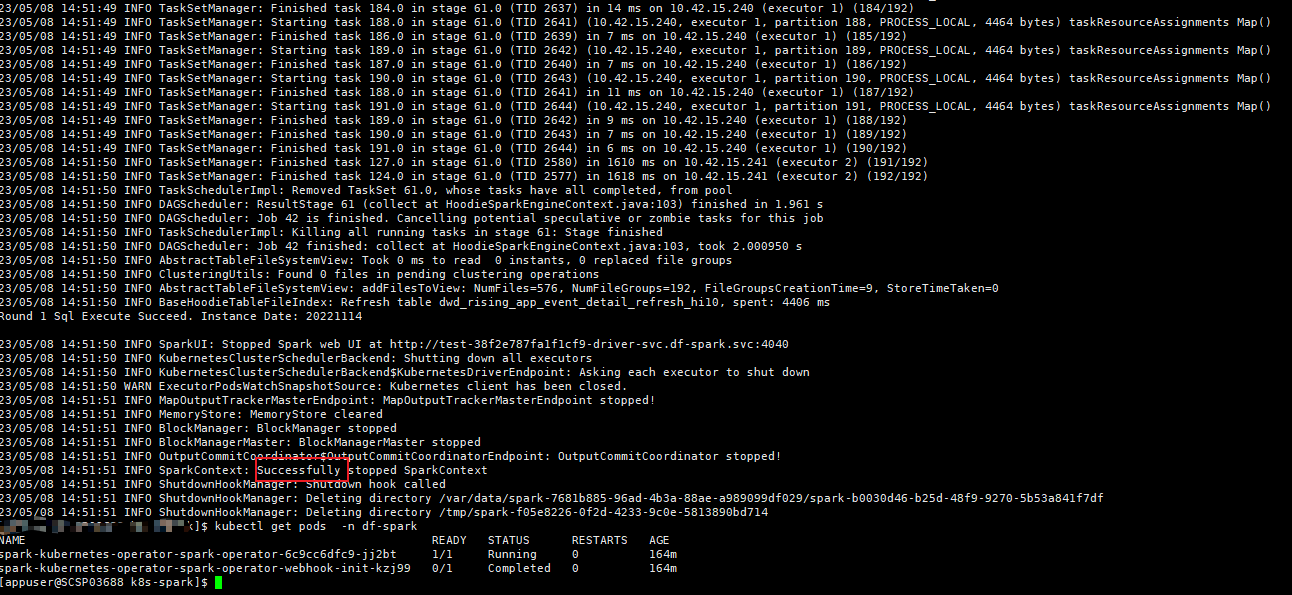
Does hudi something settings conf can't use on k8s?
Contributor guide
No contributing guide indexed for this repository
Research direction
Start with the spark-on-k8s-operator pod logs and compare the two SQL configuration sets, using the reported Hudi 0.13 and Spark 3.3.2 versions. Reproduce the case with optimistic concurrency control and the Hive metastore lock settings; done means explaining why the pod remains Running or confirming the relevant configuration limitation.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- kubernetes, sql
- Domain
- data-engineering, devops, distributed-systems
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100