[SUPPORT] Getting error when writing into COW HUDI table if schema changed (datatype changed / column dropped)
- Dominant language
- Java
- Stars
- 6.2k
- Forks
- 2.5k
- Avg merge
- 2d 8h
- Merged PRs (30d)
- 111
Description
**Describe the problem you faced**
We have a hudi table created in 2022, and we did column change by adding some columns.
Now when we do DELETE on whole partitions, it will get error
**To Reproduce**
Steps to reproduce the behavior:
1. We have old data ::
>>> old_df = spark.read.parquet("s3://our-bucket/data-lake-hudi/ods_meeting_mmr_log/ods_mmr_conf_join/cluster=aw1/year=2022/month=11/day=30")
>>> old_df.printSchema()
root
|-- _hoodie_commit_time: string (nullable = true)
|-- _hoodie_commit_seqno: string (nullable = true)
|-- _hoodie_record_key: string (nullable = true)
|-- _hoodie_partition_path: string (nullable = true)
|-- _hoodie_file_name: string (nullable = true)
|-- _hoodie_is_deleted: boolean (nullable = true)
|-- account_id: string (nullable = true)
|-- cluster: string (nullable = true)
|-- day: string (nullable = true)
|-- error_fields: string (nullable = true)
|-- host_name: string (nullable = true)
|-- instance_id: string (nullable = true)
|-- log_time: string (nullable = true)
|-- meeting_uuid: string (nullable = true)
|-- month: string (nullable = true)
|-- region: string (nullable = true)
|-- rowkey: string (nullable = true)
|-- year: string (nullable = true)
... some common fields ...
**|-- rest_fields: string (nullable = true)**
2. and we have new fields in 2023
>>> new_df = spark.read.parquet("s3://our-bucket/data-lake-hudi/ods_meeting_mmr_log/ods_mmr_conf_join/cluster=aw1/year=2023/month=04/day=16")
>>> new_df.printSchema()
root
|-- _hoodie_commit_time: string (nullable = true)
|-- _hoodie_commit_seqno: string (nullable = true)
|-- _hoodie_record_key: string (nullable = true)
|-- _hoodie_partition_path: string (nullable = true)
|-- _hoodie_file_name: string (nullable = true)
|-- _hoodie_is_deleted: boolean (nullable = true)
|-- account_id: string (nullable = true)
|-- cluster: string (nullable = true)
|-- day: string (nullable = true)
|-- error_fields: string (nullable = true)
|-- host_name: string (nullable = true)
|-- instance_id: string (nullable = true)
|-- log_time: string (nullable = true)
|-- meeting_uuid: string (nullable = true)
|-- month: string (nullable = true)
|-- region: string (nullable = true)
|-- rowkey: string (nullable = true)
|-- year: string (nullable = true)
... some common fields ...
**|-- customer_key: string (nullable = true)
|-- phone_id: long (nullable = true)
|-- bind_number: long (nullable = true)
|-- tracking_id: string (nullable = true)
|-- reg_user_id: string (nullable = true)
|-- user_sn: string (nullable = true)
|-- gateways: string (nullable = true)
|-- jid: string (nullable = true)
|-- options2: string (nullable = true)
|-- attendee_option: long (nullable = true)
|-- is_user_failover: long (nullable = true)
|-- attendee_account_id: string (nullable = true)
|-- token_uuid: string (nullable = true)
|-- restrict_join_status_sharing: long (nullable = true)
|-- rest_fields: string (nullable = true)**
3.
when we do DELETE operation by these config:
"hoodie.fail.on.timeline.archiving": "false",
"hoodie.datasource.write.table.type": "COPY_ON_WRITE",
"hoodie.datasource.write.hive_style_partitioning": "true",
"hoodie.datasource.write.keygenerator.class": "org.apache.hudi.keygen.CustomKeyGenerator",
"hoodie.datasource.hive_sync.enable": "false",
"hoodie.archive.automatic": "false",
"hoodie.metadata.enable": "false",
"hoodie.metadata.enable.full.scan.log.files": "false",
"hoodie.index.type": "SIMPLE",
"hoodie.embed.timeline.server": "false",
"hoodie.avro.schema.external.transformation": "true",
"hoodie.schema.on.read.enable": "true",
"hoodie.datasource.write.reconcile.schema": "true"
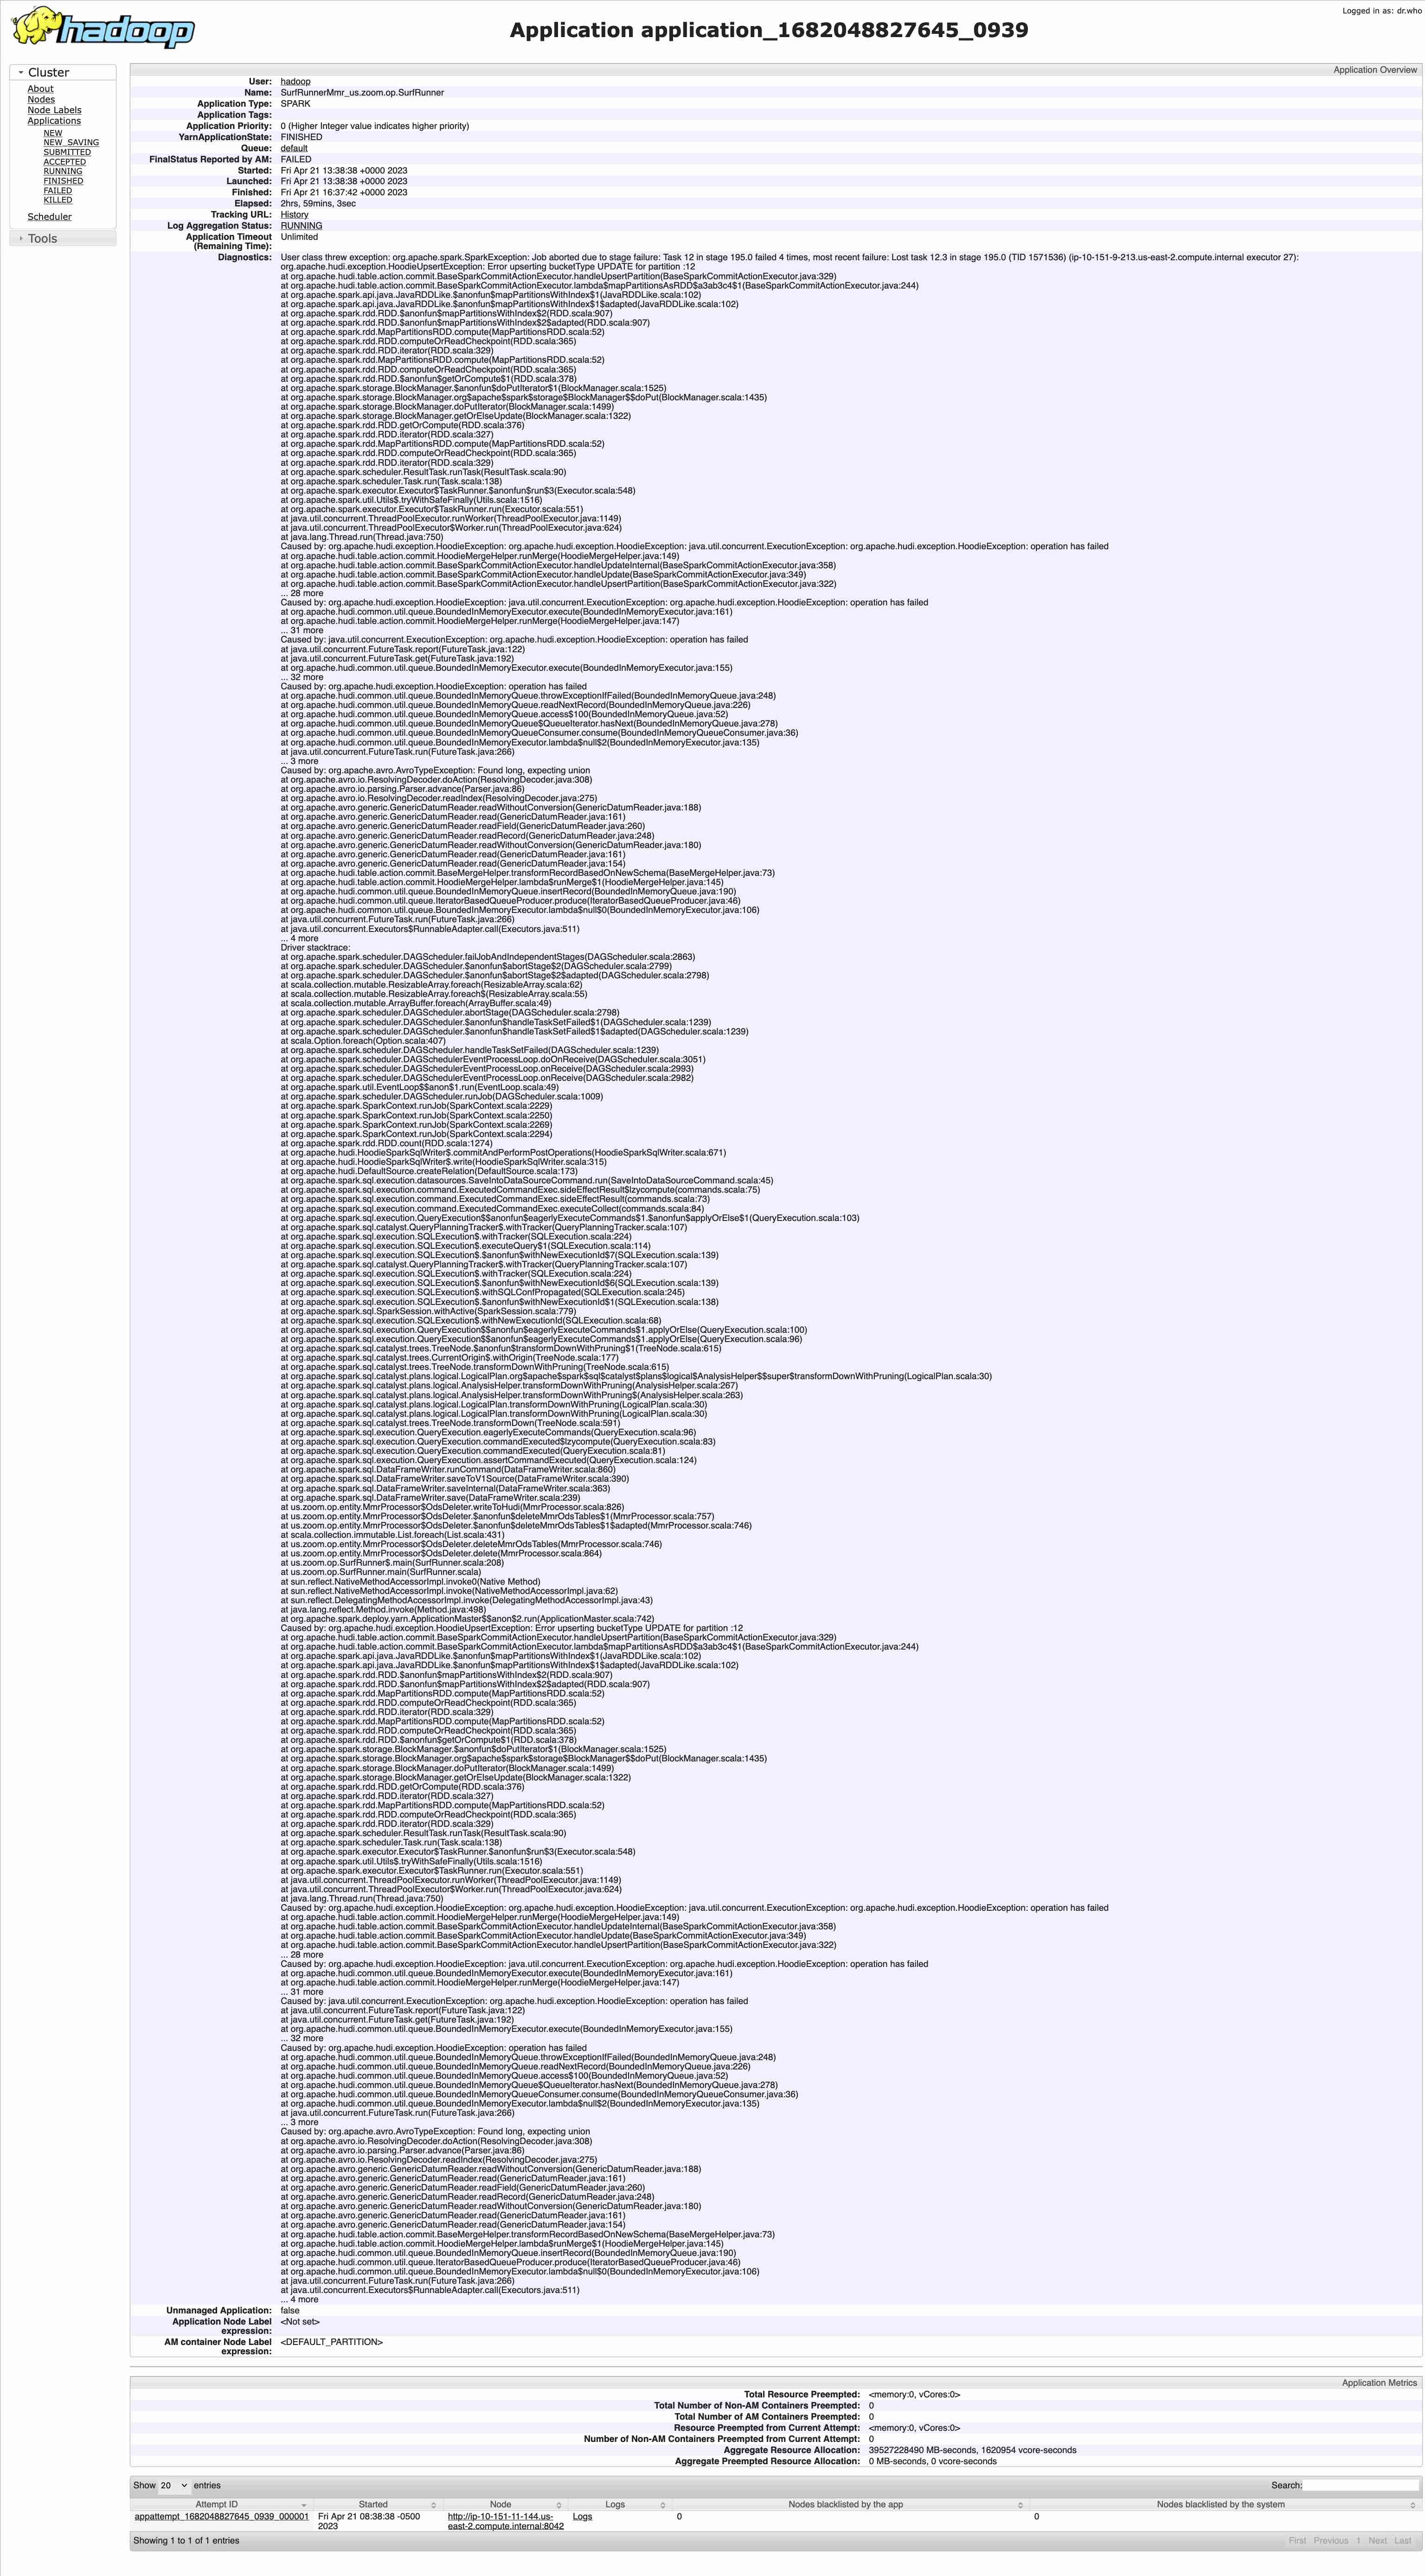
4. we got the error :
AvroTypeException: Found long, expecting union
**Environment Description**
* Hudi version : 0.11.1
* Spark version :
* Storage (HDFS/S3/GCS..) : S3
* Running on Docker? (yes/no) : no
Contributor guide
No contributing guide indexed for this repository
Research direction
No source files or tests are named. Start by reproducing the partition-wide DELETE with the reported Hudi 0.11.1, Spark, and S3 setup and schema differences; done means the DELETE no longer raises AvroTypeException for changed or dropped columns.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- aws, spark
- Domain
- data-engineering, distributed-systems
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 30/100