[SUPPORT]hudi-0.13 Using spark to write into Hudi is too slow
- Dominant language
- Java
- Stars
- 6.2k
- Forks
- 2.5k
- Avg merge
- 2d 4h
- Merged PRs (30d)
- 112
Description
**Describe the problem you faced**
I write a batch of data to a copy-on-write (COW) format Hudi table every 5 minutes, with roughly tens of thousands of records. However, I found that the writing process is very slow. From the Spark stage page, I can see that the specific write task takes 2-3 minutes to process just a dozen records. I don't understand the reason behind this and don't know how to troubleshoot the cause of the slow write.
In the data being written, 80% of the data is new, while the remaining 20% of the data will update the data in the table.
**Environment Description**
* Hudi version : 0.13
* Spark version : 3.31
* Hive version : 3.1.1
* Hadoop version : 3.1.1
* Storage (HDFS/S3/GCS..) : HDFS
* Running on Docker? (yes/no) : no
**Additional context**
spark config:
val spark = SparkSession
.builder()
.config("spark.debug.maxToStringFields", "500")
.config("spark.sql.debug.maxToStringFields", "500")
.config("spark.sql.sources.partitionOverwriteMode", "dynamic")
.config("hive.exec.dynamic.partition", true)
.config("hive.exec.dynamic.partition.mode", "nonstrict")
.enableHiveSupport()
.getOrCreate()
hoodie.properties
hoodie.table.timeline.timezone=LOCAL
hoodie.table.keygenerator.class=org.apache.hudi.keygen.ComplexKeyGenerator
hoodie.table.precombine.field=sort_key
hoodie.table.version=5
hoodie.database.name=
hoodie.datasource.write.hive_style_partitioning=true
hoodie.table.checksum=2356712026
hoodie.partition.metafile.use.base.format=false
hoodie.table.cdc.enabled=false
hoodie.archivelog.folder=archived
hoodie.table.name=dwd_foo_6_order_real_batch
hoodie.populate.meta.fields=true
hoodie.table.type=COPY_ON_WRITE
hoodie.datasource.write.partitionpath.urlencode=false
hoodie.table.base.file.format=PARQUET
hoodie.datasource.write.drop.partition.columns=false
hoodie.table.metadata.partitions=files
hoodie.timeline.layout.version=1
hoodie.table.recordkey.fields=order_id
hoodie.table.partition.fields=cdt,data_source

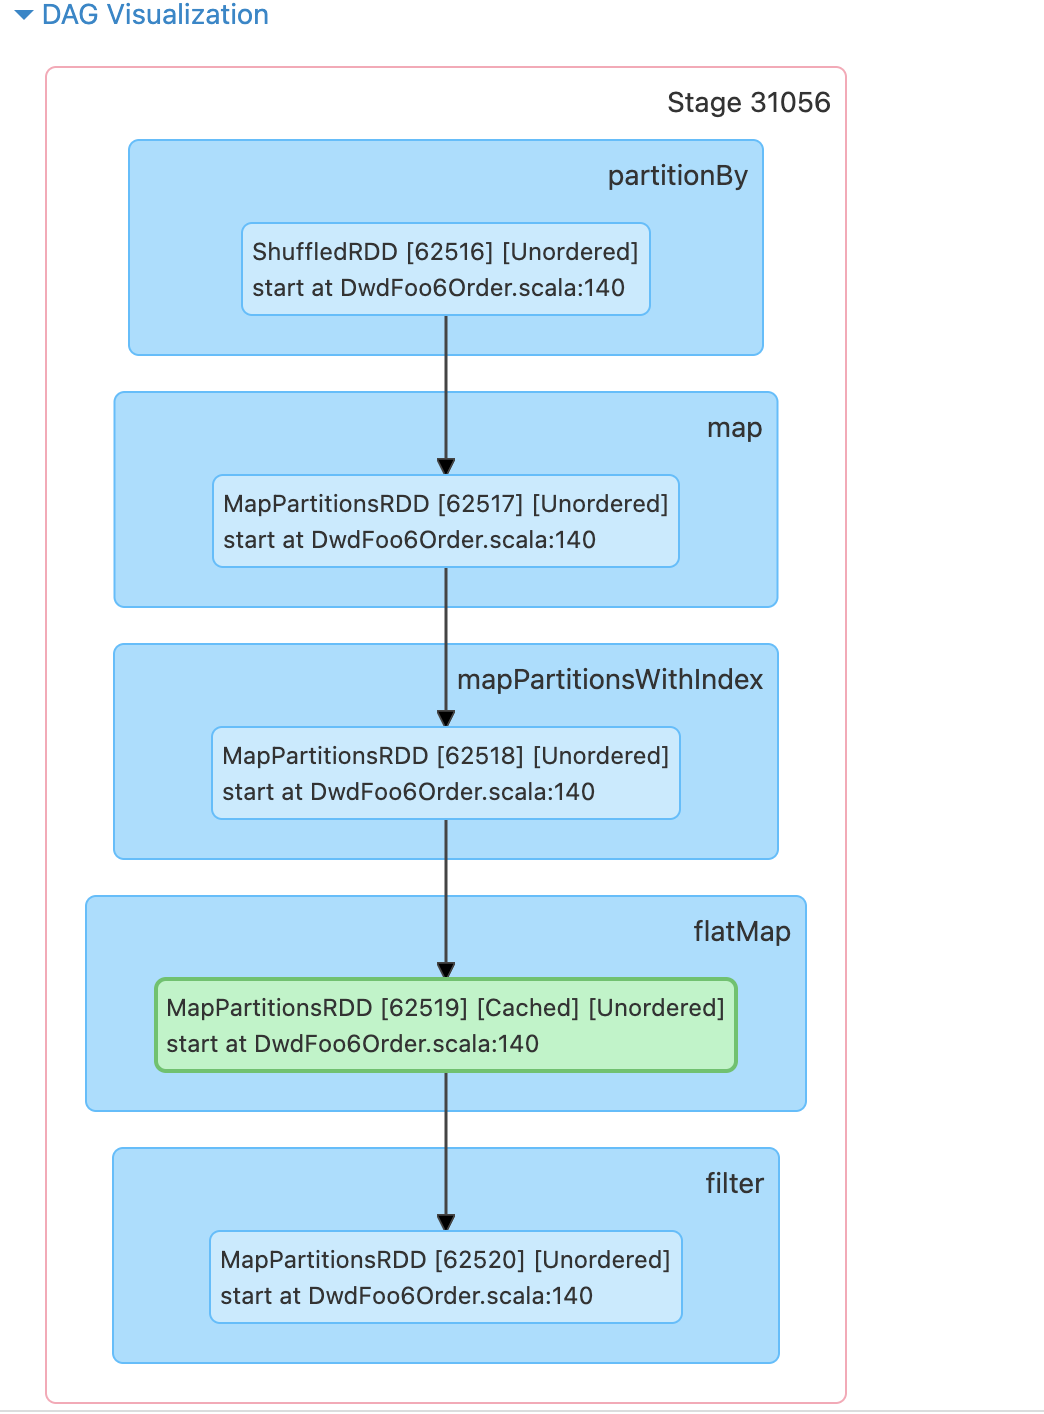
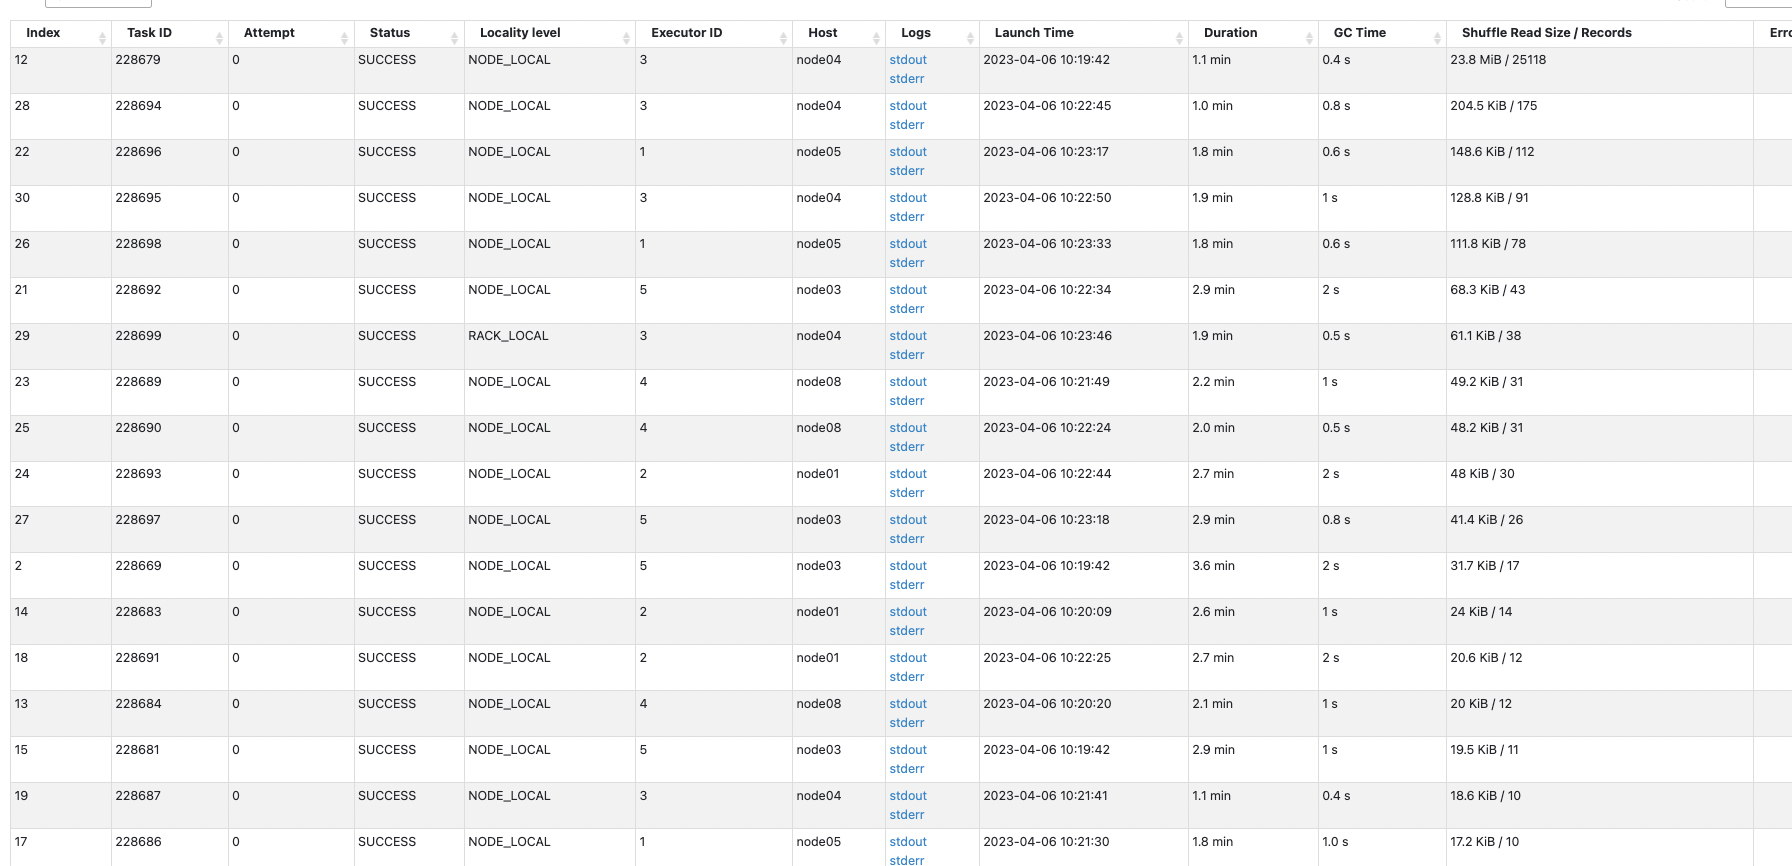
While investigating the metadata under the Hudi path, I found some log information. When rewriting the entire file block (about 128MB), the total upsert time is very long, even if only one record in this file block is upserted, the entire file block needs to be rewritten, which takes about 2 minutes. For smaller file blocks, the rewriting time is shorter.
Is it because writing Parquet files is too time-consuming? However, for rewriting a 128MB Parquet file, a 2-minute duration seems too long. I tested using Spark to read a 128MB Parquet file directly from an HDFS path and then write it to another path, and it also took about 2 minutes. Is there any other way to speed up this writing process? Or is it because my server configuration is too poor?
{
"fileId" : "94b686d9-0af9-4c33-a910-d14085658e31-0",
"path" : "cdt=2023-04-03/data_source=foo6_standard/94b686d9-0af9-4c33-a910-d14085658e31-0_11-45106-340627_20230407143107752.parquet",
"cdcStats" : null,
"prevCommit" : "20230407142144216",
"numWrites" : 301822,
"numDeletes" : 0,
"numUpdateWrites" : 1,
"numInserts" : 0,
"totalWriteBytes" : 108616464,
"totalWriteErrors" : 0,
"tempPath" : null,
"partitionPath" : "cdt=2023-04-03/data_source=foo6_standard",
"totalLogRecords" : 0,
"totalLogFilesCompacted" : 0,
"totalLogSizeCompacted" : 0,
"totalUpdatedRecordsCompacted" : 0,
"totalLogBlocks" : 0,
"totalCorruptLogBlock" : 0,
"totalRollbackBlocks" : 0,
"fileSizeInBytes" : 108616464,
"minEventTime" : null,
"maxEventTime" : null,
"runtimeStats" : {
"totalScanTime" : 0,
"totalUpsertTime" : 126022,
"totalCreateTime" : 0
}
}
{
"fileId" : "da4065f8-28ea-433e-8839-ddb71577355c-0",
"path" : "cdt=2023-03-31/data_source=foo6_standard/da4065f8-28ea-433e-8839-ddb71577355c-0_0-45106-340620_20230407143107752.parquet",
"cdcStats" : null,
"prevCommit" : "20230407142144216",
"numWrites" : 383,
"numDeletes" : 0,
"numUpdateWrites" : 2,
"numInserts" : 0,
"totalWriteBytes" : 718544,
"totalWriteErrors" : 0,
"tempPath" : null,
"partitionPath" : "cdt=2023-03-31/data_source=foo6_standard",
"totalLogRecords" : 0,
"totalLogFilesCompacted" : 0,
"totalLogSizeCompacted" : 0,
"totalUpdatedRecordsCompacted" : 0,
"totalLogBlocks" : 0,
"totalCorruptLogBlock" : 0,
"totalRollbackBlocks" : 0,
"fileSizeInBytes" : 718544,
"minEventTime" : null,
"maxEventTime" : null,
"runtimeStats" : {
"totalScanTime" : 0,
"totalUpsertTime" : 279,
"totalCreateTime" : 0
}
}
Contributor guide
No contributing guide indexed for this repository
Research direction
The report provides Spark configuration, Hudi table properties, stage observations, and write runtime metrics, but names no repository files, tests, or entry points. Start by reproducing the slow COPY_ON_WRITE upsert with the reported Hudi, Spark, Hive, Hadoop, and HDFS versions, then compare the write metrics for large and small Parquet blocks. Done means identifying a supported cause or actionable repository change, with evidence from a focused reproduction or test.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java
- Domain
- data-engineering, performance
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100