[SUPPORT] Hudi Job fails when trying to upsert/insert data due to Executor Process Lost
- Dominant language
- Java
- Stars
- 6.2k
- Forks
- 2.5k
- Avg merge
- 2d 8h
- Merged PRs (30d)
- 111
Description
**Problem Description**
Hi team,
We are trying to construct a Hudi application to run daily (as a batch job) and incrementally update data from existing tables. This is our first time working with Hudi and some issues appear when doing experiments during the deployment. Currently, we have an input data of 11GB divided into 627 parquet files and we are working with two scenarios:
- 100% of inserts
- 100% of updates
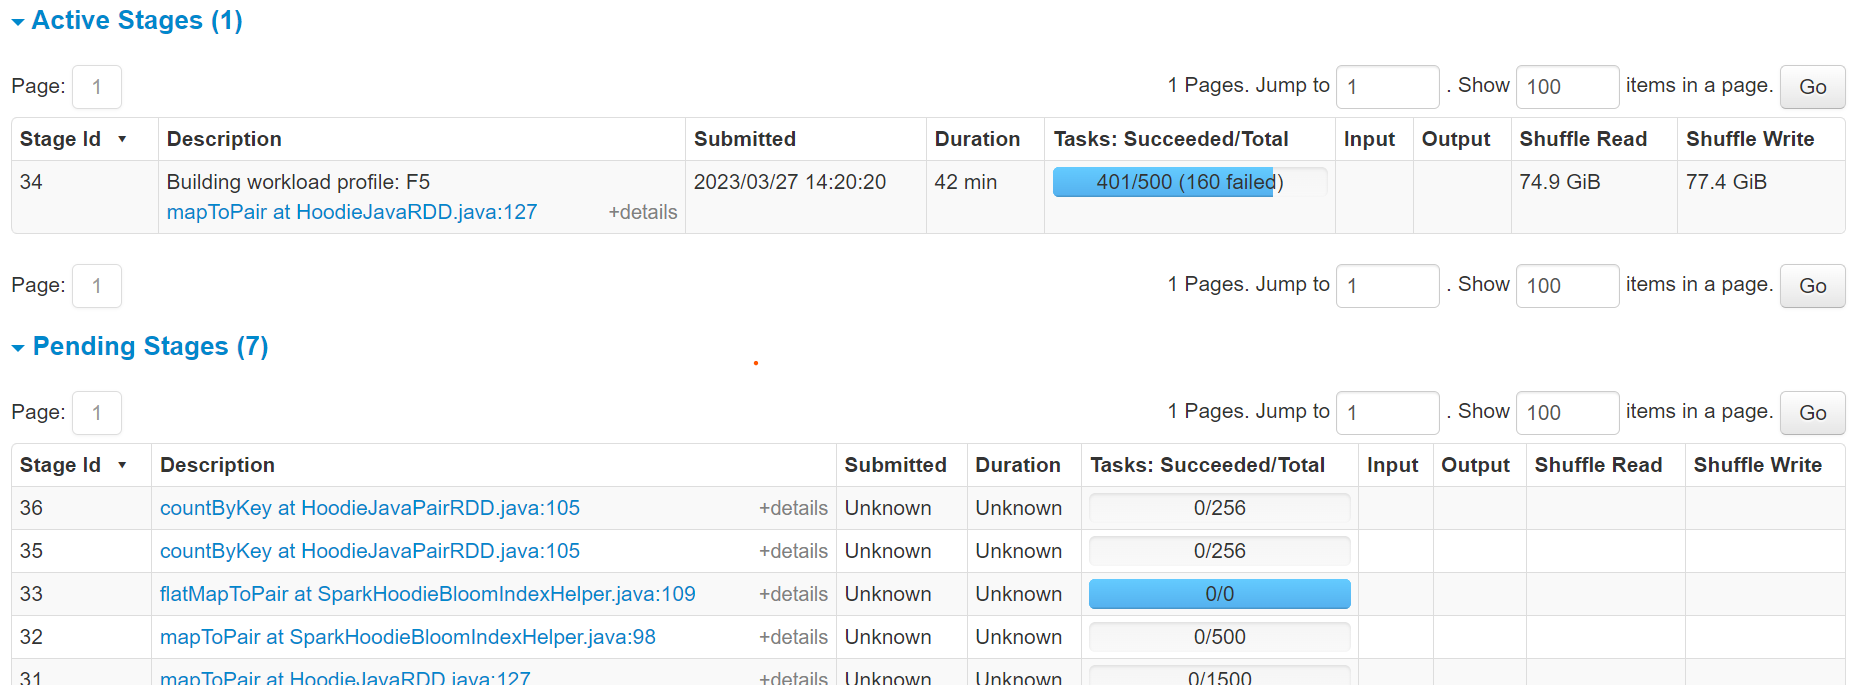
Every time we try to run a complete execution (inserts or updates) we obtain an error of Executor Process Lost until all the executors die and the job fails. The failure always occurs on "Building Workload profile" stage (more info below)
We are using AWS EMR with 1 master node (m5.2xlarge) and 4 instances (r4.8xlarge)
**Hudi Options**
hudiOptions = {
"hoodie.table.name": "F5",
"hoodie.datasource.write.table.type": "MERGE_ON_READ",
"hoodie.datasource.write.recordkey.field": "hour,id",
"hoodie.datasource.write.partitionpath.field": "subsystem,year,month,day",
"hoodie.datasource.write.precombine.field": "dedup",
"hoodie.datasource.write.hive_style_partitioning": "true",
"hoodie.datasource.write.drop.partition.columns": "true",
"hooddie.compact.inline": "true",
"hoodie.datasource.compaction.async.enable": "false",
"hoodie.compact.inline.max.delta.commits": 1,
"hoodie.cleaner.policy": "KEEP_LATEST_FILE_VERSIONS",
"hoodie.cleaner.fileversions.retained": 1,
"hoodie.datasource.write.keygenerator.class": "org.apache.hudi.keygen.ComplexKeyGenerator",
"hoodie.datasource.hive_sync.partition_extractor_class": "org.apache.hudi.hive.MultiPartKeysValueExtractor",
"hoodie.datasource.write.payload.class": "org.apache.hudi.common.model.DefaultHoodieRecordPayload",
"hoodie.index.type": "BLOOM",
"hoodie.bloom.index.filter.type": "DYNAMIC_V0",
"hoodie.upsert.shuffle.parallelism": 500,
"hoodie.metadata.enable": "true",
"hoodie.metadata.index.column.stats.enable": "true",
"hoodie.enable.data.skipping": "true"
}
To write the data we always use the upsert mode: _.option('hoodie.datasource.write.operation', 'upsert')_
**Spark-submit**
--jars /usr/lib/hudi/hudi-spark-bundle.jar
--conf spark.serializer=org.apache.spark.serializer.KryoSerializer
--conf spark.sql.catalog.spark_catalog=org.apache.spark.sql.hudi.catalog.HoodieCatalog
--conf spark.sql.extensions=org.apache.spark.sql.hudi.HoodieSparkSessionExtension
--conf spark.emr.maximizeResourceAllocation=true
**Environment Description**
* Hudi version : 0.12.2-amzn-0
* Spark version: 3.3.1
* Hive version : 3.1.3
* Hadoop version : Amazon 3.3.3
* Storage : S3
* Running on Docker? (yes/no) : No
**Additional context**
We have been playing with both spark and hudi configurations (memory, number of executors/cores, parallelism...) but nothing seems to work for us. Any suggestion or improvement in our configuration is welcome.
**SparkUI information**
Contributor guide
No contributing guide indexed for this repository
Assessment
This issue has not been assessed yet.