SQL Merge into to support Control updates
- Dominant language
- Java
- Stars
- 6.2k
- Forks
- 2.5k
- Avg merge
- 2d 8h
- Merged PRs (30d)
- 111
Description
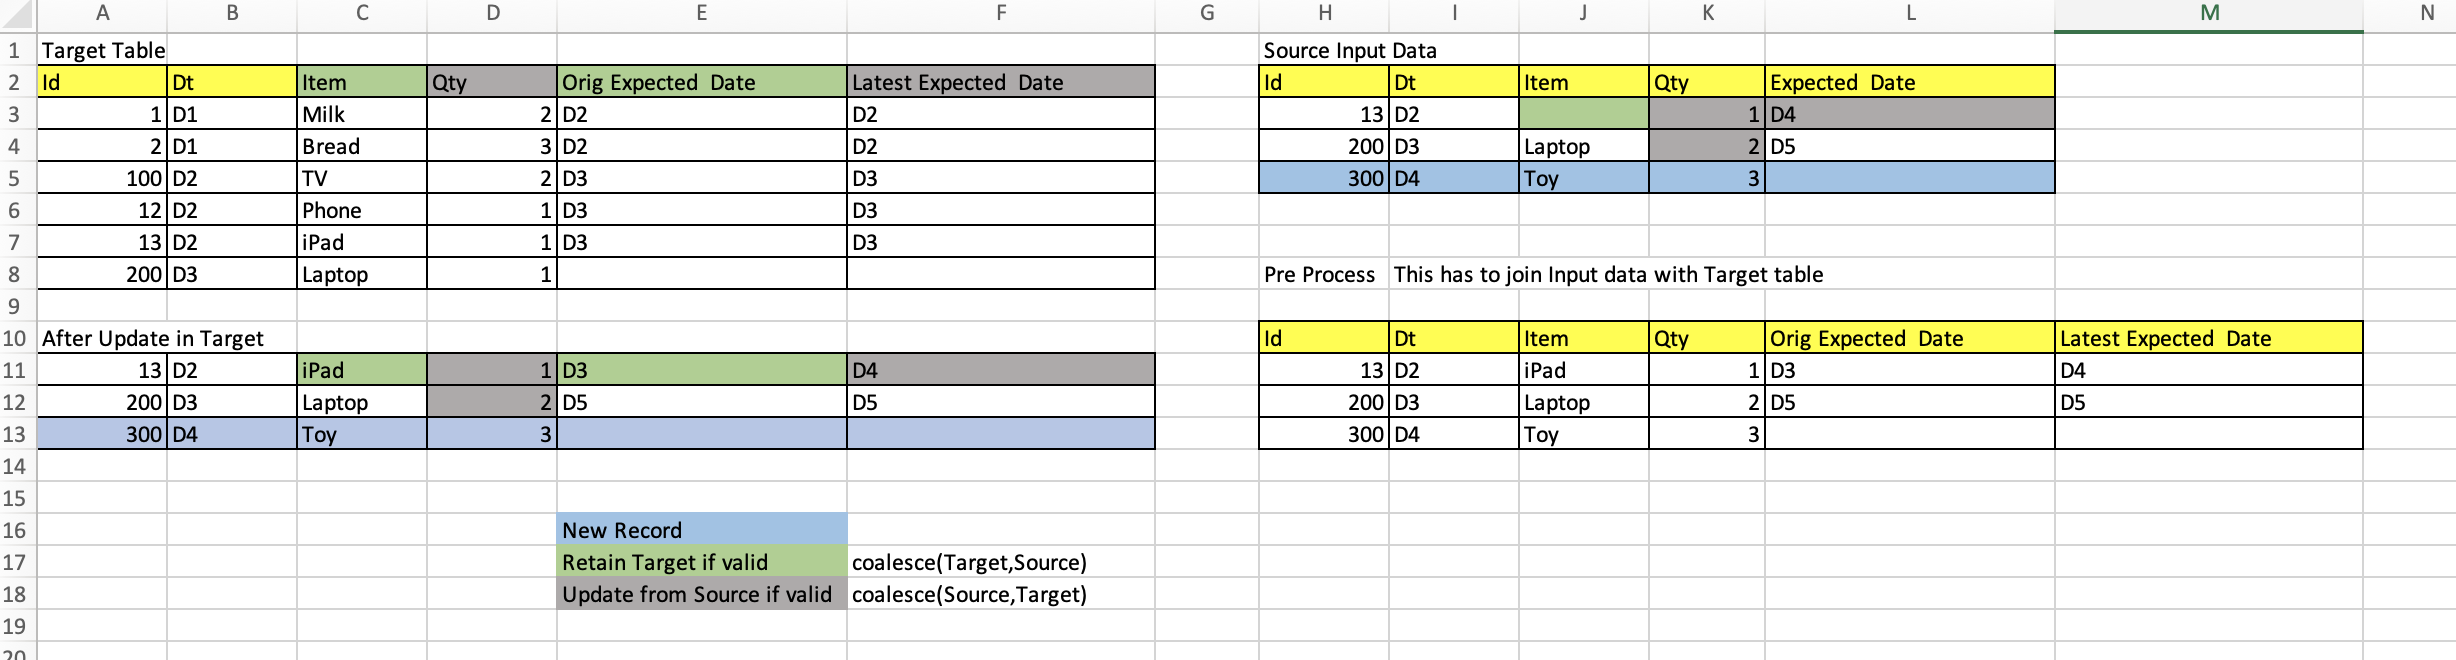
We have use case where we get updates from source and we have to perform control updates by lookup in Target table.
1. For suppose if I have a column in Target table with valid value and If I receive update from source then we need to retain the value in target other wise update from source. This is like Coalesce(Target column,Source Column).
2. Similarly Other use case, If I receive valid value from Source then update it else retain value in target. This is like Coalesce(Source Column, Target Column)
Currently we are performing preprocess by Joining our Source Input Data with Target Hudi table and take care of those above control updates by retaining it either from Target or source. This preprocess stage which including additional join with heavy Target table is causing slowness or lot of delay. Also Spark is not intelligent to prune the partitions based on my Input Data.
Contributor guide
No contributing guide indexed for this repository
Research direction
Start by tracing Apache Hudi's SQL MERGE INTO handling and the source/target update flow described in the issue; no files, tests, or entry points are named. Define how target-versus-source COALESCE control updates should work without the current preprocessing join, then add coverage for both retention cases and verify the resulting merge behavior.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- java, spark, sql
- Domain
- data-engineering, databases
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100