[C++][Parquet] Speed up Parquet Writing?
- Dominant language
- C++
- Stars
- 17.1k
- Forks
- 4.3k
- Avg merge
- 3d 18h
- Merged PRs (30d)
- 91
Description
### Describe the enhancement requested
The following was run on Ubuntu 20 on a `e2-highcpu-32` GCP VM with 32 GB of RAM and 32 vCPUs.
I downloaded the California dataset from https://github.com/microsoft/USBuildingFootprints and converted it from JSONL into Parquet with pyarrow and I attempted to do the same with fastparquet.
```bash
$ ogr2ogr -f GeoJSONSeq /vsistdout/ California.geojson \
| jq -c '.properties * {geom: .geometry|tostring}' \
> California.jsonl
$ head -n1 California.jsonl | jq .
```
```json
{
"release": 1,
"capture_dates_range": "",
"geom": "{\"type\":\"Polygon\",\"coordinates\":[[[-114.127454,34.265674],[-114.127476,34.265839],[-114.127588,34.265829],[-114.127565,34.265663],[-114.127454,34.265674]]]}"
}
```
PyArrow is able to produce a 794 MB Parquet file in 49.86 seconds.
```bash
/usr/bin/time -v \
python3 -c "import pandas as pd; pd.read_json('California.jsonl', lines=True).to_parquet('pandas.pyarrow.snappy.pq', row_group_size=37738, engine='pyarrow')"
```
With ClickHouse I'm able to complete the same task in 18.35 seconds.
```
$ /usr/bin/time -v \
clickhouse local \
--input-format JSONEachRow \
-q "SELECT *
FROM table
FORMAT Parquet" \
< California.jsonl \
> ch.snappy.pq
```
The resulting PyArrow Parquet file matches ClickHouse in terms of row groups and using snappy compression.
```
created_by: parquet-cpp-arrow version 10.0.1
num_columns: 3
num_rows: 11542912
num_row_groups: 306
format_version: 2.6
serialized_size: 228114
```
```
created_by: parquet-cpp version 1.5.1-SNAPSHOT
num_columns: 3
num_rows: 11542912
num_row_groups: 306
format_version: 1.0
serialized_size: 228389
```
The ClickHouse-produced Parquet file is 19,979 bytes larger than the PyArrow-produced file.
These are the versions of software involved:
* pandas-1.5.2-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
* pyarrow-10.0.1-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
* ClickHouse 22.13.1.1361 (official build)
Below is a flame graph from PyArrow's execution.
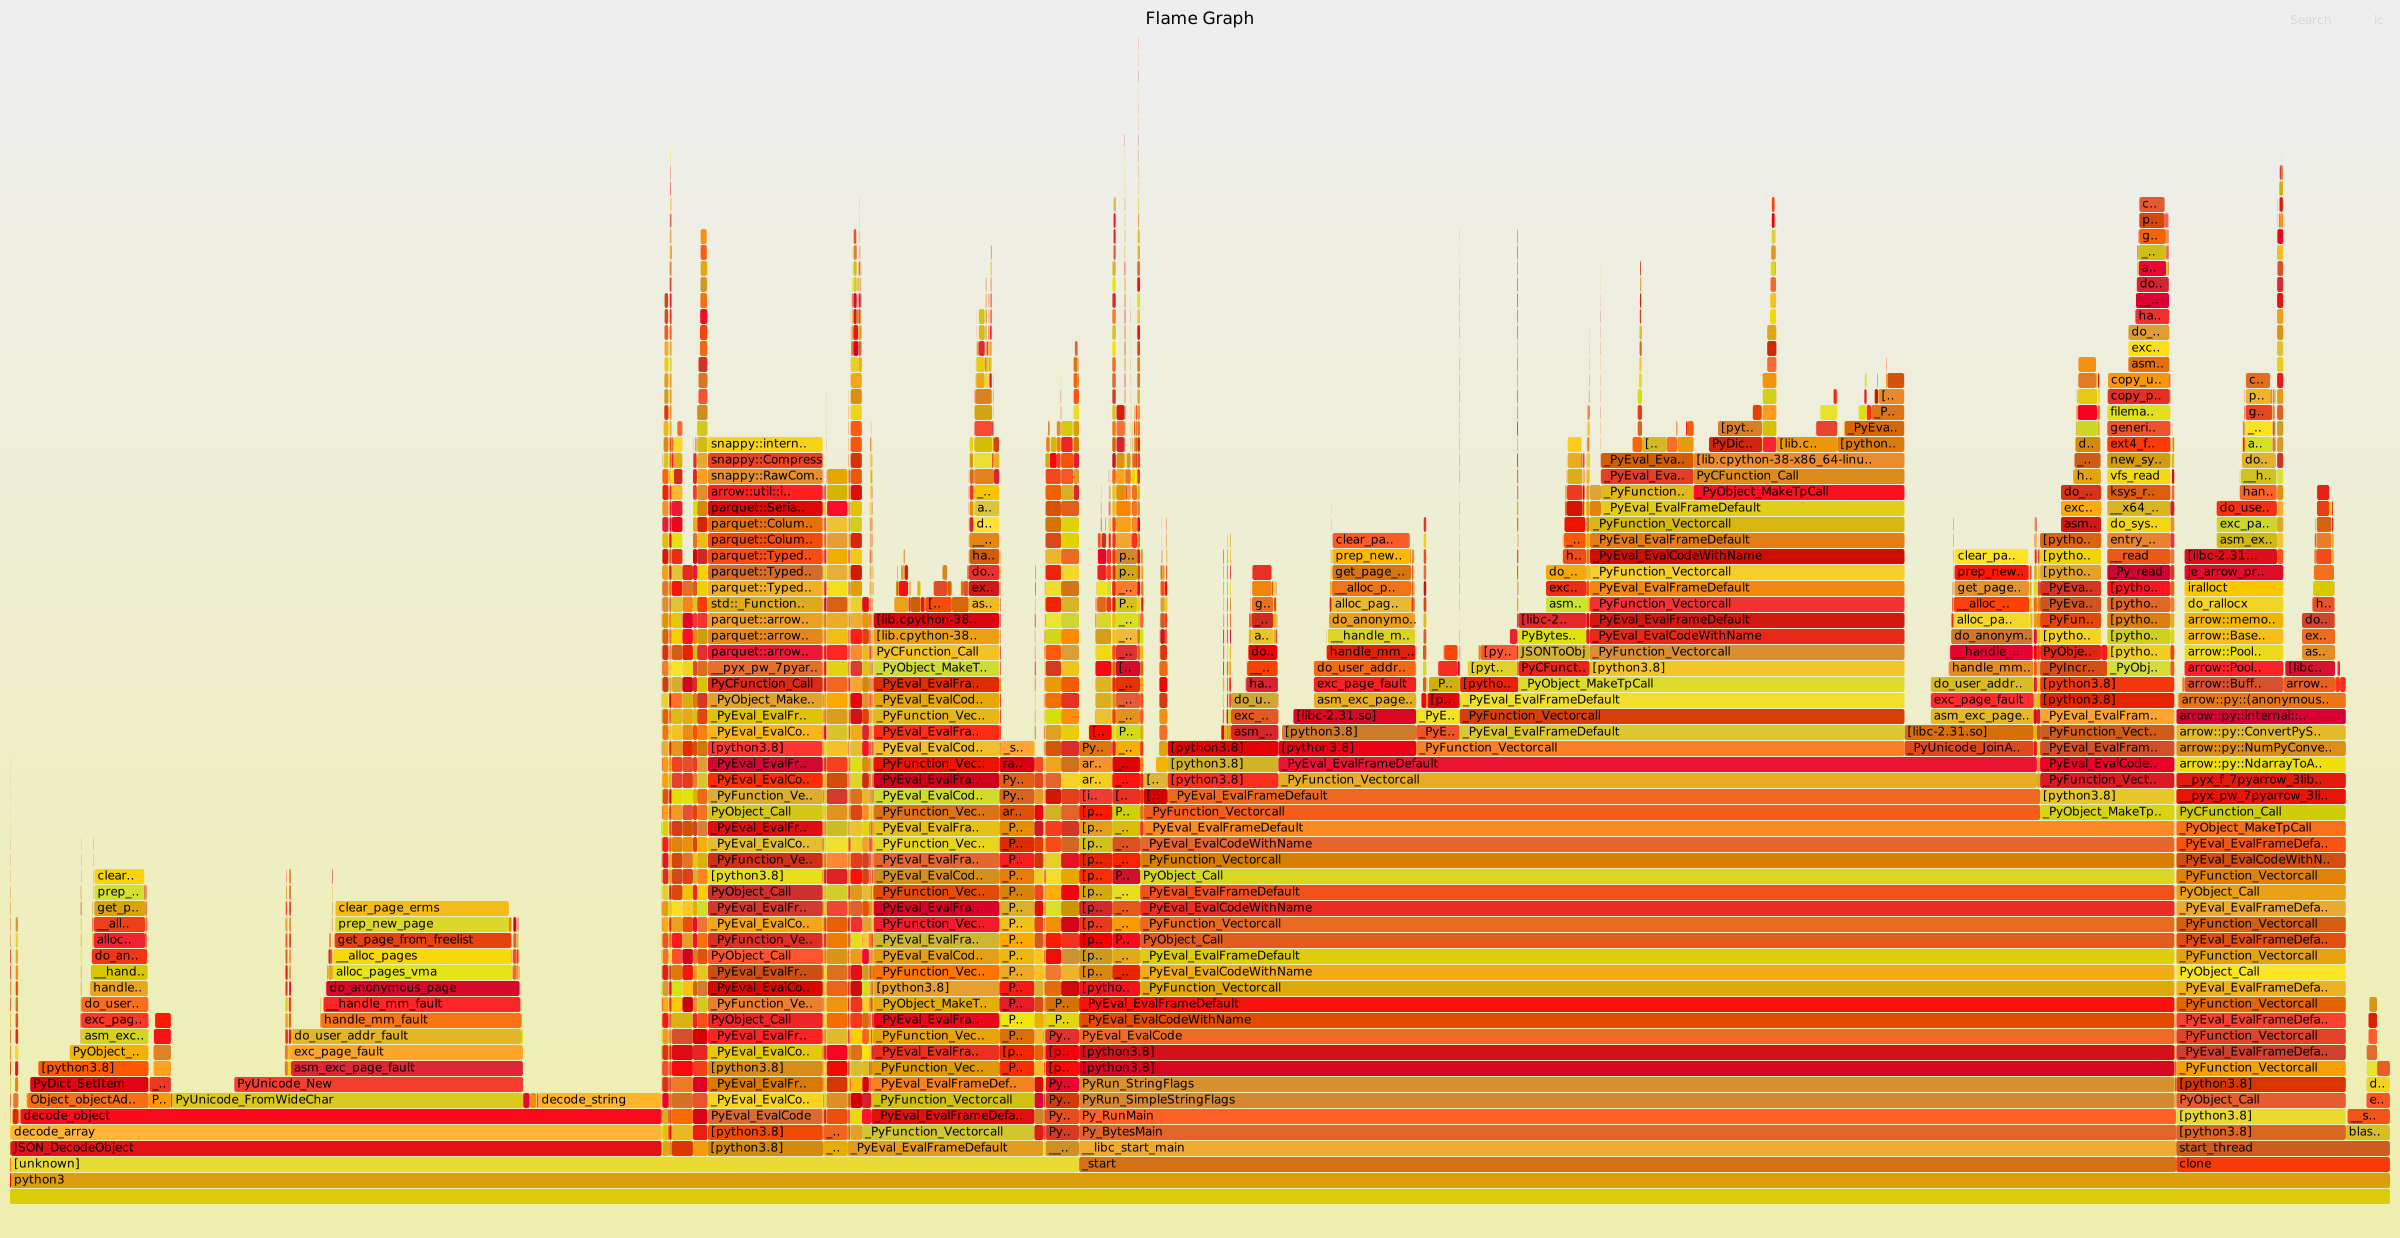
I ran a 10-line version of the above file through both PyArrow and ClickHouse. This is what `strace` and `perf` reported.
```
$ sudo su
$ source /.pq/bin/activate
$ strace -wc \
python3 -c "import pandas as pd; pd.read_json('cali10.jsonl', lines=True).to_parquet('pandas.pyarrow.snappy.pq', row_group_size=37738, engine='pyarrow')"
```
```
% time seconds usecs/call calls errors syscall
------ ----------- ----------- --------- --------- ----------------
42.24 0.097629 141 691 22 openat
14.84 0.034300 15 2183 241 stat
10.44 0.024135 22 1088 read
6.31 0.014591 12 1153 fstat
5.32 0.012300 12 977 5 lseek
4.88 0.011286 16 683 mmap
4.18 0.009669 14 678 close
2.75 0.006358 12 493 487 ioctl
1.81 0.004177 26 160 munmap
1.50 0.003467 21 158 mprotect
1.34 0.003088 93 33 clone
1.30 0.003007 21 138 getdents64
0.76 0.001762 16 109 getcwd
0.68 0.001574 20 75 futex
0.64 0.001471 16 88 brk
0.30 0.000699 10 68 rt_sigaction
0.12 0.000278 14 19 write
0.11 0.000262 18 14 lstat
0.10 0.000222 221 1 execve
0.09 0.000213 11 18 pread64
0.05 0.000119 14 8 2 readlink
0.02 0.000056 13 4 getrandom
0.02 0.000053 17 3 sigaltstack
0.02 0.000049 24 2 open
0.02 0.000043 14 3 uname
0.02 0.000040 13 3 rt_sigprocmask
0.02 0.000039 19 2 madvise
0.02 0.000037 12 3 getpid
0.01 0.000034 17 2 pipe2
0.01 0.000034 11 3 dup
0.01 0.000027 27 1 wait4
0.01 0.000025 12 2 sched_getaffinity
0.01 0.000019 9 2 1 arch_prctl
0.01 0.000015 14 1 sysinfo
0.01 0.000014 13 1 1 access
0.01 0.000013 12 1 gettid
0.00 0.000011 11 1 prlimit64
0.00 0.000011 11 1 fcntl
0.00 0.000011 10 1 set_tid_address
0.00 0.000011 10 1 set_robust_list
------ ----------- ----------- --------- --------- ----------------
100.00 0.231150 8872 759 total
```
```
$ perf stat -dd \
python3 -c "import pandas as pd; pd.read_json('/home/mark/cali10.jsonl', lines=True).to_parquet('/home/mark/pandas.pyarrow.snappy.pq', row_group_size=37738, engine='pyarrow')"
4,197.34 msec task-clock # 8.022 CPUs utilized
50,024 context-switches # 11.918 K/sec
21 cpu-migrations # 5.003 /sec
20,439 page-faults # 4.870 K/sec
0.523260373 seconds time elapsed
2.202498000 seconds user
1.996941000 seconds sys
```
ClickHouse's syscall counts were all much lower:
```
% time seconds usecs/call calls errors syscall
------ ----------- ----------- --------- --------- ----------------
29.52 0.019018 1584 12 futex
21.15 0.013625 63 214 gettid
11.19 0.007209 514 14 mprotect
11.06 0.007123 791 9 4 stat
8.72 0.005617 108 52 close
5.16 0.003327 1109 3 poll
2.19 0.001412 23 60 mmap
2.09 0.001344 39 34 1 openat
1.27 0.000816 18 44 read
...
0.15 0.000098 48 2 write
```
As were context switch and page fault counts.
```
44 context-switches # 372.955 /sec
4997 page-faults # 42.356 K/sec
```
### Component(s)
Parquet
Contributor guide
Research direction
Start by reproducing the Python/PyArrow Parquet conversion benchmark and reviewing the supplied flame graph, strace, and perf results for the Parquet component. The issue does not identify source files or tests; done would require a measurable improvement in Parquet write time while preserving the reported row-group and compression characteristics.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- cpp, python
- Domain
- data-engineering, performance
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100