antvis / antvis/g-webgl-compute
Frame Graph 实现
- Dominant language
- TypeScript
- Stars
- 149
- Forks
- 15
- PR merge metrics
- No merged PRs in 30d
Description
# Frostbite
来自「[GDC17] FrameGraph Extensible Rendering Architecture in Frostbite」[🔗](https://www.gdcvault.com/play/1024612/FrameGraph-Extensible-Rendering-Architecture-in)[解读](https://zhuanlan.zhihu.com/p/36522188)
- WorldRenderer 需要硬编码管线、负责分配资源(RenderTarget、Buffers)。
- Shading System,根据美术在 ShaderGraphs 中的连线构造的 Data-Driven Architecture。
- GFX API 即底层绘图 API,Render Context 为上层的统一抽象。
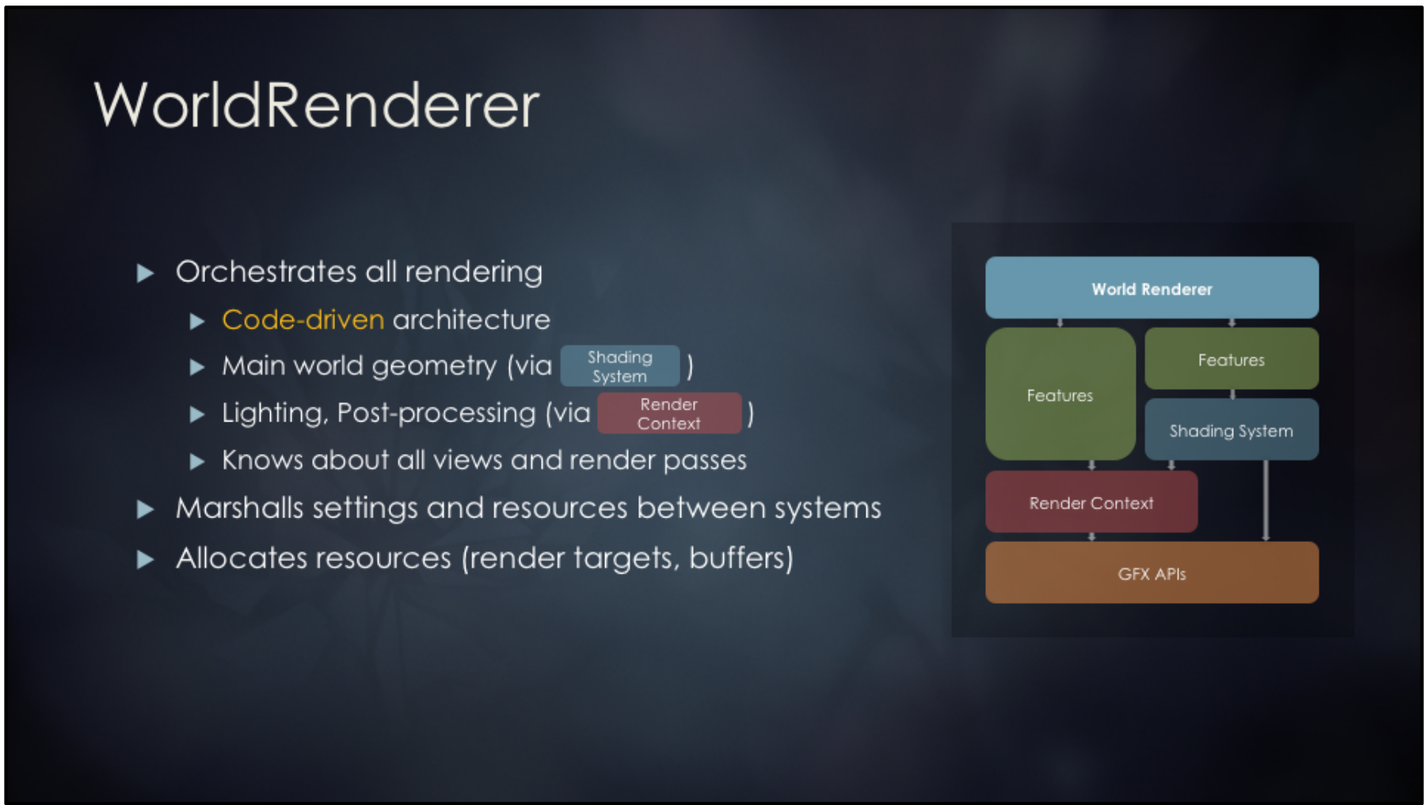
> World Render的挑战:
> - 显式的立即的模式进行渲染;
> - 显式的资源管理,各个产品项目组都会定制、手工的管理ESRAM,对资源的统一性和merge造成了影响;
> - 和渲染框架耦合严重,因为显式的定制渲染和资源,所以很多模块都受到对方的影响;
>
WorldRender的目标:
> - 想知道高层整帧的概况;
> - 更好的扩展性,解耦并组合渲染模块,自动化的资源管理,更好的可视化和分析工具。
引入了两个新的架构组件:Frame Graph 以及 Transient Resource System。
- Frame Graph 用来高度抽象表示 render pass 和资源(render pass 的概念和 vulkan 中的差不多),它了解一帧之内所有的信息;
- Transient Resources 来帮助 FG 分配资源,管理 memory aliasing。

FG的目标:
- 构建高层对整帧的了解,简化资源管理、简化渲染管线配置、简化 async compute 以及 resource barriers;
- 允许我们写独立的高性能渲染模块;
- 可以可视化以及 debug 复杂的渲染管线。
## FG 例子
这是一个 Deferred Shading pipeline,橙色代表render passes,蓝色代表资源,箭头代表render pass之间的依赖关系,红色是write操作,绿色是read操作。

## 设计哲学
- 移除了立即模式的渲染,新的rendering代码可以分割为passes,rendering分为了3个阶段:
- setup设置使用哪些render passes,哪些resources;
- compile负责resources的lifetime,并且给他们分配空间;
- execute就是执行每个render pass。
- 不想提前处理好所有的渲染模块,希望能根据不同的应用场景每帧提前去自定义渲染管线,比如每帧可以变化分辨率,根据是否在播放动画脚本/望远镜/在水下等环境去build pipeline features;
- code-driven的架构。
## Setup 阶段
在 setup 阶段声明的资源并不涉及实际的分配。每个 RP 需要声明自身所需的读/写/新建三类资源,另外一些全局的永久性资源也可以引入,例如 TAA 中的 history buffer。

一个在 RP 中创建 RT 资源例子如下:

当然也可以读入资源,这里使用上一步创建的 RT,输出到下一个 RT:

### 高级用法
- 延迟创建资源,很早的声明资源,直到使用时才创建,根据使用自动设置创建的desc;
- 推导资源参数,可以根据input的格式/size来推导参数,比如在resolve pass需要一个downsample chain,简单的可以自动直接推导出创建资源。
- 移动子资源,可以帮助我们直接在多个pass复用资源,自动的创建子资源或者资源别名。
其中第三点的例子:Deferred Shading,最终会输出2D RT;另外我们还有一个Reflection模块用来做一些convolution,他需要一些cubemap作为input,我们可以使用move操作把lighting buffer输出给cubemap的faces,所以lightbuffer会使用cubemap的subresource view来代替整个2D rtview,复用了lighting buffer的资源。这帮助我们解耦了各个模块,ds和refl模块之间不需要互相了解任何信息。

## Compile 阶段
这个阶段不会给program user暴露,自动运行。把没有引用的res和passes cull掉,这样在setup阶段可以草率一些,更容易解耦,简化了可选的passes以及debug rendering等;计算res的生命周期;根据生命周期和bind flag分配固定的GPU资源,对于async compute会延长其生命周期。
当我们需要debug时,只需要加上move pass,这样lighting pass和post pass会自动被cull掉,与他们相关的依赖项res也会被相应的cull掉。这会帮助我们更好的解耦每个模块。

执行每个rp的callback函数,里面的代码和没有FG之前的一样:包括使用RC、设置state等,dispatch和draw;唯一不同的是这儿需要根据handle去devirtualize真正的GPU资源。
SSAO读取depth输出到raw AO上,filter把raw AO处理为AO,之后作为输入给Lighting pass

我们想把AO变为async compute,这样rawAO的声明周期就延长至lighting pass(main queue中第一次使用其output依赖的地方)。

在C++中怎么声明RP:可以对每个RP声明一个class,但是这样就会破坏code
flow(每个class分割了procedure的代码),需要一堆样板参数,对于现有代码难移植;
使用了lambdas来解决,可以保证线性的代码流,最小化改变已有代码(把原有代码包进lambda中,加入资源的使用声明)
第一段包含rp使用的resources声明;
接下来是setup phase的lambda,声明了resources如何使用;
最后是execution phase的lambda,会在之后才执行,也许会被cull掉不执行;lambda能帮助我们自动捕获需要的变量,对于setup phase逻辑上应该可进行读写设置,捕捉引用&,对于execute phase逻辑上应该是延迟执行,捕捉使用值传递=。

分成两种:
- 类似上面例子中的函数(addMyPass):带有参数的函数,参数和返回值是一些resource handles,frostbite中大多数函数都是这种。
- 类似TAA的history buffer这种,生命周期大于一帧。WorldRenderer依然在高层协调整个渲染,但是它不会分配任何GPU资源,仅仅kick渲染模块,更加简单去扩展,代码量从15k行变为5k行。
之前渲染模块之间显式的通过参数和返回值传递数据,这种机制非常难以扩展因为需要改变函数声明或者结构定义。新的模块通过一种storage(hash table) component传递数据,key是typeid,这样的耦合是可控的。我们想让模块之间可以传递数据,但是又不行暴露给外界;举个例子:tonemap模块需要blur模块的数据,blur模块通过blackboard.add把相应数据加入hashtable,tonemap模块从blackboard中get出blur模块里的数据,这样blur模块不需要知道是否有tonemap的存在。

尽可能复用每一帧中的临时内存:
[Vulkan-Memory-Types-SIGGRAPH-Asia-Dec18.pptx](https://yuque.antfin-inc.com/attachments/lark/0/2020/pptx/158945/1579597698790-7f9d93de-558a-4d63-86bf-ca1064600c74.pptx?_lake_card=%7B%22uid%22%3A%221579597697372-0%22%2C%22src%22%3A%22https%3A%2F%2Fyuque.antfin-inc.com%2Fattachments%2Flark%2F0%2F2020%2Fpptx%2F158945%2F1579597698790-7f9d93de-558a-4d63-86bf-ca1064600c74.pptx%22%2C%22name%22%3A%22Vulkan-Memory-Types-SIGGRAPH-Asia-Dec18.pptx%22%2C%22size%22%3A715175%2C%22type%22%3A%22application%2Fvnd.openxmlformats-officedocument.presentationml.presentation%22%2C%22ext%22%3A%22pptx%22%2C%22progress%22%3A%7B%22percent%22%3A99%7D%2C%22status%22%3A%22done%22%2C%22percent%22%3A0%2C%22id%22%3A%223RRqw%22%2C%22refSrc%22%3A%22https%3A%2F%2Fyuque.antfin-inc.com%2Fattachments%2Flark%2F0%2F2020%2Fpptx%2F158945%2F1579597698790-7f9d93de-558a-4d63-86bf-ca1064600c74.pptx%22%2C%22card%22%3A%22file%22%7D)

# Unreal **RDG(RenderDependecyGraph)**
[https://zhuanlan.zhihu.com/p/101149903](https://zhuanlan.zhihu.com/p/101149903)
为啥取这个名字:

[https://docs.unrealengine.com/zh-CN/Programming/Rendering/RenderDependencyGraph/index.html](https://docs.unrealengine.com/zh-CN/Programming/Rendering/RenderDependencyGraph/index.html)
> 渲染依赖性图表(Rendering Dependency Graph)也被称为RDG或渲染图表,是一个基于图表的调度系统,用于执行渲染管线的整帧优化。它利用DirectX 12这样的现代API,使用自动异步计算调度以及更高效的内存管理和屏障管理来提高性能。
> DirectX 11和OpenGL式的API要求**驱动器调用复杂的启发法**,以确定何时以及如何在GPU上执行关键的调度操作。例如清空缓存、管理和再使用内存,或执行布局转换,等等。由于接口存在即时模式特性,因此需要复杂的记录和状态跟踪才能处理各种极端情况。这些情况最终会对性能产生负面影响,并阻碍并行。
> DirectX 12、Vulkan和Metal 2之类的现代图形API已经弃用此模型,而选择将低级GPU管理的负担转移至应用程序本身。这提供了一个机会,可以利用渲染管线的高级情境来驱动调度,从而提高性能并且简化渲染堆栈。
> RDG的概念如下:在GPU上并非立即执行通道,而是延迟到整个帧已记录到依赖性图表数据结构之中后再执行。当完成了对所有通道的收集之后,则按照依赖性的排序顺序对图表进行编译和执行。


来自 Introducing Qt 3D
> One of the key features of Qt 3D's renderer is the **frame graph** concept. The frame graph is a way to specify how a 3D scene is rendered. Traditionally this would be **hard-coded in low-level C++ code** that implements logic around which groups objects are rendered, in what order, using which specific cameras, what the current render target is etc. We wanted to avoid users having to provide such low level code in order to control the rendering algorithm. The frame graph does this by allowing the developer to specify **data that describes the rendering algorithm** which Qt 3D then translates into the low level code. The approach is data driven which means that the complete rendering approach can be dynamically changed at run-time and without touching any C++ code at all. For more information on the frame graph concept please take a look at this [KDAB blog post](https://www.kdab.com/qt3d-2-0-framegraph/).
[https://www.kdab.com/qt3d-2-0-framegraph/](https://www.kdab.com/qt3d-2-0-framegraph/)
[https://twitter.com/marcinignac/status/839447347960631297](https://twitter.com/marcinignac/status/839447347960631297)

[https://github.com/azhirnov/FrameGraph](https://github.com/azhirnov/FrameGraph)
[https://github.com/azhirnov/FrameGraph/blob/dev/docs/Introduction.md](https://github.com/azhirnov/FrameGraph/blob/dev/docs/Introduction.md)
[https://zhuanlan.zhihu.com/p/66044766](https://zhuanlan.zhihu.com/p/66044766)
[https://zhuanlan.zhihu.com/p/97979406](https://zhuanlan.zhihu.com/p/97979406)
[https://zhuanlan.zhihu.com/p/98572442](https://zhuanlan.zhihu.com/p/98572442)
Contributor guide
No contributing guide indexed for this repository
Research direction
The issue names no repository files, tests, or entry points. Start by reading the cited FrameGraph, RDG, and Qt 3D references, then inspect the existing TypeScript/WebGL rendering structure to identify an integration point. Done should be defined as a working, testable Frame Graph implementation with explicit pass dependencies and resource handling, but the issue does not specify acceptance criteria.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- typescript
- Domain
- computer-graphics
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100