LINE、RandomWalk性能如何提升?
- Dominant language
- C++
- Stars
- 2.9k
- Forks
- 553
- PR merge metrics
- No merged PRs in 30d
Description
背景:10台机器,每台机器配置为64CPU、251G内存,数据规模9千万个点,20亿边,运行LINE或者RandomWalk算法模型,启动1ps + 20worker进行分布式训练,
执行如何命令:
`--data_dir hdfs://path/data
--euler_zk_addr 100.70.40.40@2181
--euler_zk_path /euler
--max_id 90170696
--feature_idx 0
--feature_dim 2
--model line
--model_dir /path/model_line_128_512
--mode train
--learning_rate 0.00005
--num_epochs 1
--dim 128
`
(1)当设置dim = 128时,load完数据后,加载模型过程中,抛出内存不足,运行失败。所以,想问一下像LINE这样的模型为什么这么耗内存?是不是执行命令不对?
(2)当设置dim = 8时,程序可以执行,但是PS进程占用的cpu比较严重,而对应的worker占用cpu不到1%,即所有压力落在的PS上,如下图所示:

从日志打印看出,运行耗时严重:
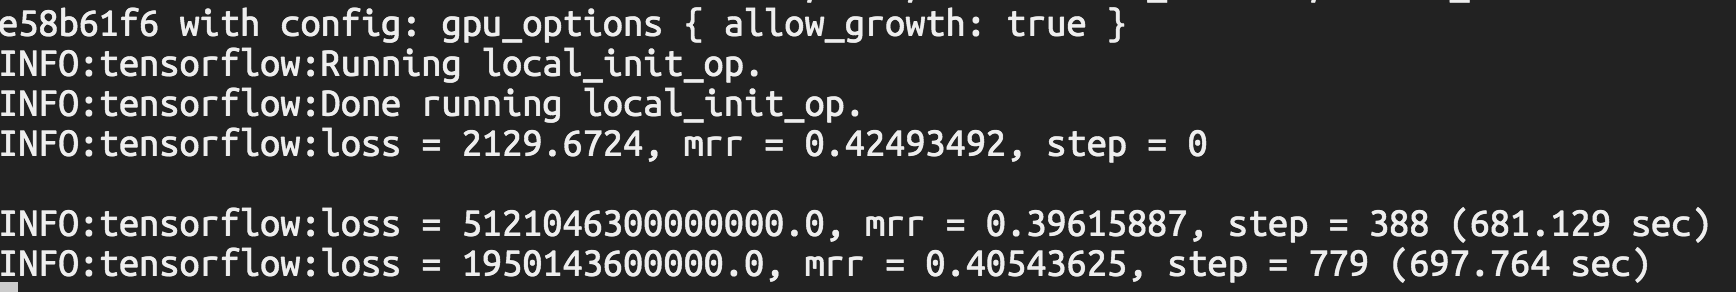
@yangsiran
作为对比,同样的数据运行graphsage算法模型时(dim = 256),一个epoch运行耗时只需要50分钟;所以,对于euler上提供的LINE、RandomWalk等算法模型,基本上无法进行大规模数据的训练,请问,这个问题如何解决? 谢谢!
Contributor guide
No contributing guide indexed for this repository
Research direction
Start by reproducing LINE with the posted distributed-training command, first at dim=8 and then dim=128, while reviewing the runtime logs and memory/CPU behavior. Compare the PS and worker utilization with the reported GraphSAGE run. Done means identifying the cause of the memory failure and PS bottleneck and documenting an actionable way to run these models at the stated scale.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- cpp
- Domain
- distributed-systems, machine-learning, performance
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100