从hive(hdfs)导入数据到另一个hive(hdfs),出现莫名其妙的错乱和字段变多。
Open
Nobody has claimed this yet.
- Dominant language
- Java
- Stars
- 17.4k
- Forks
- 5.7k
- PR merge metrics
- No merged PRs in 30d
Description
原本的hive存储是orc格式,导入另一个hive也是orc格式,但是比较扯的是,发生错位就算了,还多了些字段,简直不知道怎么办
原始数据如图

结果切出来的数据
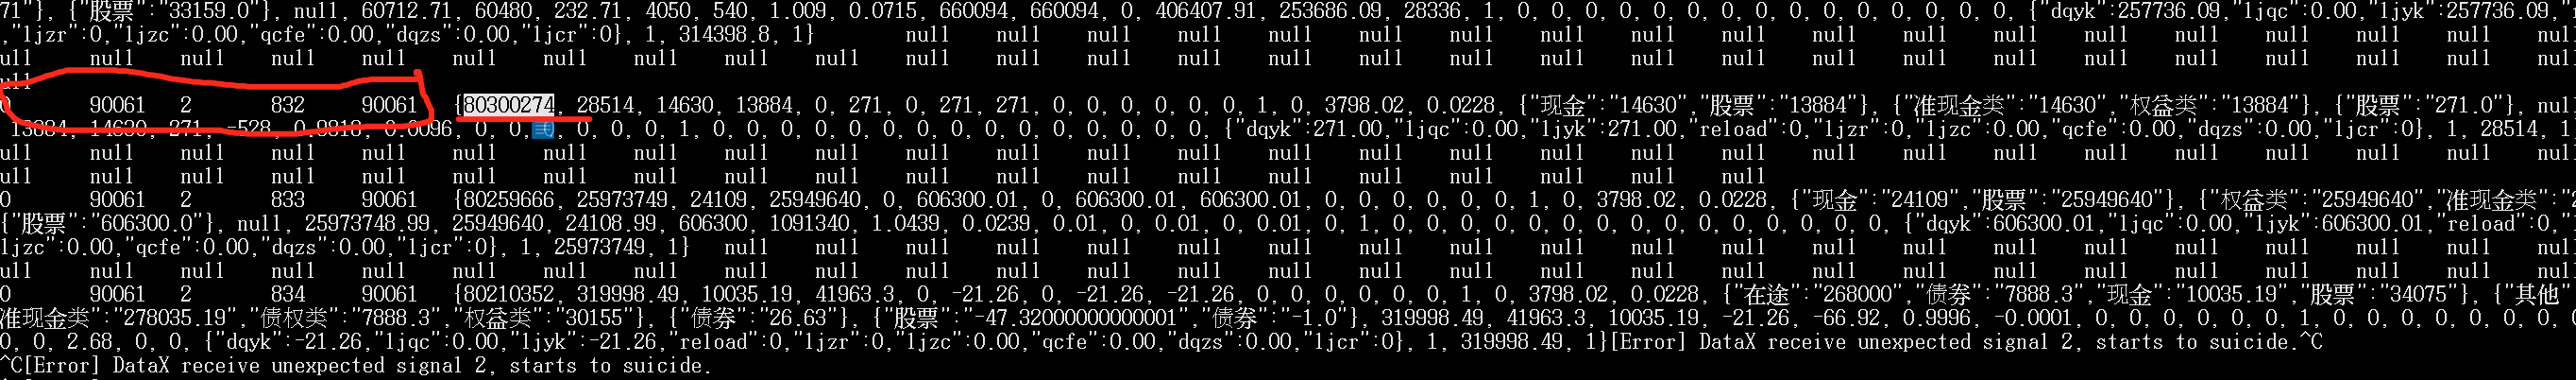
完全懵了,前面多出来的字段,完全不知道是怎么来的
值得注意的是的是里面有些字段是字符串类型的json数据。
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
No repository file, test, or entry point is named. Start by documenting the source and target Hive/HDFS tables, confirming both use ORC, and checking how fields containing JSON strings are transferred; compare the resulting columns with the screenshots. Done means the transfer preserves field order and does not introduce extra fields, with a reproducible test case.
Written by the indexing model from the issue text.
Assessment
- Domain
- data-engineering, databases
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 20/100