TimelyDataflow / TimelyDataflow/timely-dataflow
Timely job OOM for too many messages received
Open
Nobody has claimed this yet.
question
- Dominant language
- Rust
- Stars
- 3.6k
- Forks
- 293
- Avg merge
- 14h 46m
- Merged PRs (30d)
- 4
Description
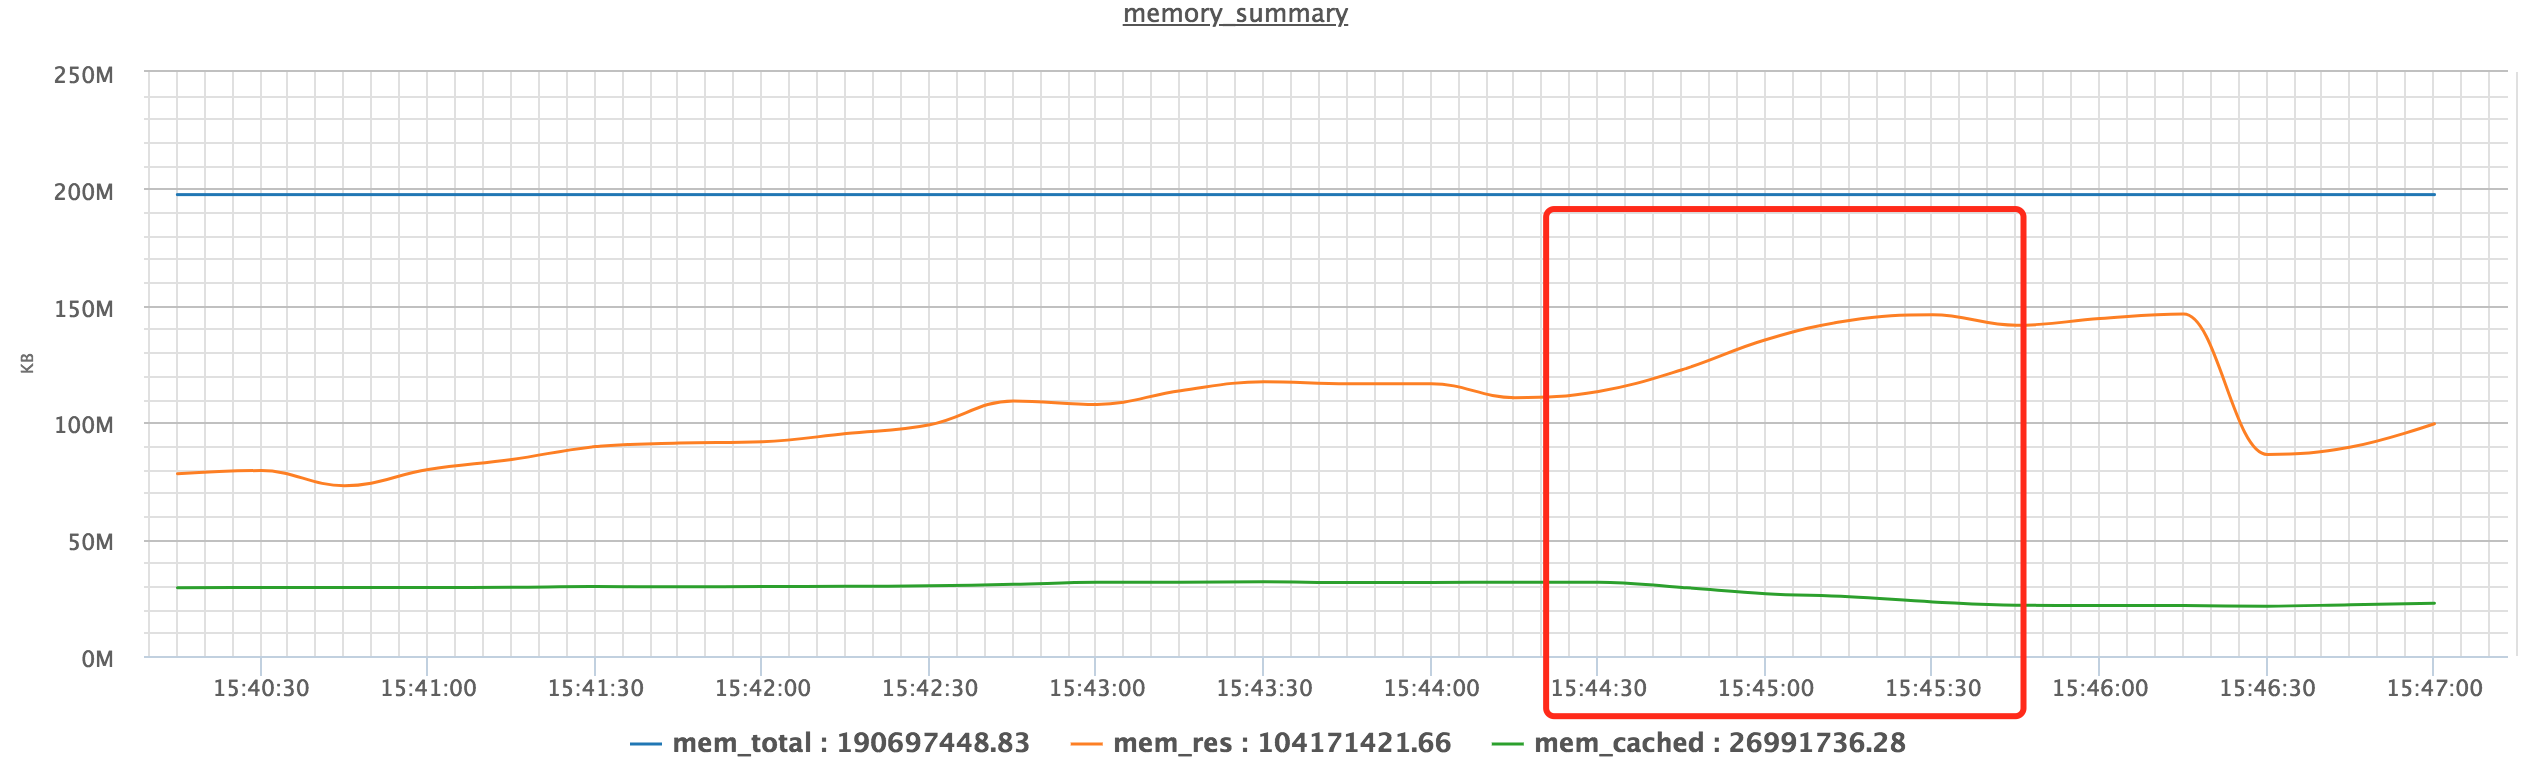
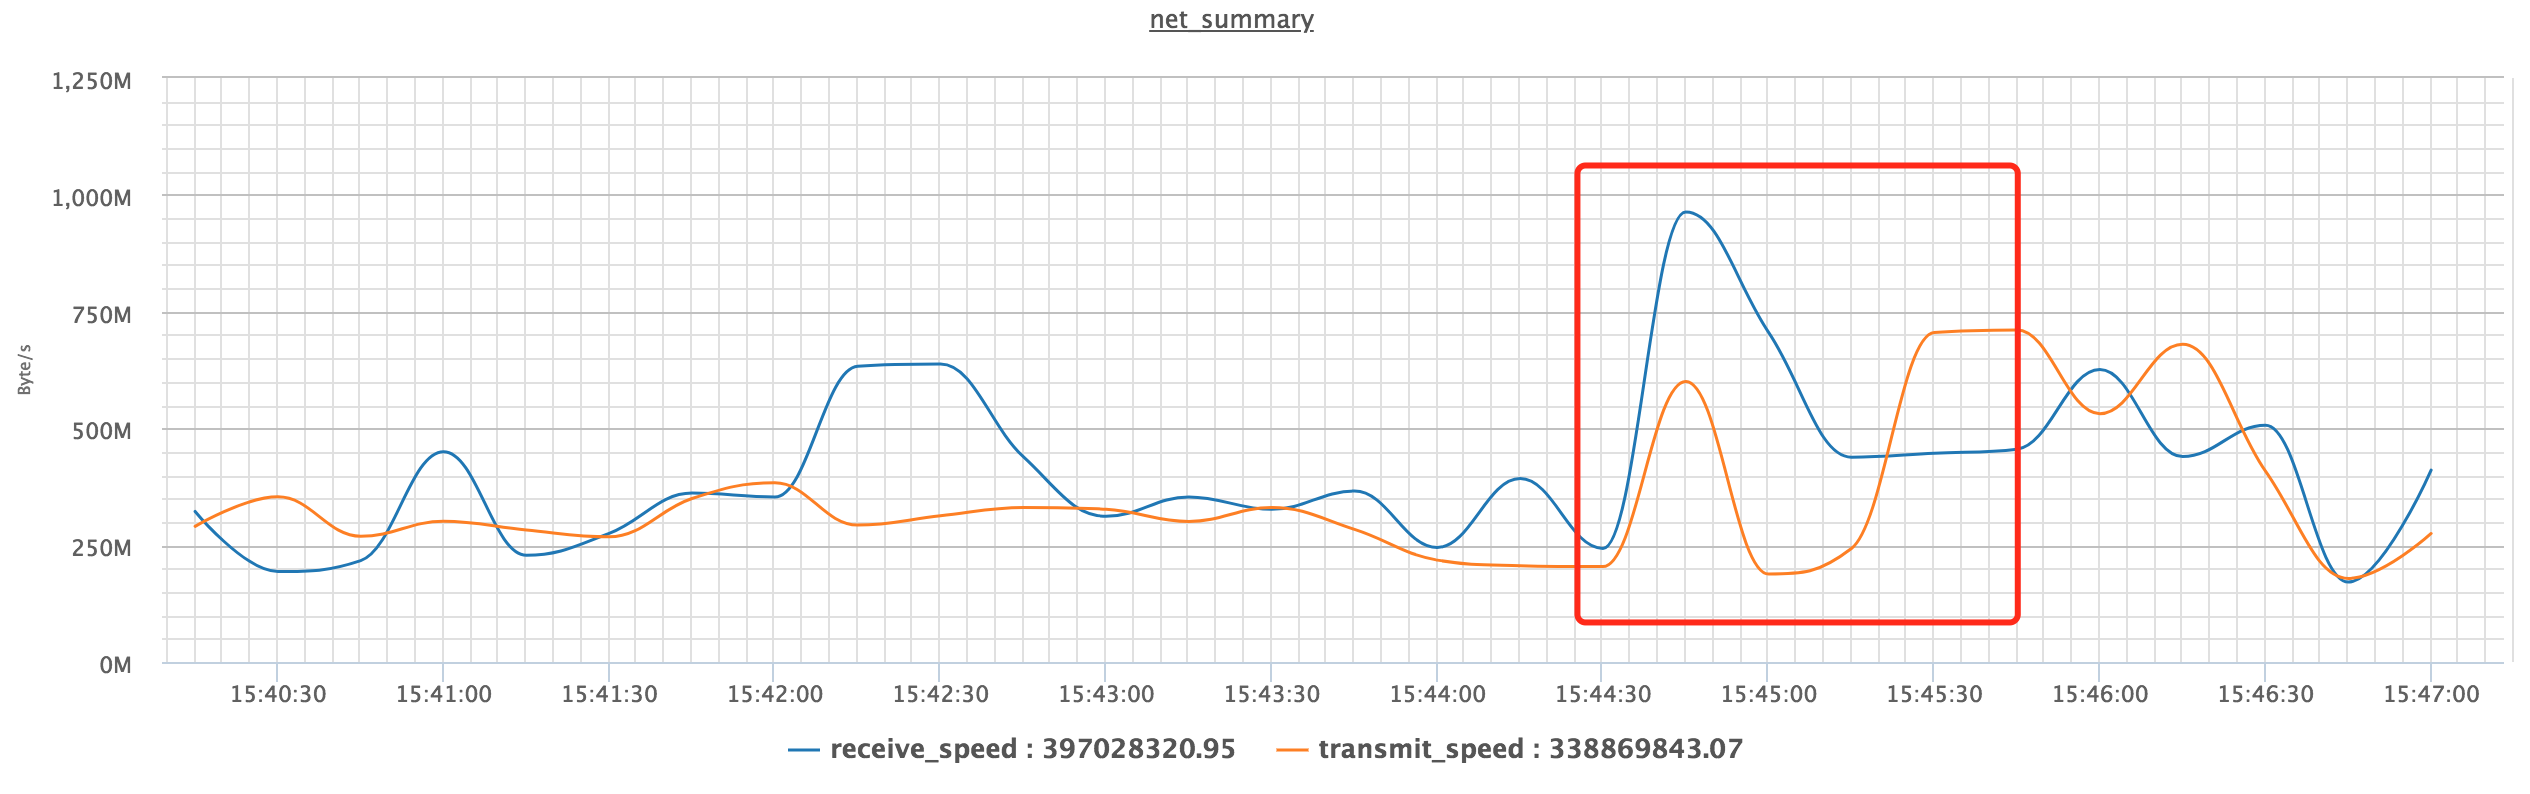
I ran my timely job with 30G RAM each processor, I found that when some processors receive and send too many messages for an instant, the processors will OOM. I find the memory and network summary of the machine as follows:
The memory summary
The net summary
Are there any suggestions to solve this problem? Thanks @frankmcsherry
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
No files, tests, or entry points are identified. Start by reproducing the timely job with 30G RAM per processor while reviewing the provided memory and network summaries; done means the message burst no longer causes processors to run out of memory.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- rust
- Domain
- distributed-systems, performance
- Issue type
- Bug
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100