RocketChat / RocketChat/Rocket.Chat
Metrics of last restarted instance looks a bit overloaded
Nobody has claimed this yet.
- Dominant language
- TypeScript
- Stars
- 46.1k
- Forks
- 13.9k
- Avg merge
- 3d 3h
- Merged PRs (30d)
- 130
Description
Description:
We have docker deployment with 25 instances for users connections and 2 instances for present monitor without users (actually one with presence monitor enabled).
But we have couple instances with strange load according to Rocket chat Metrics.
That instances have completely similar configurations in docker-compose.yml file and normal users amount (not more then other instances)
Steps to reproduce:
- Setup docker deployment and Metrics monitoring
- Check Metrics for some graphs
- Few instances behave strange
Expected behavior:
All instances should have similar load and metrics.
Actual behavior:
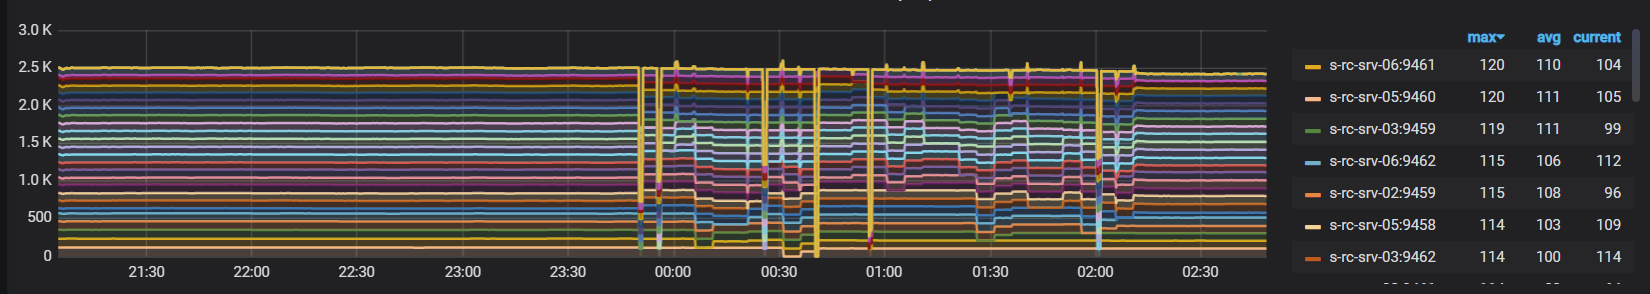
Here is a metric size graph
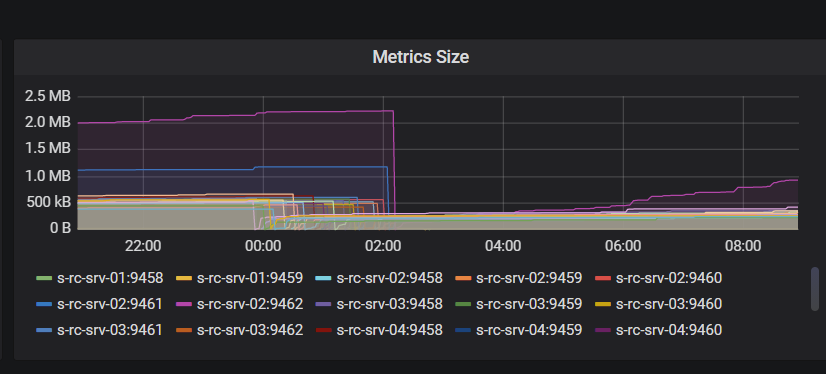
As you can see 5 instance on 2 server have much more metrics size
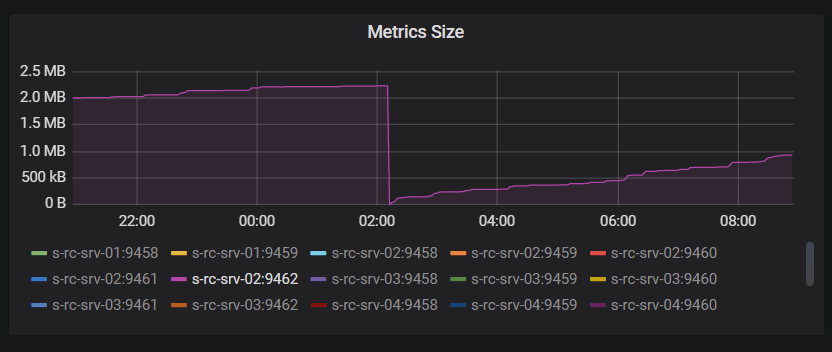
And another screen right now
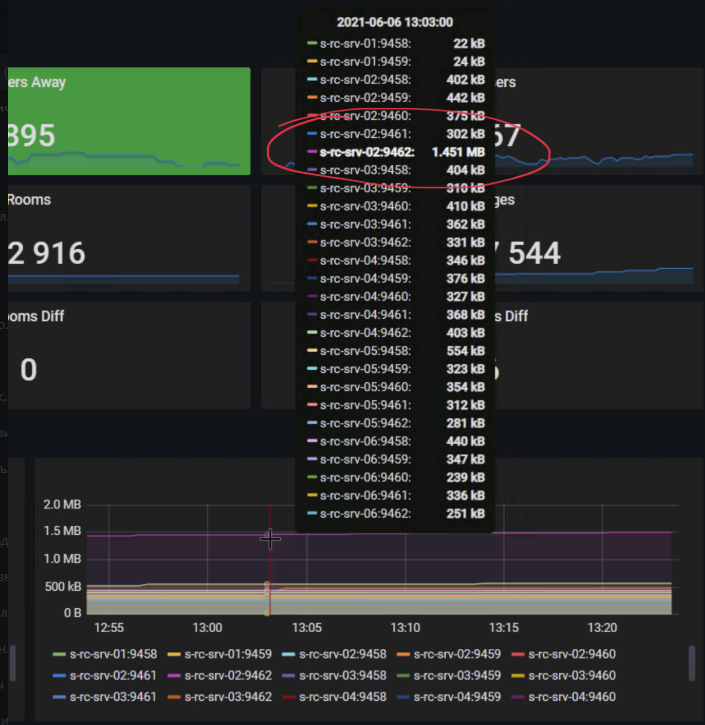
And 4 instance on that same 2 server too
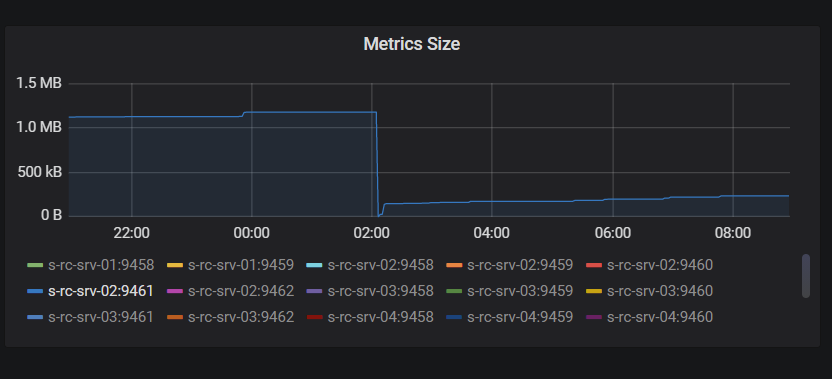
Event loop lag is bigger then other instances
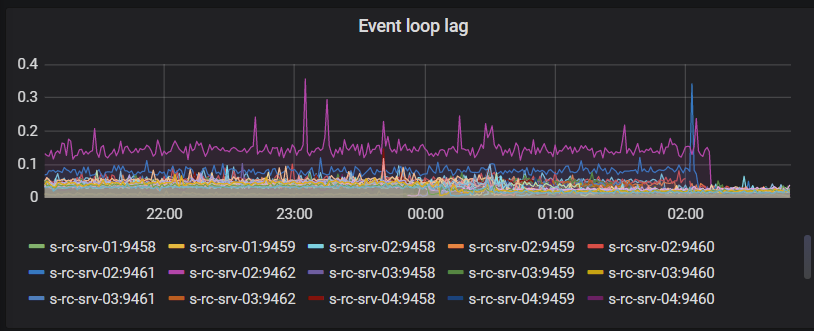
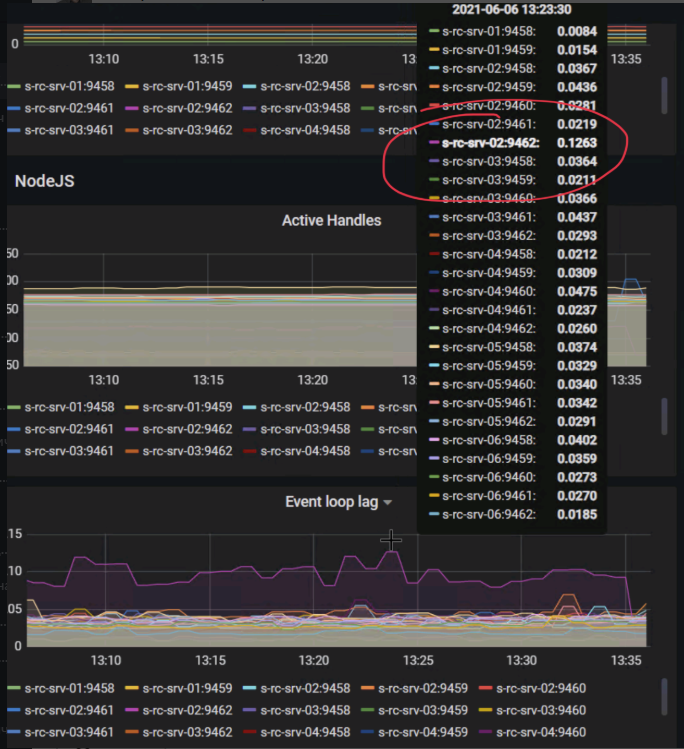
Pod heap same as others
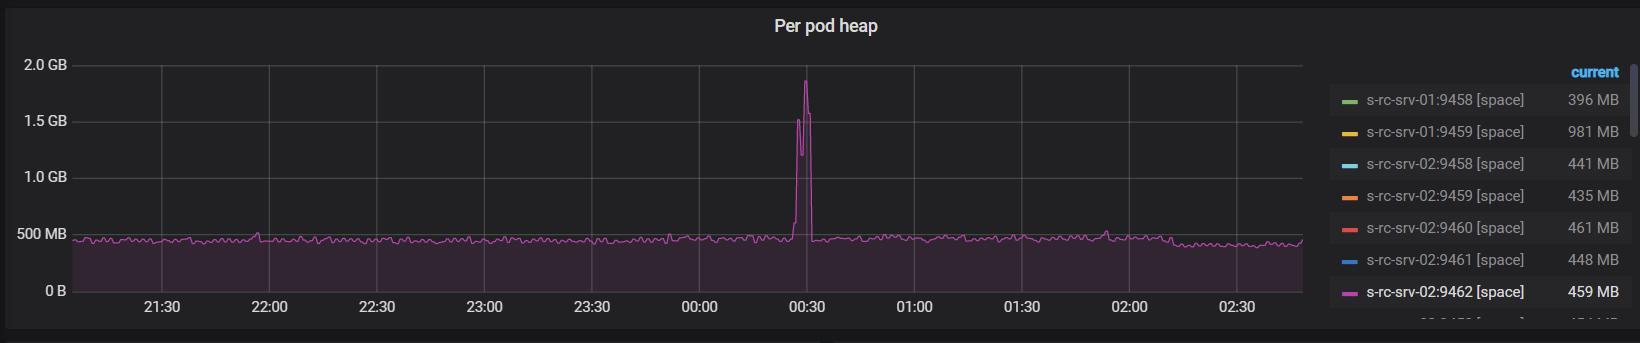
But amount of WS sessions is even less then other instances
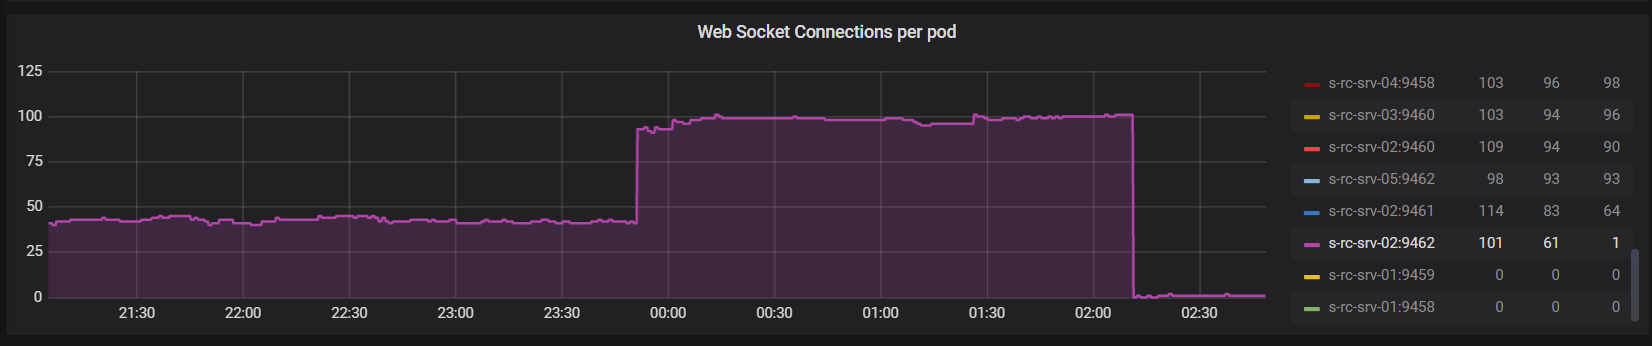
Server Setup Information:
- Version of Rocket.Chat Server: 3.15.0
- Operating System: CentOS7
- Deployment Method: docker
- Number of Running Instances: 25
- DB Replicaset Oplog: Enabled
- NodeJS Version: 12.22.1
- MongoDB Version: 4.2.14 WiredTiger
Client Setup Information
- Desktop App or Browser Version: 3.2.2
- Operating System: Windows 10
Additional context
That graphs collected at weekend with really low load, but metrics for that few instances behave same all times.
In general all 5 (last) instances have more metrics size and event loop lag.
We restart every instances one-by-one and in each server I restart from 5 to 1 instances (5-4-3-2-1)
So 5 instance of 5 server restarted first and 1 instance of 2 server restarted last (actually 1 instance of 1 server restarted last, but 1 server holds 2 instances without user sessions)
Relevant logs:
No
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start with the docker-compose.yml configurations and the supplied metrics graphs, comparing the affected instances with the others and accounting for the restart order. Reproduce or inspect the metrics behavior under the stated Rocket.Chat, NodeJS, MongoDB, and Docker versions; done means identifying why specific instances show higher metric size and event-loop lag and documenting or validating the fix.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- docker, mongodb, node.js
- Domain
- backend, infrastructure, observability
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100