PyThaiNLP / PyThaiNLP/pythainlp
Using adversarial texts for training text normalization algorithms
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 1.2k
- Forks
- 304
- Avg merge
- 2d 14h
- Merged PRs (30d)
- 14
Description
Consider the following example:
Current PythaiNLP's text normalization relies heavily on rules, which are sufficient in some circumstances. However, consider the following example, it considerably fails
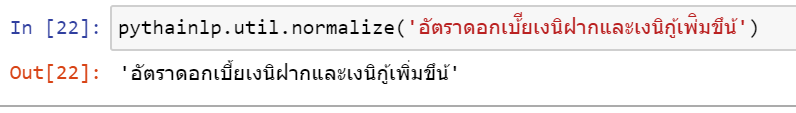 .
Input: อัตราดอกเบ้ียเงนิฝากและเงนิกู้เพ่ิมขึน้
Expect: อัตราดอกเบี้ยเงินฝากและเงินกู้เพิ่มขึ้น
Would it be possible if we can train a ML model for text normalization? I think the approach is similar to what we did for thai2rom, which is a seq2seq model.
Speaking about training data, we might develop a probabilistic model that perturbed a given word according to to some rules, e.g. สระลอย. So, we can use it to generate the training data for our seq2seq normalization model.
From what I can see, consider that many Thai official documents are in PDF, this model will be very useful for preprocessing results from PDF parsing, which is typically not robust for cases such as สระลอย.
@c4n : do you think we can leverage what you've developed for https://github.com/c4n/Thai-Adversarial-Evaluation here?
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by reviewing the existing thai2rom seq2seq approach and the related Thai-Adversarial-Evaluation project. Define how adversarial Thai text would generate training data and how the model would be evaluated against the provided normalization example; the issue does not name specific files or tests.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- machine-learning
- Issue type
- Feature
- Difficulty
- 5/5
- Estimated time
- Over a week
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 25/100