OHDSI / OHDSI/FeatureExtraction
Feature Extraction seems to return NA for timeId for temporalCovariate continuous covariates
Open
Nobody has claimed this yet.
- Dominant language
- R
- Stars
- 74
- Forks
- 63
- PR merge metrics
- No merged PRs in 30d
Description
reproducible example
# Get cohort json
cohortJson <- RJSONIO::fromJSON("https://raw.githubusercontent.com/OHDSI/SkeletonCohortDiagnosticsStudy/main/inst/cohorts/14907.json", digits = 23) %>%
  RJSONIO::toJSON(digits = 23, pretty = TRUE)

# render cohort sql
cohortExpression <- CirceR::cohortExpressionFromJson(expressionJson = cohortJson)
genOp <- CirceR::createGenerateOptions(
  cohortId = 1,
  vocabularySchema = "@vocabulary_database_schema",
  generateStats = FALSE)
cohortSql <- CirceR::buildCohortQuery(expression = cohortExpression, options = genOp)

# set up connections to eunomia
connectionDetails <- Eunomia::getEunomiaConnectionDetails()
connection = DatabaseConnector::connect(connectionDetails = connectionDetails)
cdmDatabaseSchema <- "main"
cohortDatabaseSchema <- "main"
cohortTable <- "cohort"
databaseId <- "Eunomia"

# instantiate cohort
DatabaseConnector::renderTranslateExecuteSql(connection = connection,
                                             sql = cohortSql,
                                             cdm_database_schema = cdmDatabaseSchema,
                                             vocabulary_database_schema = cohortDatabaseSchema,
                                             target_database_schema = cohortDatabaseSchema,
                                             target_cohort_table = cohortTable)

# set up temporal covariate settings object
temporalCovariateSettings = createTemporalCovariateSettings(
  useConditionOccurrence = TRUE,
  useDrugEraStart = TRUE,
  useDrugEraOverlap = TRUE,
  useVisitCount = TRUE,
  useVisitConceptCount = TRUE,
  useProcedureOccurrence = TRUE,
  useMeasurement = TRUE,
  temporalStartDays = c(-365, -30, 0, 1, 31,
                        seq(from = -421, to = -31, by = 30),
                        seq(from = 0, to = 390, by = 30)),
  temporalEndDays = c(-31, -1, 0, 30, 365,
                      seq(from = -391, to = -1, by = 30),
                      seq(from = 30, to = 420, by = 30))
)

# execute feature extraction
featureExtractionOutput <-
  FeatureExtraction::getDbCovariateData(
    connection = connection,
    cdmDatabaseSchema = cdmDatabaseSchema,
    cohortDatabaseSchema = cohortDatabaseSchema,
    cohortTable = cohortTable,
    covariateSettings = temporalCovariateSettings,
    aggregated = TRUE
  )

# inspect returned object
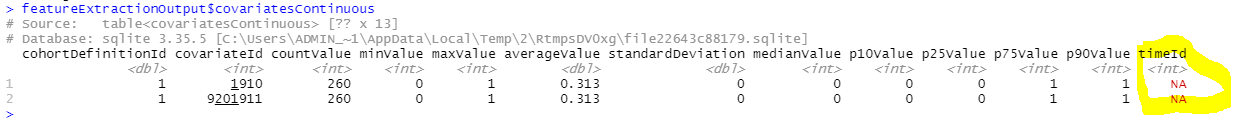
featureExtractionOutput$covariatesContinuous
See timeId is NA
Contributor guide
No contributing guide indexed for this repository
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Reproduce the example using FeatureExtraction::getDbCovariateData and inspect the returned covariatesContinuous data, focusing on how temporal covariate timeId values are produced. Compare the temporal settings and generated output to determine why timeId is NA; done means the affected continuous covariates return the expected time identifiers.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- r
- Domain
- databases
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100