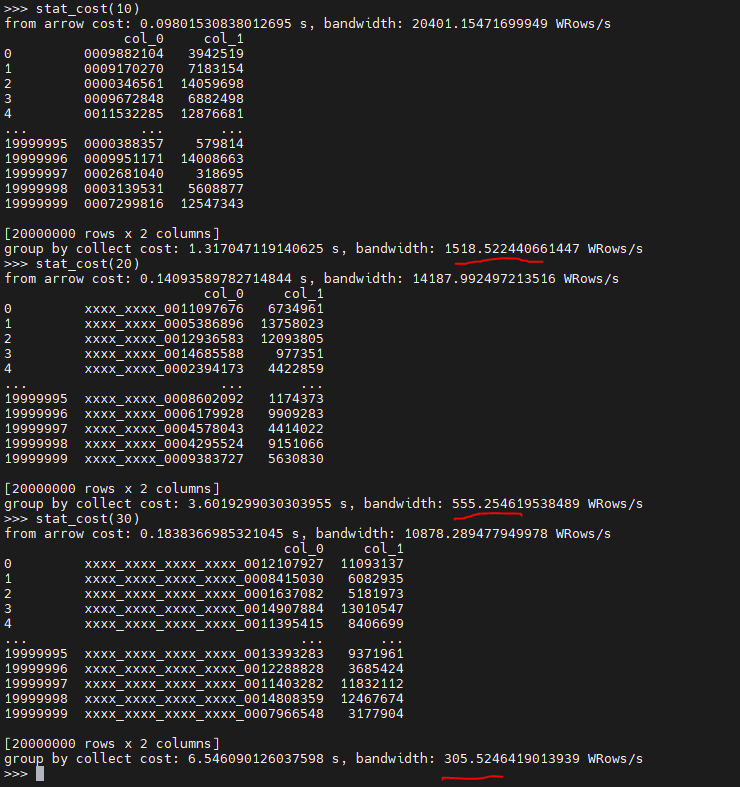
[QST]The group by collect performance is insufficient, and the performance deteriorates with the increase of the group by column length.
- Dominant language
- C++
- Stars
- 9.8k
- Forks
- 1.1k
- Avg merge
- 3d 6m
- Merged PRs (30d)
- 278
Description
**What is your question?**
The group by collect performance is insufficient, and the performance deteriorates with the increase of the group by column length.
```
>>> import cudf
>>> import time
>>>
>>> import pandas
>>> import pyarrow
>>> import numpy as np
>>>
>>> def create_table(n_rows, n_cols, n_range):
... table = pyarrow.Table.from_pydict(
... {f'col_{c}': np.random.randint(0, n_range, size=[n_rows]) for c in range(n_cols)})
... return table
...
>>>
>>> def create_table_with_str(n_rows, n_cols, n_strs, n_strs_cols, n_range):
... prefix = 'xxxx_' * ((n_strs - 10) // 5)
... cdf = create_table(n_rows, n_cols, n_range).to_pandas()
... for i in range(n_strs_cols):
... cdf[f'col_{i}'] = cdf[f'col_{i}'].apply(lambda x: f'{prefix}{x:010}')
return pyarrow.Table.from_pandas(cdf)... return pyarrow.Table.from_pandas(cdf)
...
>>>
>>> def stat_cost(str_len):
... tbl = create_table_with_str(2000 * 10000, 2, str_len, 1, 1500 * 10000)
... start = time.time()
... df = cudf.DataFrame.from_arrow(tbl)
... print(f'from arrow cost: {time.time() - start} s, '
... f'bandwidth: {df.shape[0] / 10000 / (time.time() - start)} WRows/s')
... print(df)
... start = time.time()
... result = df.groupby(['col_0']).collect()
... print(f'group by collect cost: {time.time() - start} s, '
... f'bandwidth: {df.shape[0] / 10000 / (time.time() - start)} WRows/s')
...
>>>
>>> stat_cost(10)
from arrow cost: 0.09801530838012695 s, bandwidth: 20401.15471699949 WRows/s
col_0 col_1
0 0009882104 3942519
1 0009170270 7183154
2 0000346561 14059698
3 0009672848 6882498
4 0011532285 12876681
... ... ...
19999995 0000388357 579814
19999996 0009951171 14008663
19999997 0002681040 318695
19999998 0003139531 5608877
19999999 0007299816 12547343
[20000000 rows x 2 columns]
group by collect cost: 1.317047119140625 s, bandwidth: 1518.522440661447 WRows/s
>>> stat_cost(20)
from arrow cost: 0.14093589782714844 s, bandwidth: 14187.992497213516 WRows/s
col_0 col_1
0 xxxx_xxxx_0011097676 6734961
1 xxxx_xxxx_0005386896 13758023
2 xxxx_xxxx_0012936583 12093805
3 xxxx_xxxx_0014685588 977351
4 xxxx_xxxx_0002394173 4422859
... ... ...
19999995 xxxx_xxxx_0008602092 1174373
19999996 xxxx_xxxx_0006179928 9909283
19999997 xxxx_xxxx_0004578043 4414022
19999998 xxxx_xxxx_0004295524 9151066
19999999 xxxx_xxxx_0009383727 5630830
[20000000 rows x 2 columns]
group by collect cost: 3.6019299030303955 s, bandwidth: 555.254619538489 WRows/s
>>> stat_cost(30)
from arrow cost: 0.1838366985321045 s, bandwidth: 10878.289477949978 WRows/s
col_0 col_1
0 xxxx_xxxx_xxxx_xxxx_0012107927 11093137
1 xxxx_xxxx_xxxx_xxxx_0008415030 6082935
2 xxxx_xxxx_xxxx_xxxx_0001637082 5181973
3 xxxx_xxxx_xxxx_xxxx_0014907884 13010547
4 xxxx_xxxx_xxxx_xxxx_0011395415 8406699
... ... ...
19999995 xxxx_xxxx_xxxx_xxxx_0013393283 9371961
19999996 xxxx_xxxx_xxxx_xxxx_0012288828 3685424
19999997 xxxx_xxxx_xxxx_xxxx_0011403282 11832112
19999998 xxxx_xxxx_xxxx_xxxx_0014808359 12467674
19999999 xxxx_xxxx_xxxx_xxxx_0007966548 3177904
[20000000 rows x 2 columns]
group by collect cost: 6.546090126037598 s, bandwidth: 305.5246419013939 WRows/s
```
How to improve performance?
Contributor guide
Assessment
This issue has not been assessed yet.