Errors when converting a Dali tensor to a pytoch tensor
Nobody has claimed this yet.
- Dominant language
- C++
- Stars
- 5.8k
- Forks
- 678
- Avg merge
- 3d 1h
- Merged PRs (30d)
- 27
Description
Hi, guys.
I tried to combine DALI with the torch.autograd.graph.saved_tensors_hooks(pack_hook,unpack_hook) API to speed up the offloading and prefetching of intermediate feature maps to SSDs.
I converted the Pytorch tensor to numpy for storage on the SSD during forward propagation, and used pipe_gds() to fetch back to the GPU during backward propagation, then completed the DALI Tensor to Pytorch via nvidia.dali.plugin.pytorch.feed_ndarray() Tensor conversion.
When executing the feature map generated by the convolution layer, some errors occur and the error output is as follows.
(wjpytorch) root@li:~/wj# python test_with_hook_gds.py
Files already downloaded and verified
train_data_size:50000
cuda:0
Number of parameter: 0.14 M
Memory of parameter: 0.56 M
--------------The 1 training begins----------
inputimages type is torch.Size([64, 10])
inputimages type is torch.Size([2560, 64])
successfully free 7d4e1136-ed45-4a2c-9afd-ad109689260b.npy
successfully free 7c970ca2-82b1-43f2-87ac-4df69e35a576.npy
inputimages type is torch.Size([1024, 64])
inputimages type is torch.Size([2560, 1024])
successfully free 4375fe98-b486-418e-b70e-74e80de8cf99.npy
successfully free bf5766bb-3f17-4df0-a7c8-5fe7d17e0c3b.npy
inputimages type is torch.Size([2560, 64, 8, 8])
Traceback (most recent call last):
  File "/root/wj/test_with_hook_gds.py", line 123, in <module>
    loss.backward()
  File "/root/anaconda3/envs/wjpytorch/lib/python3.9/site-packages/torch/_tensor.py", line 363, in backward
    torch.autograd.backward(self, gradient, retain_graph, create_graph, inputs=inputs)
  File "/root/anaconda3/envs/wjpytorch/lib/python3.9/site-packages/torch/autograd/__init__.py", line 173, in backward
    Variable._execution_engine.run_backward(  # Calls into the C++ engine to run the backward pass
RuntimeError: AssertionError: The element type of DALI Tensor/TensorList doesn't match the element type of the target PyTorch Tensor: torch.int64 vs torch.float32

At:
  /root/anaconda3/envs/wjpytorch/lib/python3.9/site-packages/nvidia/dali/plugin/pytorch.py(55): feed_ndarray
  /root/wj/test_with_hook_gds.py(59): unpack_hook
I'm not sure if this is due to DALI or the Pytorch API, when I use torch.load() directly to read a Pytorch tensor file, no errors occur. Could you give me some suggestions for adjustments?
The reproducible code is as follows:
import os
import time
import uuid
import inspect
import torch
import torch.nn as nn
import torch.nn.functional as F
import numpy as np
import torchvision
from torch import cuda
from nvidia.dali import pipeline_def, fn
import nvidia.dali.plugin.pytorch
from torch.utils.data import DataLoader

device=torch.device('cuda:0')

#pynvml.nvmlInit()
#frame = inspect.currentframe()
#gpu_tracker = MemTracker(frame)

train_data=torchvision.datasets.CIFAR10(root='./data',train=True,transform=torchvision.transforms.ToTensor(),download=True)
#test_data=torchvision.datasets.CIFAR10(root='./data',train=False,transform=torchvision.transforms.ToTensor(),download=True)

train_data_size=len(train_data)
#test_data_size=len(test_data)
print("train_data_size:{}".format(train_data_size))
#print("test_data_size:{}".format(test_data_size))

train_dataloader=DataLoader(train_data,batch_size=2560)
#test_dataloader=DataLoader(test_data,batch_size=128)

'''hook'''
class SelfDeletingTempFile():
    def __init__(self):
        self.name=os.path.join("",str(uuid.uuid4()))
    def __del__(self):
        freefilename = self.name +'.npy'
        os.remove(freefilename)
        print("successfully free " + freefilename)

@pipeline_def(batch_size=1, num_threads=8, device_id=0)
def pipe_gds(filename):
    data = fn.readers.numpy(device='gpu',file_root='.', files=filename)
    return data

def pack_hook(tensor):
    temp_file=SelfDeletingTempFile()
    tensorshape = tensor.shape
    Inputnumpy = tensor.cpu().numpy()
    np.save(temp_file.name,Inputnumpy)
    file = [temp_file, tensorshape]
    return file

def unpack_hook(file):
    Inputimages = torch.zeros(file[1]).to(device)
    p = pipe_gds(filename=(file[0].name+'.npy'))
    p.build()
    pipe_out = p.run()
    nvidia.dali.plugin.pytorch.feed_ndarray(pipe_out[0][0], Inputimages)
    print("inputimages type is",Inputimages.shape)
    return Inputimages


""" Network architecture. """
class mymodel(nn.Module):
    def __init__(self):
        super(mymodel, self).__init__()

        self.model1=nn.Sequential(
        nn.Conv2d(3, 32, 5, padding=2),
        nn.MaxPool2d(2),
        nn.Conv2d(32, 32, 5, padding=2),
        nn.MaxPool2d(2),
        nn.Conv2d(32, 64, 5, padding=2),
        nn.MaxPool2d(2),
        nn.Flatten(),  # 展平

        nn.Linear(64 * 4 * 4, 64),
        nn.Linear(64, 10),
        )

    def forward(self, x):  # input:32*32*3
        with torch.autograd.graph.saved_tensors_hooks(pack_hook,unpack_hook):
            x=self.model1(x)
        return x

net1=mymodel()
net1=net1.to(device)
loss_fn=nn.CrossEntropyLoss()
loss_fn=loss_fn.to(device)
optimizer=torch.optim.SGD(net1.parameters(),lr=0.1)

total_train_step=0
total_test_step=0
epoch=20

print(next(net1.parameters()).device)
total = sum([param.nelement() for param in net1.parameters()])
print("Number of parameter: %.2f M"  % (total/1024/1024))
print("Memory of parameter: %.2f M " % (cuda.memory_allocated()/1024/1024))


'''start training'''
totalbegin=time.time()
#gpu_tracker.track()
for i in range(epoch):
    print("--------------The {} training begins----------".format(i+1))

    running_loss=0
    running_correct=0

    begin=time.time()
    for data in train_dataloader:
        images,targets=data
        #print(images.device)
        images=images.to(device)
        targets=targets.to(device)

        outputs=net1(images)
        loss=loss_fn(outputs,targets)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

        running_loss+=loss.item()
        running_correct += (outputs.argmax(1) == targets).sum()
        total_train_step+=1

        #if total_train_step%100==0:
        #    print("number of training:{},loss:{}".format(total_train_step,loss))

    end = time.time()
    print("spend time: ",(end-begin)/60)
    print("epoch:{}, loss:{}, accuracy:{}".format(i+1,running_loss/train_data_size,running_correct/train_data_size))

totalend=time.time()
print("total real runtime: ", (totalend - totalbegin) / 60)
#gpu_tracker.track()
print("gpu memory allocated: %2.f M " % (cuda.memory_allocated()/1024/1024))
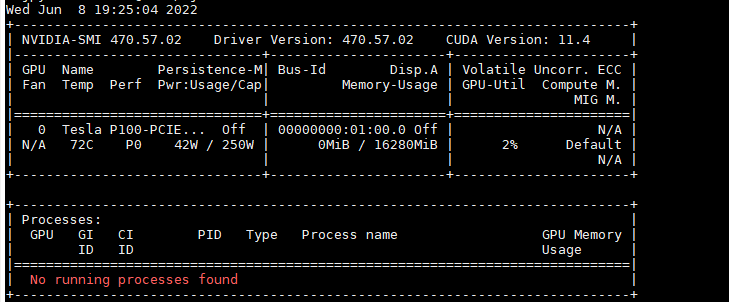
My GPU is Nvidia P100, and my Pytorch is 1.11.0+cu113. My Dali version is 1.14.
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Assessment
This issue has not been assessed yet.