Lightning-AI / Lightning-AI/pytorch-lightning
Cannot replicate results from vanilla Pytorch using Deepspeed integration
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 31.4k
- Forks
- 3.8k
- Avg merge
- 6d 7h
- Merged PRs (30d)
- 6
Description
### Bug description
I notice that while training with DeepSpeed my results were much worse so I decided to do a quick experiment where I am trying to overfit to a small dataset.
The exact same code with a `strategy=auto` quickly overfits the dataset. Output logs when using `strategy=auto`:
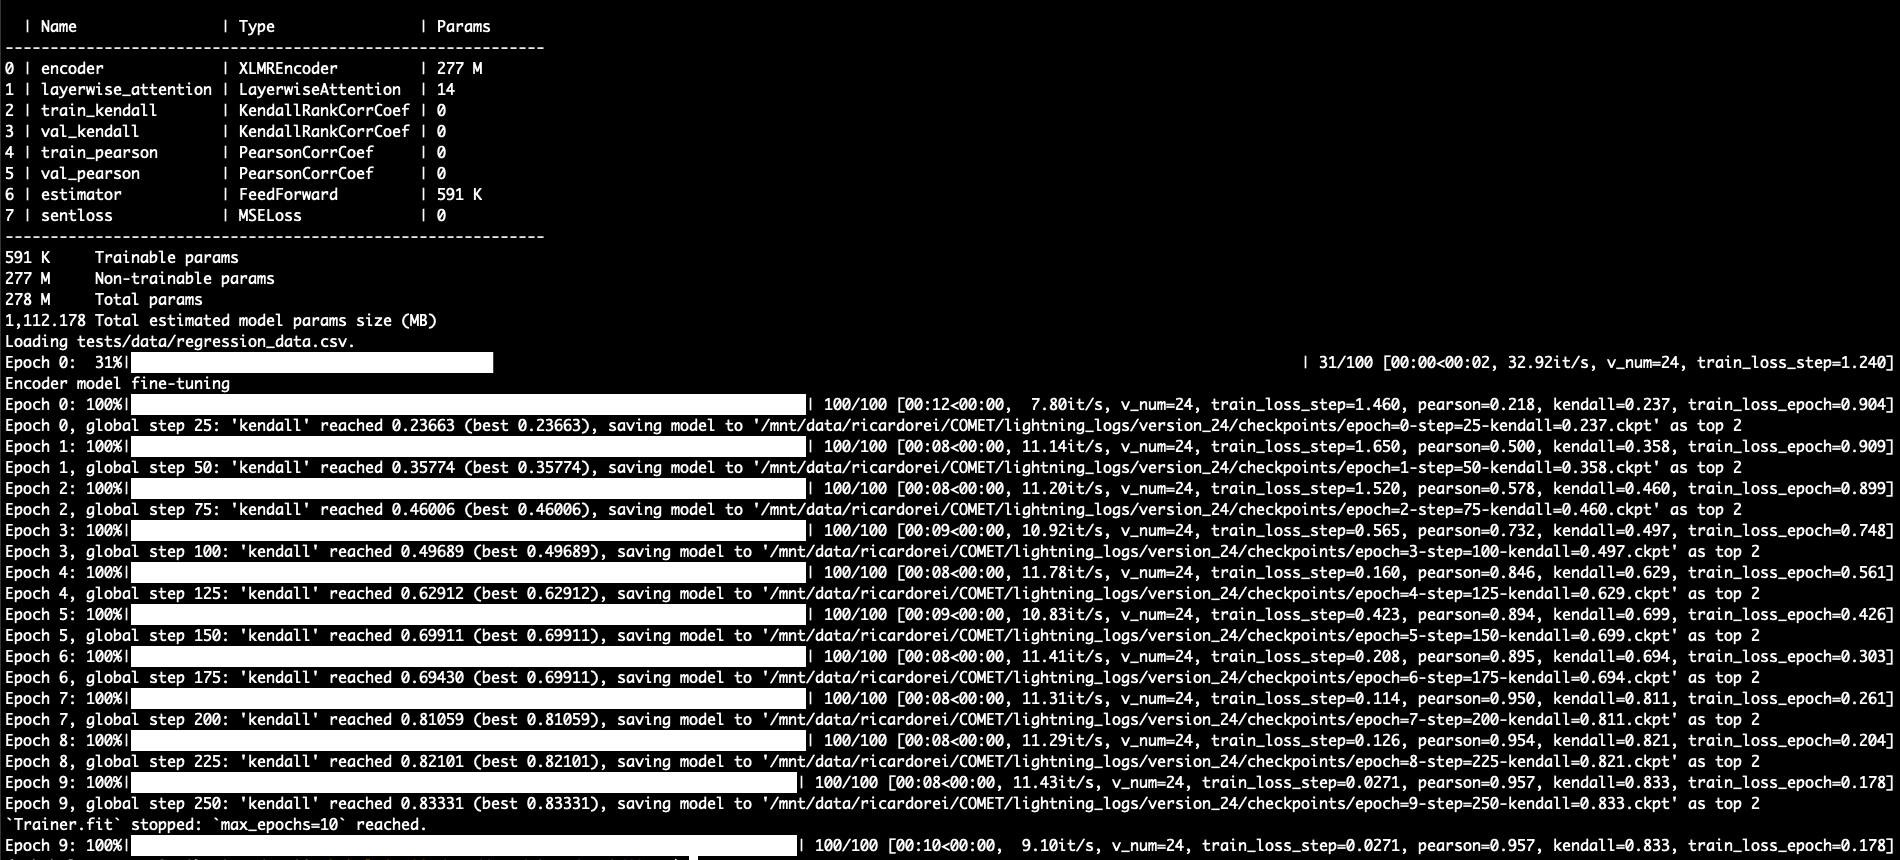
Note that my task is a regression task and therefore kendall close to 1 is a really strong correlation!
When changing `strategy=deepspeed_stage_2` results are completely different and the model does not seem to be learning:

I also tried with `deepspeed_stage_1` and results are similar to deepspeed_stage_2.
My configure optimizer is simple:
```python
def configure_optimizers(
self,
) -> Tuple[List[torch.optim.Optimizer], List[torch.optim.lr_scheduler.LambdaLR]]:
"""Pytorch Lightning method to initialize a training Optimizer and learning
rate scheduler.
Returns:
Tuple[List[torch.optim.Optimizer], List[torch.optim.lr_scheduler.LambdaLR]]:
List with Optimizers and a List with lr_schedulers.
"""
optimizer = Adafactor(
self.parameters(),
lr=self.hparams.learning_rate,
relative_step=False,
scale_parameter=False,
)
return optimizer
```
and my Trainer is initialised with a config file:
```
class_path: pytorch_lightning.trainer.trainer.Trainer
init_args:
accelerator: gpu
strategy: deepspeed_stage_2
devices: 1
num_nodes: 1
precision: 16
accumulate_grad_batches: 4
fast_dev_run: False
max_epochs: 10
min_epochs: 1
max_steps: -1
min_steps: null
max_time: null
limit_train_batches: 1.0
limit_val_batches: 1.0
limit_test_batches: 1.0
limit_predict_batches: 1.0
overfit_batches: 0
val_check_interval: 1.0
check_val_every_n_epoch: 1
num_sanity_val_steps: 3
log_every_n_steps: 50
enable_progress_bar: true
enable_model_summary: true
gradient_clip_val: 1.0
gradient_clip_algorithm: norm
deterministic: false
benchmark: null
inference_mode: true
use_distributed_sampler: true
profiler: null
detect_anomaly: false
barebones: false
sync_batchnorm: false
reload_dataloaders_every_n_epochs: 0
default_root_dir: null
```
Honestly I don't know what I am doing wrong or if this is a bug. I don't find enough examples on how to use deepspeed with pytorch-Lightning.
### How to reproduce the bug
_No response_
### Error messages and logs
```
# Error messages and logs here please
```
### Environment
Current environment
```
#- Lightning Component (e.g. Trainer, LightningModule, LightningApp, LightningWork, LightningFlow):
#- PyTorch Lightning Version (e.g., 1.5.0):
#- Lightning App Version (e.g., 0.5.2):
#- PyTorch Version (e.g., 2.0):
#- Python version (e.g., 3.9):
#- OS (e.g., Linux):
#- CUDA/cuDNN version:
#- GPU models and configuration:
#- How you installed Lightning(`conda`, `pip`, source):
#- Running environment of LightningApp (e.g. local, cloud):
```
### More info
My dependencies are:
[tool.poetry.dependencies]
python = "^3.8.0"
sentencepiece = "^0.1.96"
pandas = "^1.4.1"
transformers = "^4.17"
pytorch-lightning = "^2.0.0"
jsonargparse = "3.13.1"
torch = "^1.6.0"
numpy = "^1.20.0"
torchmetrics = "^0.11.3"
sacrebleu = "^2.0.0"
scipy = "^1.5.4"
entmax = "^1.1"
huggingface-hub = "^0.12.0"
tensorboard = "^2.12.0"
cc @lantiga
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
The issue provides no reproduction, logs, environment, or named source or test files. Start with the shown configure_optimizers method and Trainer YAML, reproducing the small-dataset comparison between strategy=auto and deepspeed_stage_1/2; done means a confirmed cause or actionable maintainer diagnosis.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, pytorch
- Domain
- distributed-systems, machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100