Lightning-AI / Lightning-AI/pytorch-lightning
Add a callback to loggers called after removing a checkpoint
Nobody has claimed this yet.
- Dominant language
- Python
- Stars
- 31.4k
- Forks
- 3.8k
- Avg merge
- 6d 7h
- Merged PRs (30d)
- 6
Description
Edit:
Editing this to add slightly more context as this issue went slightly stale and this issue really handicaps the usability of WandbLogger.
Description & Motivation
When using ModelCheckpoint(save_top_k=3) and WandbLogger(log_model="all") you end up with only top 3 models saved locally, but multiple models uploaded to wandb, which feels like a buggish behavior.
This is because currently loggers are notified after a checkpoints is saved, but are NOT notified after a checkpoint is removed. This could be solved, by adding a callback so that a logger knows, when a checkpoint is removed.
Described behavior is obviously undesirable because it creates tons of unnecessary checkpoints stored in a cloud.
Using log_model=True is not really a solution to this problem, because it defers uploading model until the training is complete and works ONLY when the training succeeds, so no checkpoints if your training crashes at any point.
Pitch
Add a callback to loggers that is called after a checkpoint is removed to allow for removal of uploaded artifacts by a logger.
This callback would presumably require a path to deleted checkpoint to be passed as an argument, but it seems like a reasonable aporoach.
Then modify WandbLogger to remove deprecated uploaded artifacts from the could.
Then log_model="all" mode could be replaced with log_model="immediate", and possibly log_model=True with log_model="end", as that would be more appropriate naming, and more in-line with the description in the docs.
Alternatives
WandbLogger could scan for local checkpoints and remove non-existent ones from the cloud without the need to actually add another callback method. This however seems like a slightly hacky solution.
Additional context
I'd be willing to write a PR for this if given an approval that is makes sense.
cc @borda @tchaton @justusschock @awaelchli @morganmcg1 @borisdayma @scottire @parambharat
Example
Given code:
import torch
import lightning
import lightning.pytorch.callbacks
import lightning.pytorch.loggers
import wandb


class MockLightningModule(lightning.LightningModule):
    def __init__(self) -> None:
        super().__init__()
        self.layer = torch.nn.Linear(1, 1)
        self.scores_in_each_epoch = [
            10, 9, 8, 7, 6, 5, 4, 3, 2, 1
        ]

    def training_step(self, batch):
        return self.layer(batch)

    def validation_step(self, batch, batch_index):
        self.log("mock_score", self.scores_in_each_epoch[self.current_epoch])

    def configure_optimizers(self):
        return torch.optim.Adam(self.parameters())


class MockDataModule(lightning.LightningDataModule):
    def train_dataloader(self):
        return torch.utils.data.DataLoader(torch.range(0, 10))

    def val_dataloader(self):
        return torch.utils.data.DataLoader(torch.range(0, 10))


def run_mock_wandb_training(should_crash: bool, log_model):
    dm = MockDataModule()
    model = MockLightningModule()

    logger = lightning.pytorch.loggers.WandbLogger(project='mock_project', log_model=log_model, name=f"{should_crash=}-{log_model=}")
    callback = lightning.pytorch.callbacks.ModelCheckpoint(save_top_k=3, monitor="mock_score", mode="min")

    if should_crash:
        max_epochs = 11
    else:
        max_epochs = 10

    trainer = lightning.Trainer(max_epochs=max_epochs, callbacks=callback, logger=logger)
    try:
        trainer.fit(model, datamodule=dm)
    except:
        # this training is supoorsed to fail, so it's okay
        pass
    logger._experiment.finish()


run_mock_wandb_training(should_crash=False, log_model=True)
run_mock_wandb_training(should_crash=False, log_model="all")
run_mock_wandb_training(should_crash=True, log_model=True)
run_mock_wandb_training(should_crash=True, log_model="all")
You get:
3 checkpoints
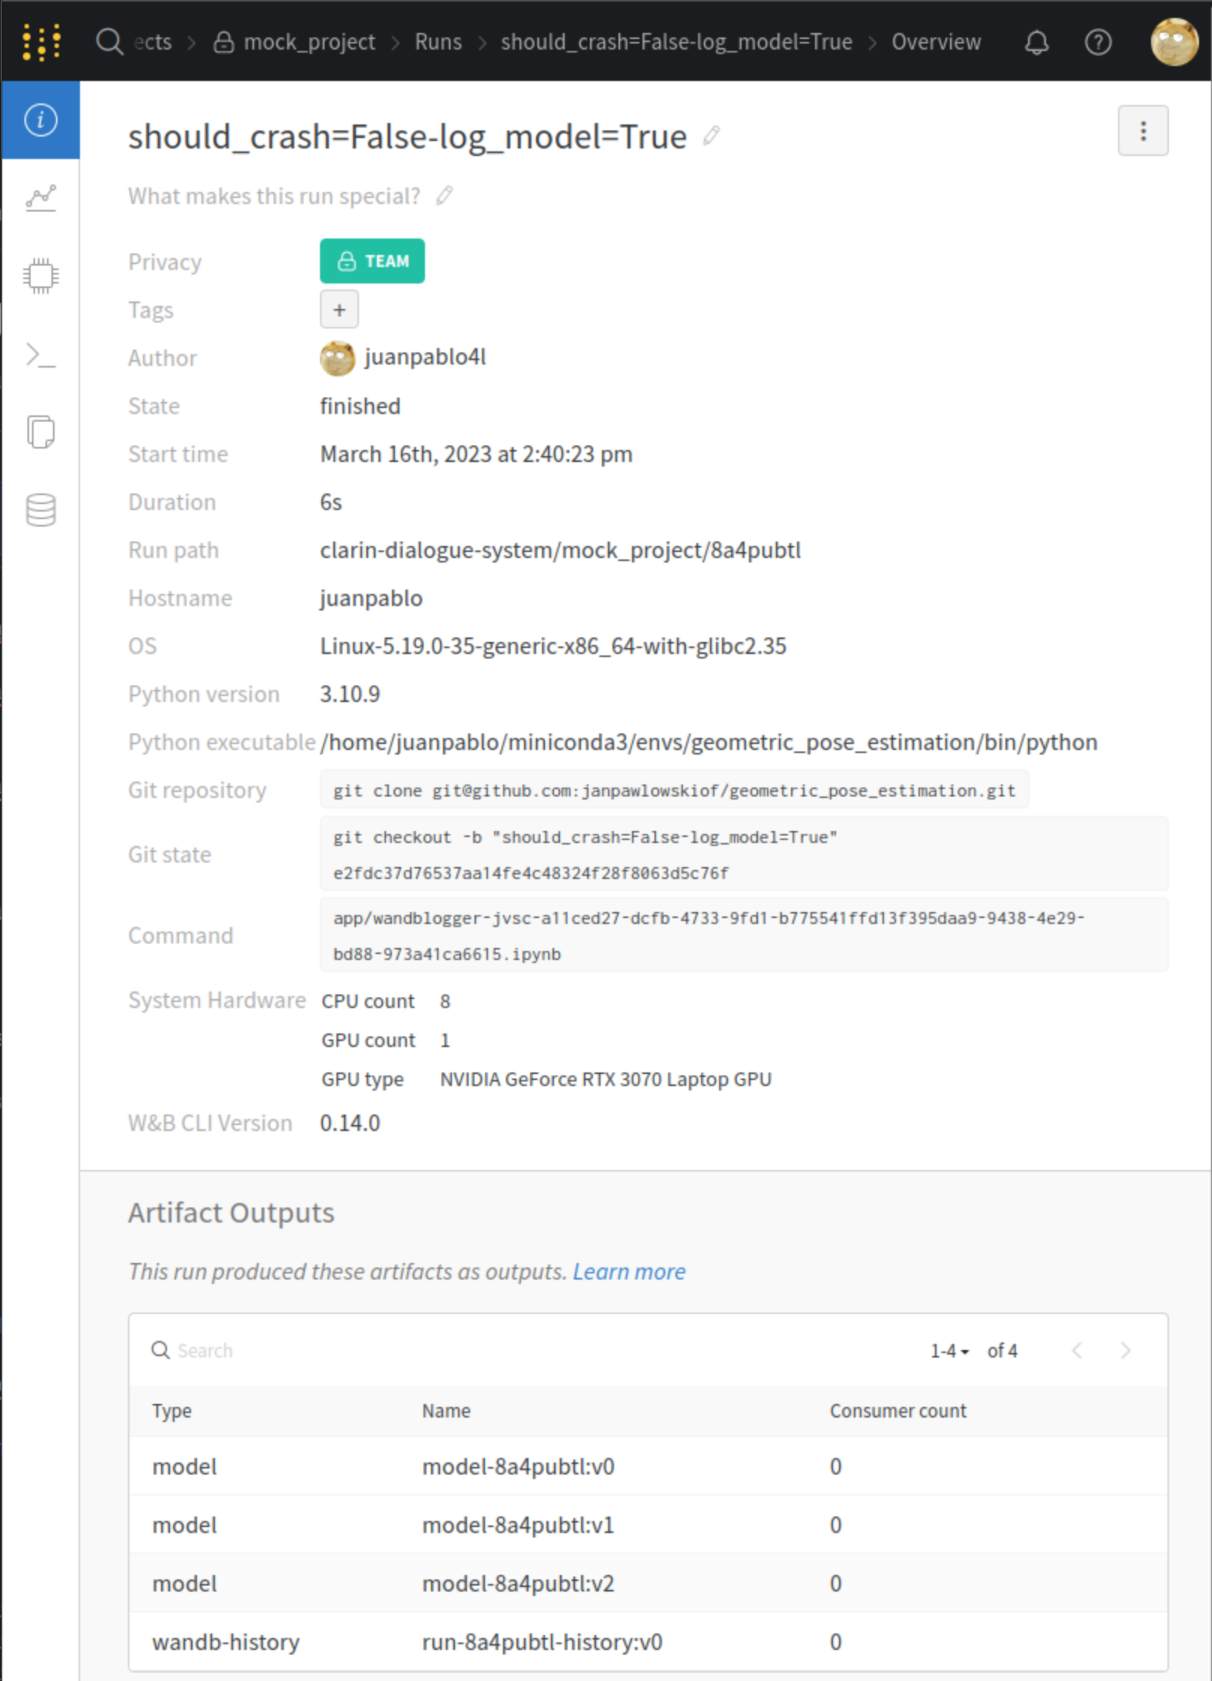
10 checkpoints:
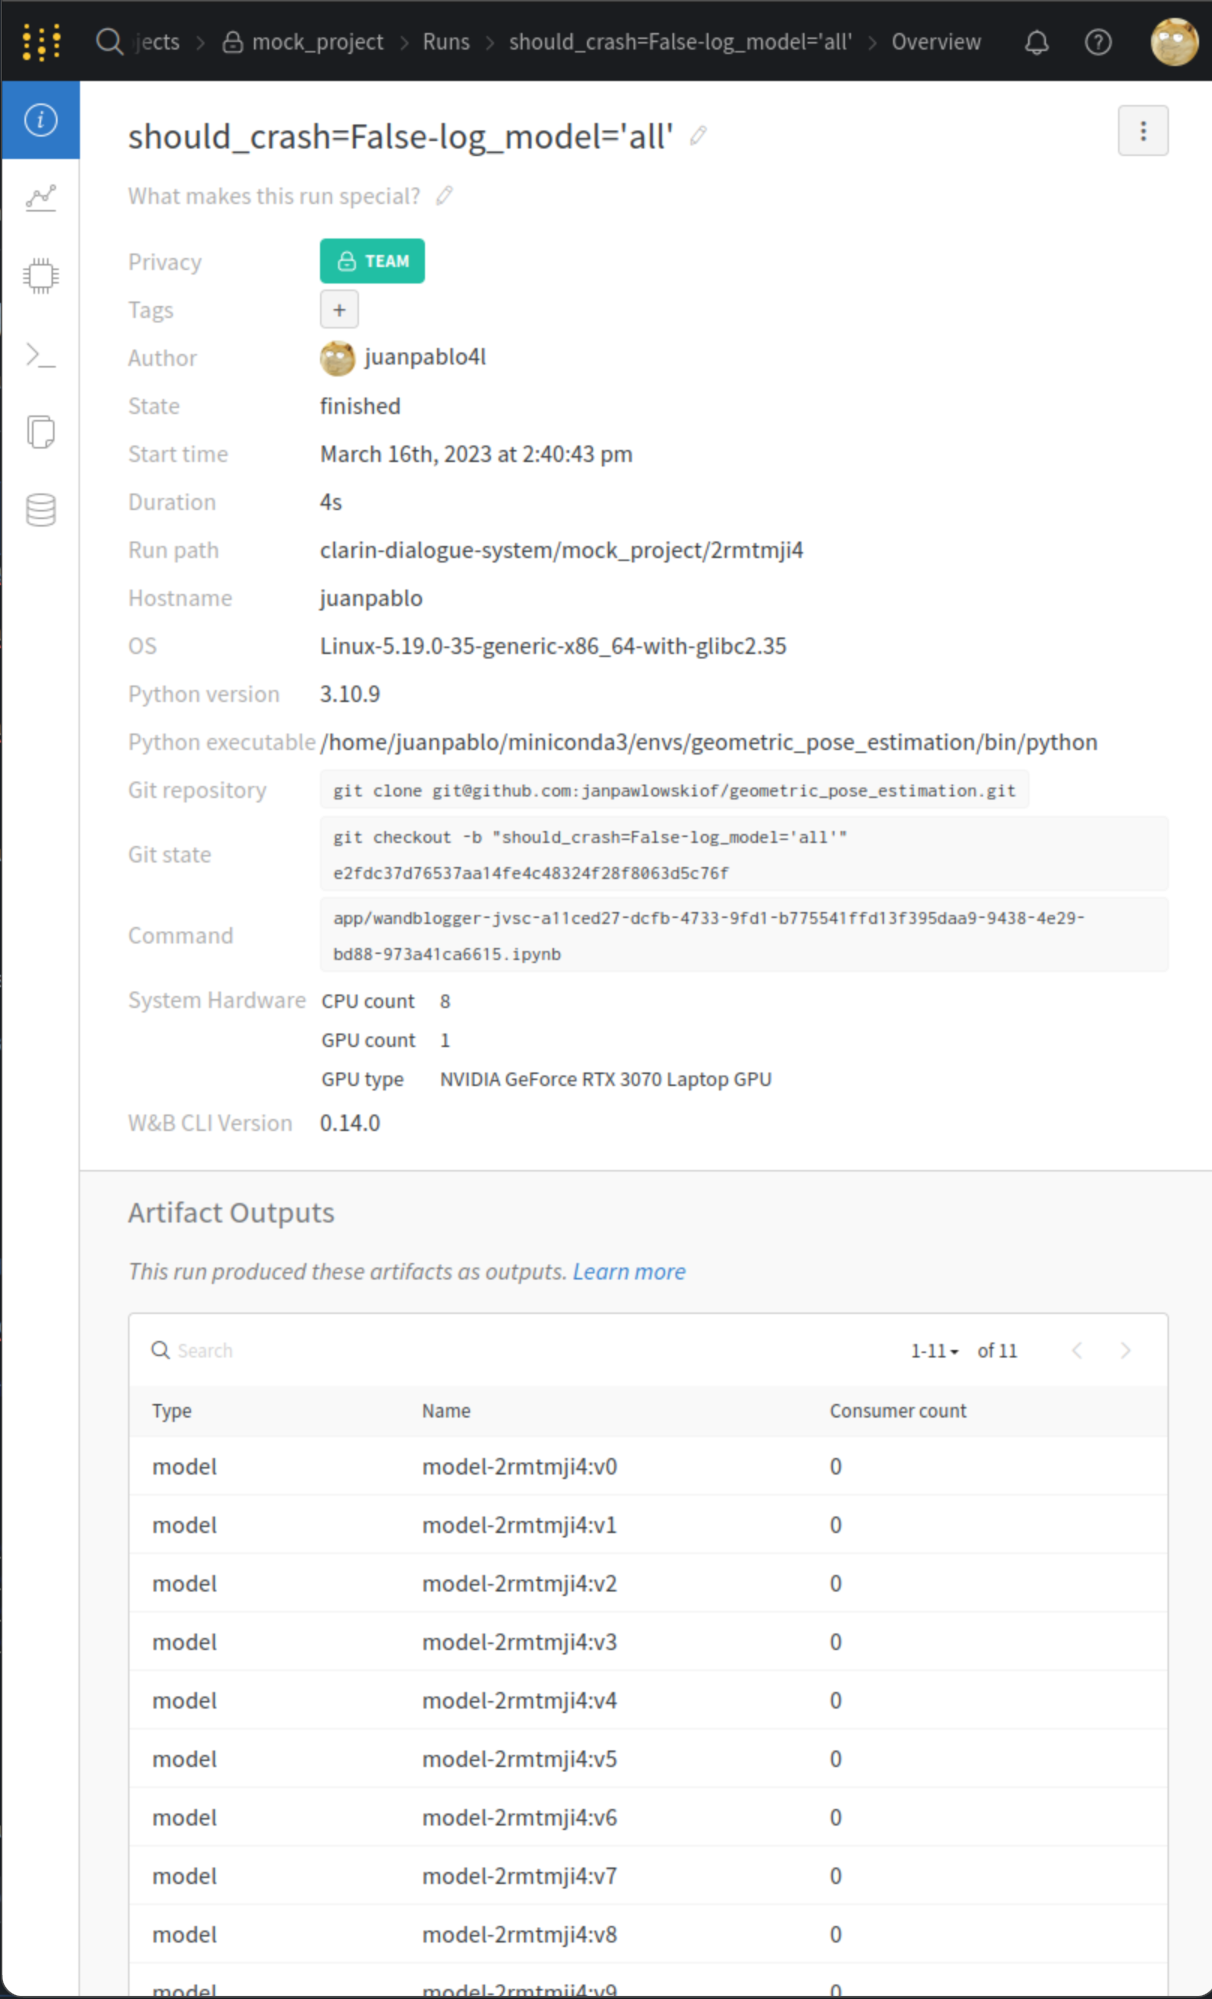
0 checkpoints:
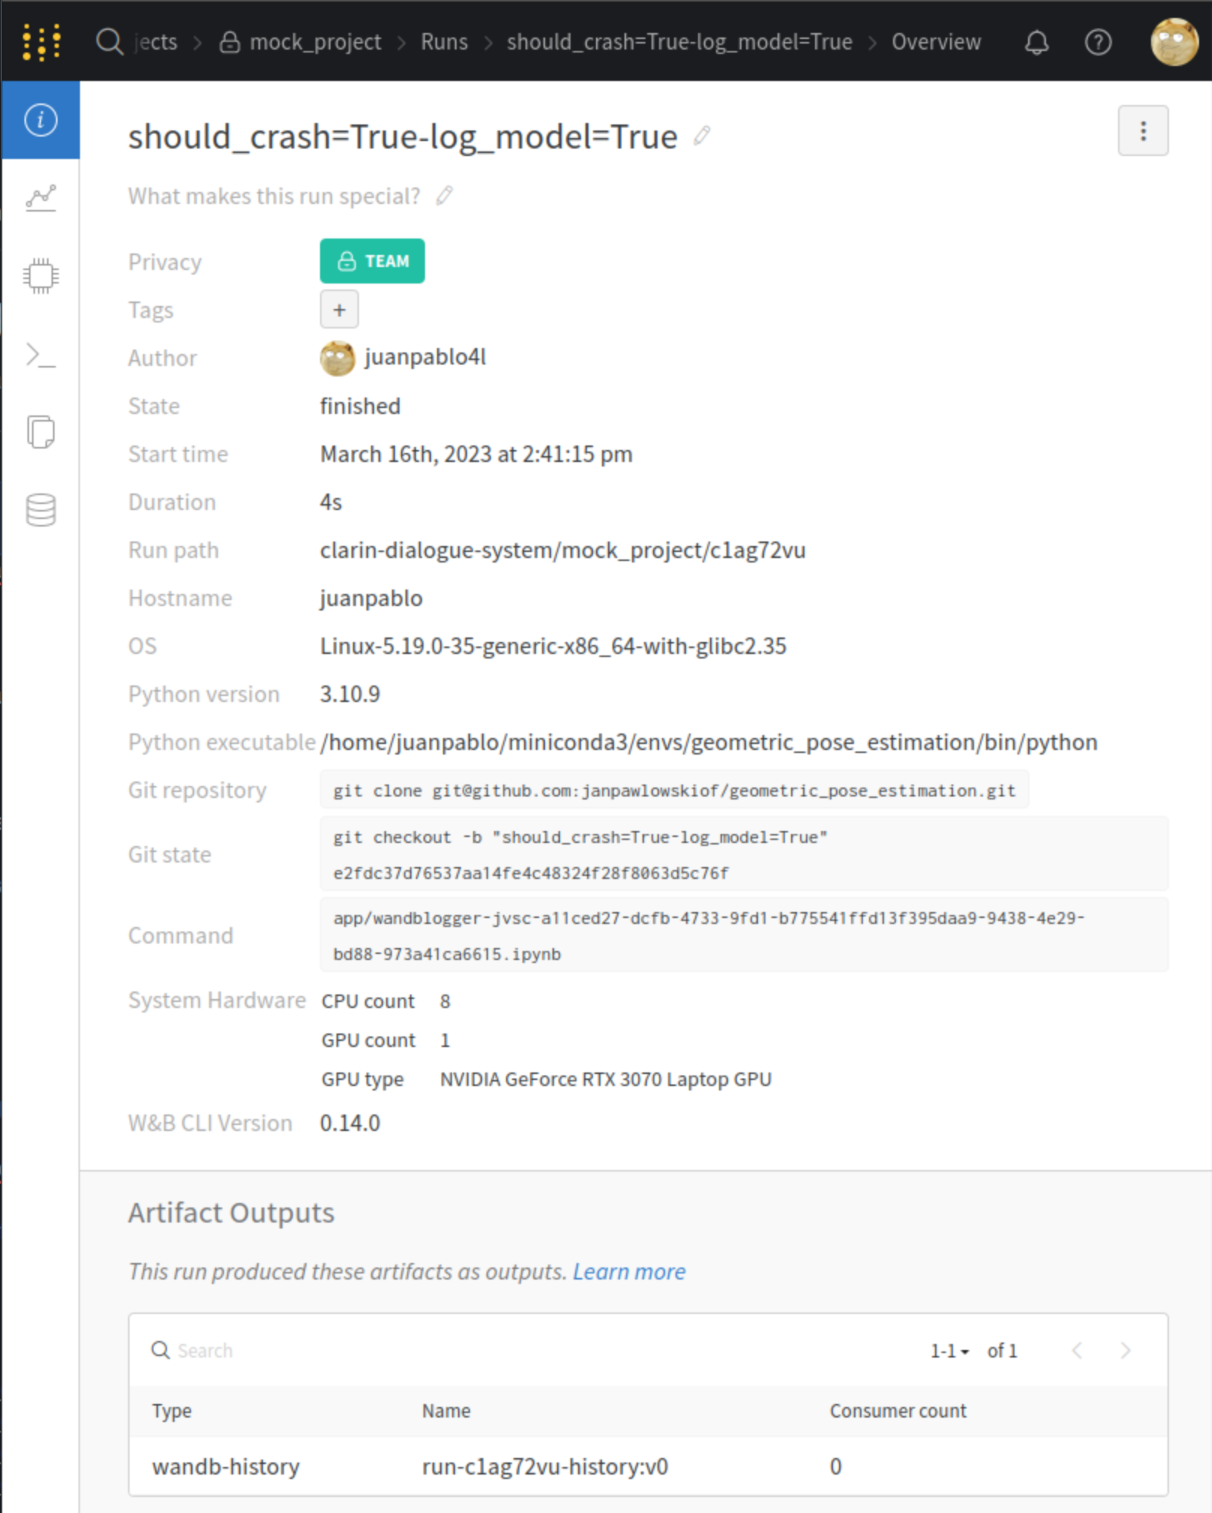
10 checkpoints:
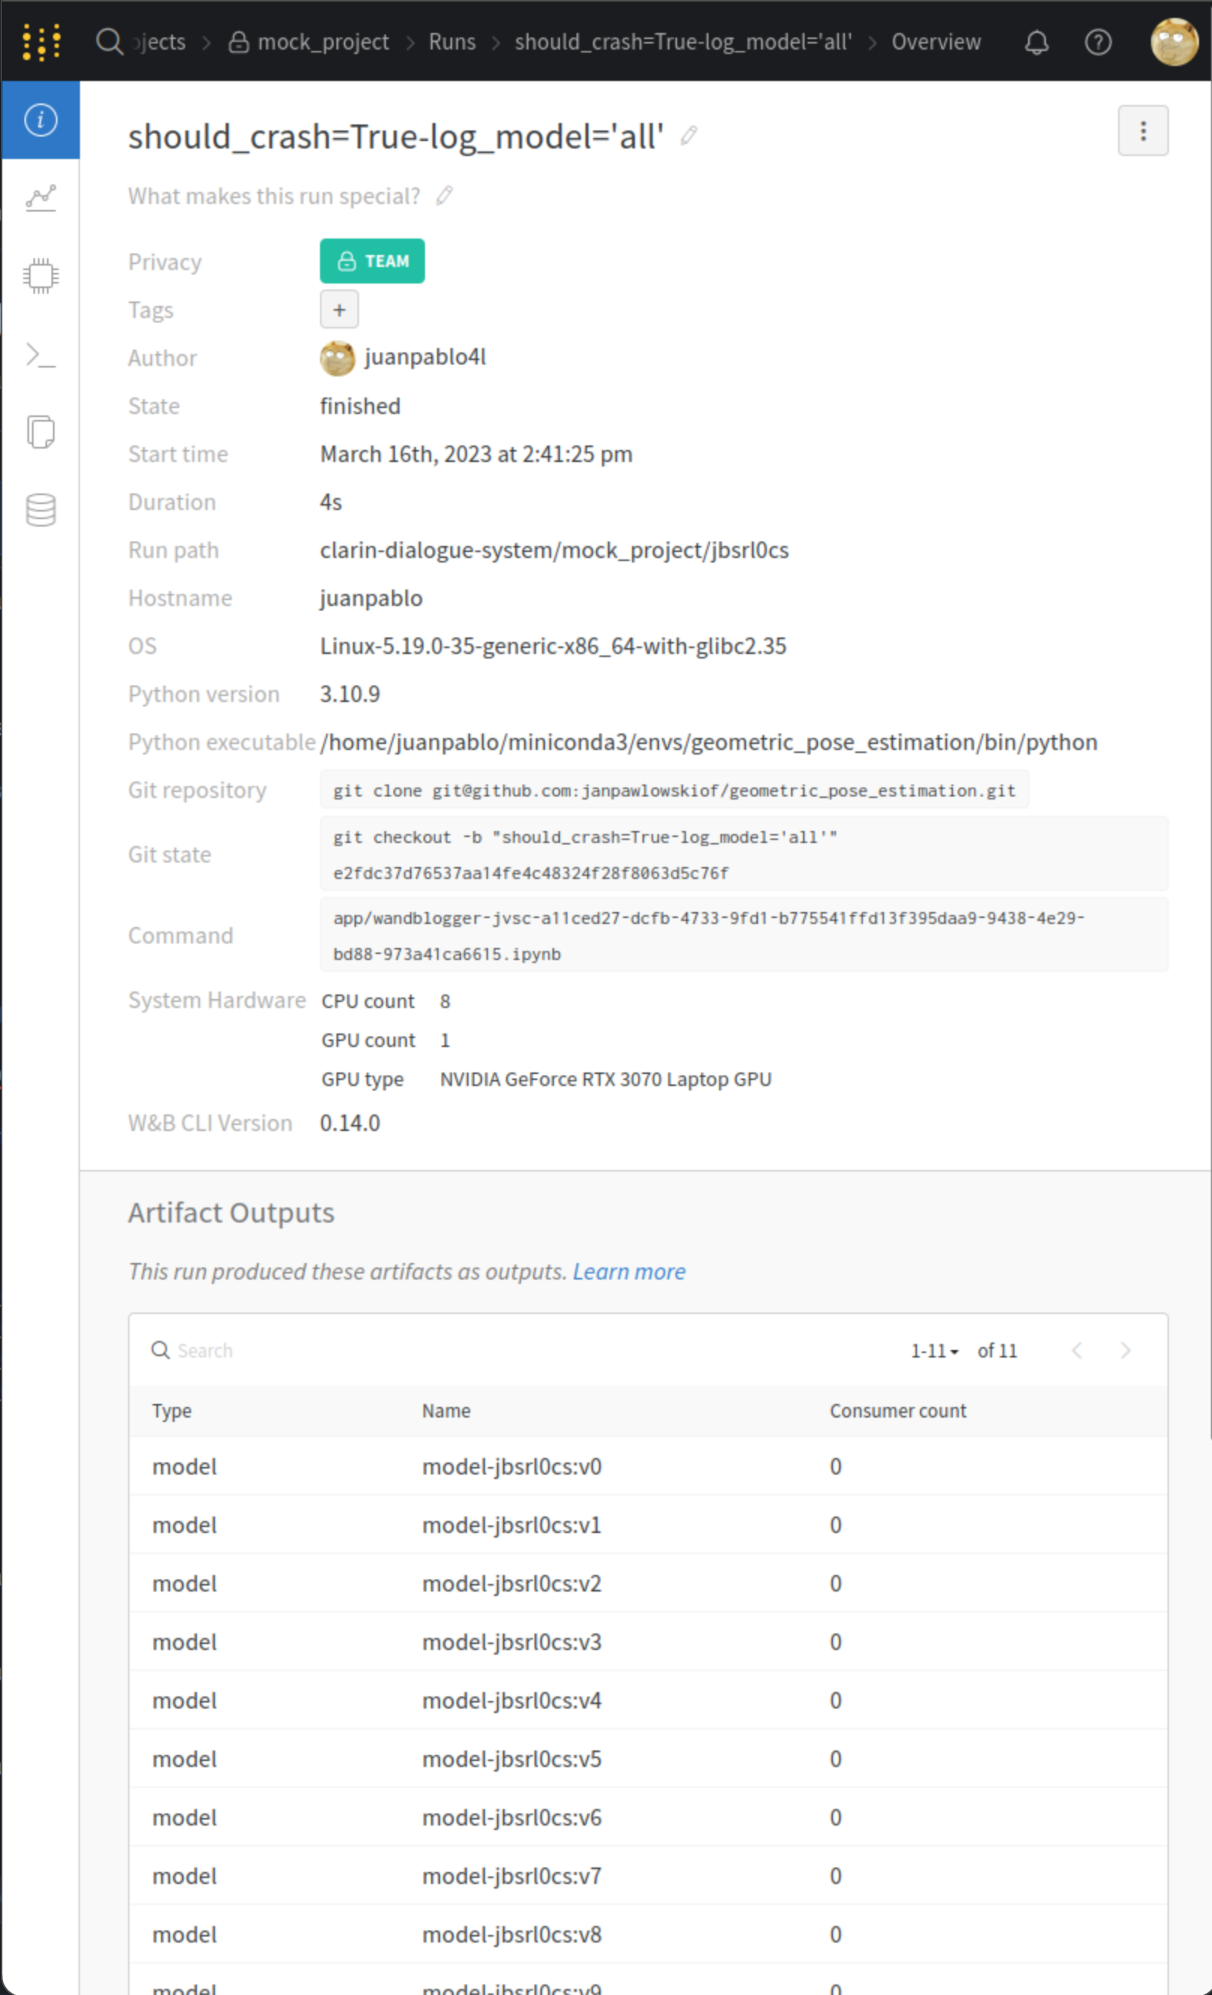
Contributor guide
First steps
- Read the whole issue, then the project's contributing guide.
- Comment on the issue to say you are picking it up — it saves two people doing the same work.
- Fork the repository and make your change on a branch.
- Open a pull request that references the issue number.
Research direction
Start by tracing ModelCheckpoint's checkpoint-removal flow and WandbLogger's existing checkpoint notification behavior. Determine the callback contract and how removed checkpoints should be handled by log_model="all"; done means the logger can remove corresponding uploaded artifacts while retaining the intended behavior for other log_model modes.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python
- Domain
- machine-learning
- Issue type
- Feature
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Mostly clear
- Newbie friendliness
- 35/100