JessYanCoding / JessYanCoding/hf-trending-mirror
trending-data (auto-updated daily; do not close)
- Dominant language
- No language data
- Stars
- 0
- Forks
- 0
- PR merge metrics
- No merged PRs in 30d
Description
{"fetchedAt": "2026-09-18T00:33:59.657507Z", "models": [{"id": "Edge0/Edge0-35B-A3B-preview", "pipeline_tag": "text-generation", "downloads": 37131, "likes": 3305, "last_modified": "2026-09-17T04:37:15.000Z", "tags": ["mlx", "safetensors", "qwen3_5_moe", "moe", "edge-inference", "prerouter", "lora", "ssd-offload", "text-generation", "conversational"], "readme": "---\nlicense: apache-2.0\nlibrary_name: mlx\ntags:\n- moe\n- edge-inference\n- prerouter\n- lora\n- ssd-offload\nbase_model:\n- Qwen/Qwen3.6-35B-A3B\npipeline_tag: text-generation\n---\n\n
 \n\n
Edge0-35b-a3b Preview
\n\n**A 35B-class sparse MoE that runs in phone-class memory.**\n\n**3 GiB active memory · 15 tok/s · 4-bit**\n\n[](https://github.com/Edge0-AI/edge0)\n[](https://huggingface.co/Edge0/Edge0-35b-a3b-preview)\n[](https://huggingface.co/Edge0/Edge0-8b-a1b-preview)\n[](https://www.modelscope.cn/models/Edge0/Edge0-35B-A3B-preview)\n[](https://www.modelscope.cn/models/Edge0/Edge0-8B-A1B-preview)\n[](https://arxiv.org/abs/2609.18063)\n[](https://github.com/Edge0-AI/edge0/blob/main/LICENSE)\n\n \n
\n\n\n
 \n
 \n
 \n
 \n
 \n \n
 \n
🤗 YuE2-3B
\nFrontier music generation with editable scores
\n\n\n 

\n 🎧 Demo\n ·\n 🗳️ Music Arena\n ·\n 🚀 Quick start\n ·\n 🎙️ Cover\n ·\n 🤖 Edit\n ·\n ⚡ Speed\n ·\n 📊 Benchmarks\n ·\n 📚 Citation\n
\n\n 


\n
NeoHorse-1-4B
\nTowards Recursive Self-Improvement via Agentic Post-Training with Routing Harness.
\n


\n Technical Report\n
\n\n\n/* Reusable benchmark table architecture. Inline styles remain as a fallback for HF rendering. */\n.vl-table {\n width: 100%;\n min-width: 100%;\n border-collapse: collapse;\n table-layout: fixed;\n font-size: 15px;\n}\n.vl-table th {\n font-size: 15px !important;\n line-height: 1.2;\n color: #c2410c;\n background: rgba(249,115,22,.10);\n}\n.vl-table td:not(.benchmark-cell):not([colspan]) {\n font-size: 15px;\n line-height: 1.2;\n vertical-align: middle;\n}\n.vl-table .benchmark-cell {\n padding: 12px", "params_total": null}, {"id": "ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1027602, "likes": 1259, "last_modified": "2026-09-02T09:11:34.000Z", "tags": ["gguf", "gsq", "rco", "quantization", "mixed-precision", "ist-daslab", "multimodal", "vision", "image-text-to-text", "arxiv:2604.18556"], "readme": "---\nbase_model: Qwen/Qwen3.8-27B\nbase_model_relation: quantized\npipeline_tag: image-text-to-text\nlibrary_name: gguf\nlicense: apache-2.0\ntags:\n- gguf\n- gsq\n- rco\n- quantization\n- mixed-precision\n- ist-daslab\n- multimodal\n- vision\n---\n\n<!--\n GSQ-RCO GGUF release card, TEMPLATE (filled with Qwen3.8-27B as the example).\n To publish a new model, copy this folder and change only:\n 1. the YAML frontmatter above (base_model, license)\n 2. every field marked [swap] (model name, filenames, one-line summaries)\n 3. the results: drop tools/results/<model>.json, run\n python tools/make_plots.py tools/results/<model>.json\n then paste the printed Markdown table into \"Results\".\n The header (banner + badges) is shared across all releases.\n NB: the YAML block must remain the very first bytes of the file (HF requirement).\n-->\n\n<div align=\"center\">\n\n<a href=\"https://github.com/IST-DASLab\"><img src=\"https://huggingface.co/ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF/resolve/main/assets/banner.png\" alt=\"GGUF, GSQ-RCO dynamic non-uniform quantization\" width=\"100%\"/></a>\n\n<br/>\n\n# Qwen3.8-27B · GSQ-RCO GGUFs\n\n**Non-uniform GGUF quantizations** produced with **GSQ** and **RCO**, with a vision projector for multimodal use.\n\n[](https://arxiv.org/abs/2604.18556)\n[](https://arxiv.org/abs/2605.00649)\n[](https://github.com/IST-DASLab/GSQ)\n[](https://github.com/IST-DASLab/RCO)\n[](https://github.com/IST-DASLab)\n[](#license)\n\n</div>\n\n and\n consent to receive offers and updates including targeted and personalized advertisements.\n You can unsubscribe at any time.\nextra_gated_button_content: Agree and Access\n---\n\n<!-- LTX-2.5 model card — license-first redesign. YAML frontmatter above kept intact. -->\n\n<div class=\"lg:-mr-20 xl:-mr-24 2xl:-mr-36\" style=\"border-radius:14px;overflow:hidden;\">\n<div style=\"position:relative;line-height:0;font-size:0;height:300px;\">\n<img src=\"https://huggingface.co/Lightricks/LTX-2.5/resolve/main/hf-hero-web.webp\" alt=\"LTX-2.5 — Video, Audio & World Simulation\" style=\"display:block;width:100%;height:100%;object-fit:cover;margin:0;vertical-align:top;\" />\n<video autoplay muted loop playsinline style=\"position:absolute;inset:0;width:100%;height:100%;object-fit:cover;\">\n<source src=\"https://videos.ltx.io/LTX-2/ltx-research/hf-hero-web.mp4\" type=\"video/mp4\" />\n<source src=\"https://videos.ltx.io/LTX-2/ltx-research/hf-hero-web.webm\" type=\"video/webm\" />\n</video>\n</div>\n<!-- light hero footer -->\n<div class=\"dark:hidden\" style=\"background-color:#eef1f5;padding:2rem 1.5rem 2.4rem;text-align:center;isolation:isolate;\">\n<h1 style=\"color:#0a0a0a;margin:0 0 0.5rem;font-size:2rem;font-weight:700;letter-spacing:-0.01em;bo", "params_total": null}, {"id": "openbmb/MiniCPM5-2B", "pipeline_tag": "text-generation", "downloads": 329713, "likes": 1537, "last_modified": "2026-09-12T07:20:14.000Z", "tags": ["transformers", "safetensors", "llama", "text-generation", "minicpm", "minicpm5", "long-context", "tool-calling", "on-device", "edge-ai"], "readme": "---\nlicense: apache-2.0\nlanguage:\n- en\n- zh\nlibrary_name: transformers\npipeline_tag: text-generation\ntags:\n- minicpm\n- minicpm5\n- llama\n- text-generation\n- long-context\n- tool-calling\n- on-device\n- edge-ai\ndatasets:\n- openbmb/Ultra-FineWeb\n- openbmb/UltraX-Preview\n- openbmb/Ultra-FineWeb-L3\n- openbmb/UltraData-Math\n- openbmb/UltraData-Code\n- openbmb/UltraData-SFT-2605\n- openbmb/UltraData-SFT-Agent-2609\n- openbmb/UltraData-RL-2609\n---\n\n<div align=\"center\">\n<img src=\"https://raw.githubusercontent.com/OpenBMB/MiniCPM/main/assets/minicpm_logo.png\" width=\"500em\" />\n</div>\n\n<p align=\"center\">\n<a href=\"https://arxiv.org/pdf/2506.07900\" target=\"_blank\">MiniCPM Tech Report</a> |\n<a href=\"https://modelbest.feishu.cn/wiki/UtWxwcERfiRIpIkBOjuc3h9tn1D\" target=\"_blank\">MiniCPM Wiki(Chinese)</a> |\n<a href=\"https://github.com/OpenBMB/MiniCPM\" target=\"_blank\">GitHub Repo</a> |\n<a href=\"https://ultradata.openbmb.cn/\" target=\"_blank\">UltraData</a> |\n<a href=\"https://huggingface.co/spaces/openbmb/MiniCPM5-2B-Demo\" target=\"_blank\">Online Demo</a>\n</p>\n\n<p align=\"center\">\nEnglish |\n<a href=\"https://huggingface.co/openbmb/MiniCPM5-2B/blob/main/README-cn.md\" target=\"_blank\">中文</a>\n</p>\n\n## Highlights\n\nWe are releasing **MiniCPM5-2B**, the second model in the **MiniCPM5** series, following [MiniCPM5-1B](https://huggingface.co/openbmb/MiniCPM5-1B). It is a dense 2B Transformer that scales up the same training recipe, built for on-device, local deployment, and resource-constrained scenarios, reaching 2B-class open-source SOTA.\n\n🏆 **2B-class open-source SOTA**: compared with strong open-source models of similar size, MiniCPM5-2B achieves SOTA performance within this comparison set. It remains competitive with 4B-class models overall, while showing its advantages over models of comparable size in coding, mathematics, long-context understanding, tool use, and agentic tasks.\n\n<div id=\"capability-comparison-radar\" class=\"radar-visual\" role=\"img\" aria-label=\"Capability radar chart comparing MiniCPM", "params_total": null}, {"id": "ukisai/Swift-Qwen3.8-27b", "pipeline_tag": "image-text-to-text", "downloads": 3221, "likes": 392, "last_modified": "2026-09-16T15:20:16.000Z", "tags": ["transformers", "safetensors", "qwen3_5", "image-text-to-text", "qwen3_8", "efficient-thinking", "reasoning", "token-efficient", "lora", "conversational"], "readme": "---\nlicense: other\nlicense_name: swift-open-license-1.0\nlicense_link: https://huggingface.co/ukisai/Swift-Qwen3.8-27b/blob/main/LICENSE\nlibrary_name: transformers\npipeline_tag: image-text-to-text\ngated: true\ntags:\n- qwen3_8\n- efficient-thinking\n- reasoning\n- token-efficient\n- lora\nbase_model: Qwen/Qwen3.8-27B\nbase_model_relation: finetune\n---\n\n<div align=\"center\">\n <a href=\"https://ukisai.com\"><img src=\"ukisai-banner.png\" alt=\"UkisAI\" style=\"width:100%;max-width:100%;height:auto;display:block;margin-bottom:0.6em;\" /></a>\n <div style=\"display:flex;justify-content:center;gap:0.6em;margin-bottom:1em;\">\n <a href=\"https://ukisai.com\"><strong>Website</strong></a> • \n <a href=\"https://ukisai.com/products/swift\"><strong>Learn more</strong></a> • \n <a href=\"https://huggingface.co/ukisai/Swift-Qwen3.8-27B-GGUF\"><strong>GGUF</strong></a> • \n <a href=\"#license-and-access\"><strong>Enterprise licensing</strong></a>\n </div>\n</div>\n\n# Swift-Qwen3.8-27B\n\nSwift-Qwen3.8-27B is UkisAI's reasoning-efficient derivative of Qwen3.8-27B,\nusing **58.3% fewer thinking tokens** while maintaining near-identical performance\n(**<1% loss**) and as a result getting a **x1.95 speed-up** on several tasks.\n\n<video controls autoplay muted loop playsinline style=\"width:100%;max-width:100%;height:auto;display:block;border-radius:12px;margin:0.8em 0 1.4em;\" src=\"https://huggingface.co/ukisai/Swift-Qwen3.8-27b/resolve/main/swift-speed-demo.mp4\"></video>\n<p align=\"center\" style=\"font-size:13px;color:#8C94A8;margin:-0.6em 0 1.4em;\">The prompt is a sample from LiveCodeBench v6</p>\n\n## Training approach\n\nWe built Swift by identifying reasoning-marker tokens that, in our analysis, trigger overthinking in Qwen’s\nreasoning rollouts. We then fine-tuned Qwen by penalizing usage of those tokens while it reasons.\n\nSwift produces shorter reasoning traces. In our testing, we also observe fewer overthinking errors.\n\nFor maximum gains, Swift also includes ", "params_total": null}, {"id": "DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF", "pipeline_tag": "image-text-to-text", "downloads": 1116038, "likes": 844, "last_modified": "2026-09-16T23:56:33.000Z", "tags": ["gguf", "unsloth", "fine tune", "heretic", "uncensored", "abliterated", "ara", "MTP GGUF Quants", "Regular GGUF Quants", "qwen3_8"], "readme": "---\nlanguage:\n- en\n- zh\nlicense: apache-2.0\ntags:\n- unsloth\n- fine tune\n- heretic\n- uncensored\n- abliterated\n- ara\n- MTP GGUF Quants\n- Regular GGUF Quants\n- qwen3_8\n- qwen3_6\n- qwen3_5\n- multi-stage tuned\n- thinking\n- reasoning\n- all use cases\n- coder\n- creative\n- creative writing\n- all genres\n- story\n- writing\n- fiction\n- roleplaying\n- bfloat16\n- multi-stage-tune\n- multi-state-merge\ndatasets:\n- DavidAU/Polar-STRICT-Datasets\n- DavidAU/F451-STRICT-Datasets\npipeline_tag: image-text-to-text\nbase_model:\n- DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU\n---\n\n<small><b><font color=\"red\">Important:</font></b> This is the first fine tune to exceed 730 \"arc-c\" (\"735\": 144 pts higher than Qwen 3.8 27B) AND 880 ARC-E (The OpenAI, Claude and Gemini \"zone of intelligence\") \nin 8 bit and over 718 arc-c in 4 bit. This version is called TURBO because it drastically reduces thinking tokens (by 1/2 to as high as 1/10), yet maintains output detail and quality. \nIn otherwords while \"reg\" Qwen3.8 27B is thinking about \"formatting\" for a few 1000 tokens, this model is already done and waiting for more.\nThis repo contains both \"regular\" and \"MTP\" Neo-CODER MAX DI-MATRIX (duel imatrix) GGUF quants. \n\nNOTE: Please see the \"community\" tab for user experiences, additional third party benchmarks (including strongest tool calling performance ever recorded), \nand other quant versions (also see \"Quantized\" in the right \"model tree\" too).</small>\n\n<h2>Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF</h2>\n\n<img src=\"star-wars-hans-solo.gif\" style=\"float:right; padding:10px;\">\n\nThe strongest, smartest open source multi-stage model fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth.\n\nThe first model of this size/type to breach \"730\" ARC-C in 8 bit (735) and 4 bit (719); hench the \"735\" in the name.\n\nThis model has 1/5 (as low as 1/10 in some cases) to 1/2 the thinking tokens (vs reg Qwen 3.8) across all 3 ", "params_total": null}, {"id": "unsloth/Qwen3.8-27B-GGUF", "pipeline_tag": null, "downloads": 8205000, "likes": 4267, "last_modified": "2026-08-20T12:04:25.000Z", "tags": ["gguf", "qwen3_5", "unsloth", "base_model:Qwen/Qwen3.8-27B", "base_model:quantized:Qwen/Qwen3.8-27B", "license:apache-2.0", "endpoints_compatible", "region:us", "imatrix", "conversational"], "readme": "---\nbase_model:\n- Qwen/Qwen3.8-27B\nlicense: apache-2.0\ntags:\n- unsloth\n---\n\n# Read our How to [Run Qwen3.8-27B Guide!](https://unsloth.ai/docs/models/qwen3.8)\n<div>\n <p style=\"margin: 0 0 0px 0; margin-top: 0px;\">\n <em><a href=\"https://unsloth.ai/docs/basics/dynamic-3.0-ggufs\">Unsloth Dynamic 3.0</a> achieves superior accuracy & outperforms other leading quants.</em>\n </p>\n <div style=\"display: flex; gap: 5px; align-items: center; margin-bottom: 0px;\">\n <a href=\"https://github.com/unslothai/unsloth/\">\n <img src=\"https://github.com/unslothai/unsloth/raw/main/images/unsloth%20new%20logo.png\" width=\"133\">\n </a>\n <a href=\"https://discord.gg/unsloth\">\n <img src=\"https://github.com/unslothai/unsloth/raw/main/images/Discord%20button.png\" width=\"173\">\n </a>\n <a href=\"https://unsloth.ai/docs/models/qwen3.8\">\n <img src=\"https://raw.githubusercontent.com/unslothai/unsloth/refs/heads/main/images/documentation%20green%20button.png\" width=\"143\">\n </a>\n </div>\n <ul style=\"margin: 0;\">\n <li>Introducing <a href=\"https://unsloth.ai/docs/basics/dynamic-3.0-ggufs\">Dynamic V3.0</a> GGUFs for SOTA accuracy and quantization performance</li>\n <li>Run and fine-tune Qwen3.8 in <a href=\"https://unsloth.ai/docs/new/desktop\">Unsloth Desktop</a> with <strong>Thinking toggles</strong>. <a href=\"https://unsloth.ai\">Download</a> for Mac, Windows and Linux.</a> <a href=\"github.com/unslothai/unsloth\">GitHub repo</a></li>\n <li>Developer Role Support so Qwen3.8 can work in agentic tools like Codex and more!</li>\n <li>Tool calling improvements: Makes parsing nested objects to make tool calling succeed more.</li>\n <li>See below for 4-bit Qwen3.8-27B run inside of Unsloth Desktop:</li>\n</div>\n\n<img width=\"600\" alt=\"qwen3.8 unsloth desktop\" src=\"https://3215535692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FxhOjnexMCB3dmuQFQ2Zq%2Fuploads%2FSqxs6NjShWrLfRKhDy1m%2Fvolcano%202.gif?alt=media&token=395274a0-b437-403a-8a01-8e8502f9d", "params_total": null}, {"id": "harshatheg/Qwen-2.5-1B-RLCD", "pipeline_tag": "text-generation", "downloads": 0, "likes": 259, "last_modified": "2026-09-16T06:23:02.000Z", "tags": ["mlx", "structured-generation", "parallel-decoding", "constrained-decoding", "apple-silicon", "classification", "json", "text-generation", "en", "base_model:Qwen/Qwen2.5-1.5B-Instruct"], "readme": "---\nlanguage:\n- en\nlicense: apache-2.0\nlibrary_name: mlx\ntags:\n- structured-generation\n- parallel-decoding\n- constrained-decoding\n- apple-silicon\n- mlx\n- classification\n- json\npipeline_tag: text-generation\nbase_model: Qwen/Qwen2.5-1.5B-Instruct\nspaces:\n- drinkmoonshine/parallel-constrained-decoding\n---\n\n# Parallel Constrained Decoding for Apple Silicon\n\n[](https://huggingface.co/spaces/drinkmoonshine/parallel-constrained-decoding)\n\n> **Live Demo**: Try the side-by-side comparison live on Hugging Face Spaces: [drinkmoonshine/parallel-constrained-decoding](https://huggingface.co/spaces/drinkmoonshine/parallel-constrained-decoding).\n\nA high-throughput inference engine for structured information extraction, decision routing, and categorical classification on Apple Silicon using MLX.\n\nParallel Constrained Decoding evaluates multi-field JSON schemas simultaneously rather than generating tokens sequentially. On an Apple Silicon M4 Max, it delivers **5.6x to 7.0x latency reductions** compared to standard autoregressive decoding with **100% schema validity** and **calibrated field-level confidence scores**.\n\n---\n\n## Performance Benchmarks (Apple Silicon M4 Max)\n\nEvaluated with `mlx-community/Qwen2.5-1.5B-Instruct-4bit` on macOS Sequoia:\n\n| Scenario | Fields | Autoregressive Baseline | Parallel Constrained | Latency Speedup | Syntax Validity |\n| :--- | :--- | :--- | :--- | :--- | :--- |\n| **Fintech Fraud Routing** | 4 fields | 420 ms (120 tok/s) | **75 ms** | **5.6x** | 100% guaranteed |\n| **Code Security Audit** | 4 fields | 380 ms (125 tok/s) | **68 ms** | **5.6x** | 100% guaranteed |\n| **High-Cardinality Tariff** | 1 field (255 choices) | 500 ms (118 tok/s) | **89 ms** | **5.6x** | 100% guaranteed |\n| **Enterprise Support Triage** | 28 fields | 1,900 ms (130 tok/s) | **270 ms** | **7.0x** | 100% guaranteed |\n\n---\n\n## Why Parallel Constrained Decoding?\n\n### The Problem", "params_total": null}, {"id": "sentence-transformers/all-MiniLM-L6-v2", "pipeline_tag": "sentence-similarity", "downloads": 255618777, "likes": 6048, "last_modified": "2026-06-01T06:29:13.000Z", "tags": ["sentence-transformers", "pytorch", "tf", "rust", "onnx", "safetensors", "openvino", "bert", "feature-extraction", "sentence-similarity"], "readme": "---\nbase_model:\n- nreimers/MiniLM-L6-H384-uncased\nlanguage: en\nlicense: apache-2.0\nlibrary_name: sentence-transformers\ntags:\n- sentence-transformers\n- feature-extraction\n- sentence-similarity\n- transformers\ndatasets:\n- s2orc\n- flax-sentence-embeddings/stackexchange_xml\n- ms_marco\n- gooaq\n- yahoo_answers_topics\n- code_search_net\n- search_qa\n- eli5\n- snli\n- multi_nli\n- wikihow\n- natural_questions\n- trivia_qa\n- embedding-data/sentence-compression\n- embedding-data/flickr30k-captions\n- embedding-data/altlex\n- embedding-data/simple-wiki\n- embedding-data/QQP\n- embedding-data/SPECTER\n- embedding-data/PAQ_pairs\n- embedding-data/WikiAnswers\npipeline_tag: sentence-similarity\n---\n\n\n# all-MiniLM-L6-v2\nThis is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 384 dimensional dense vector space and can be used for tasks like clustering or semantic search.\n\n## Usage (Sentence-Transformers)\nUsing this model becomes easy when you have [sentence-transformers](https://www.SBERT.net) installed:\n\n```\npip install -U sentence-transformers\n```\n\nThen you can use the model like this:\n```python\nfrom sentence_transformers import SentenceTransformer\nsentences = [\"This is an example sentence\", \"Each sentence is converted\"]\n\nmodel = SentenceTransformer('sentence-transformers/all-MiniLM-L6-v2')\nembeddings = model.encode(sentences)\nprint(embeddings)\n```\n\n## Usage (HuggingFace Transformers)\nWithout [sentence-transformers](https://www.SBERT.net), you can use the model like this: First, you pass your input through the transformer model, then you have to apply the right pooling-operation on-top of the contextualized word embeddings.\n\n```python\nfrom transformers import AutoTokenizer, AutoModel\nimport torch\nimport torch.nn.functional as F\n\n#Mean Pooling - Take attention mask into account for correct averaging\ndef mean_pooling(model_output, attention_mask):\n token_embeddings = model_output[0] #First element of model_output contains all token embeddings\n input", "params_total": null}, {"id": "Qwen/Qwen3.8-Flash-Next", "pipeline_tag": "image-text-to-text", "downloads": 706052, "likes": 5364, "last_modified": "2026-08-27T05:03:36.000Z", "tags": ["transformers", "safetensors", "qwen4_exp", "image-text-to-text", "conversational", "license:other", "eval-results", "endpoints_compatible", "region:us"], "readme": "---\nlibrary_name: transformers\nlicense: other\nlicense_name: qwen-community-1.0\nlicense_link: LICENSE\npipeline_tag: image-text-to-text\n---\n\n# Qwen3.8-Flash-Next\n\n> [!Note]\n> This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. \n>\n> These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc.\n\n> [!Tip]\n> For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by [Qwen Cloud](https://www.qwencloud.com).\n>\n> In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the [Qwen3.8-Flash Overview](https://www.qwencloud.com/models/qwen3.8-flash).\n\n\nAs the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. \n\n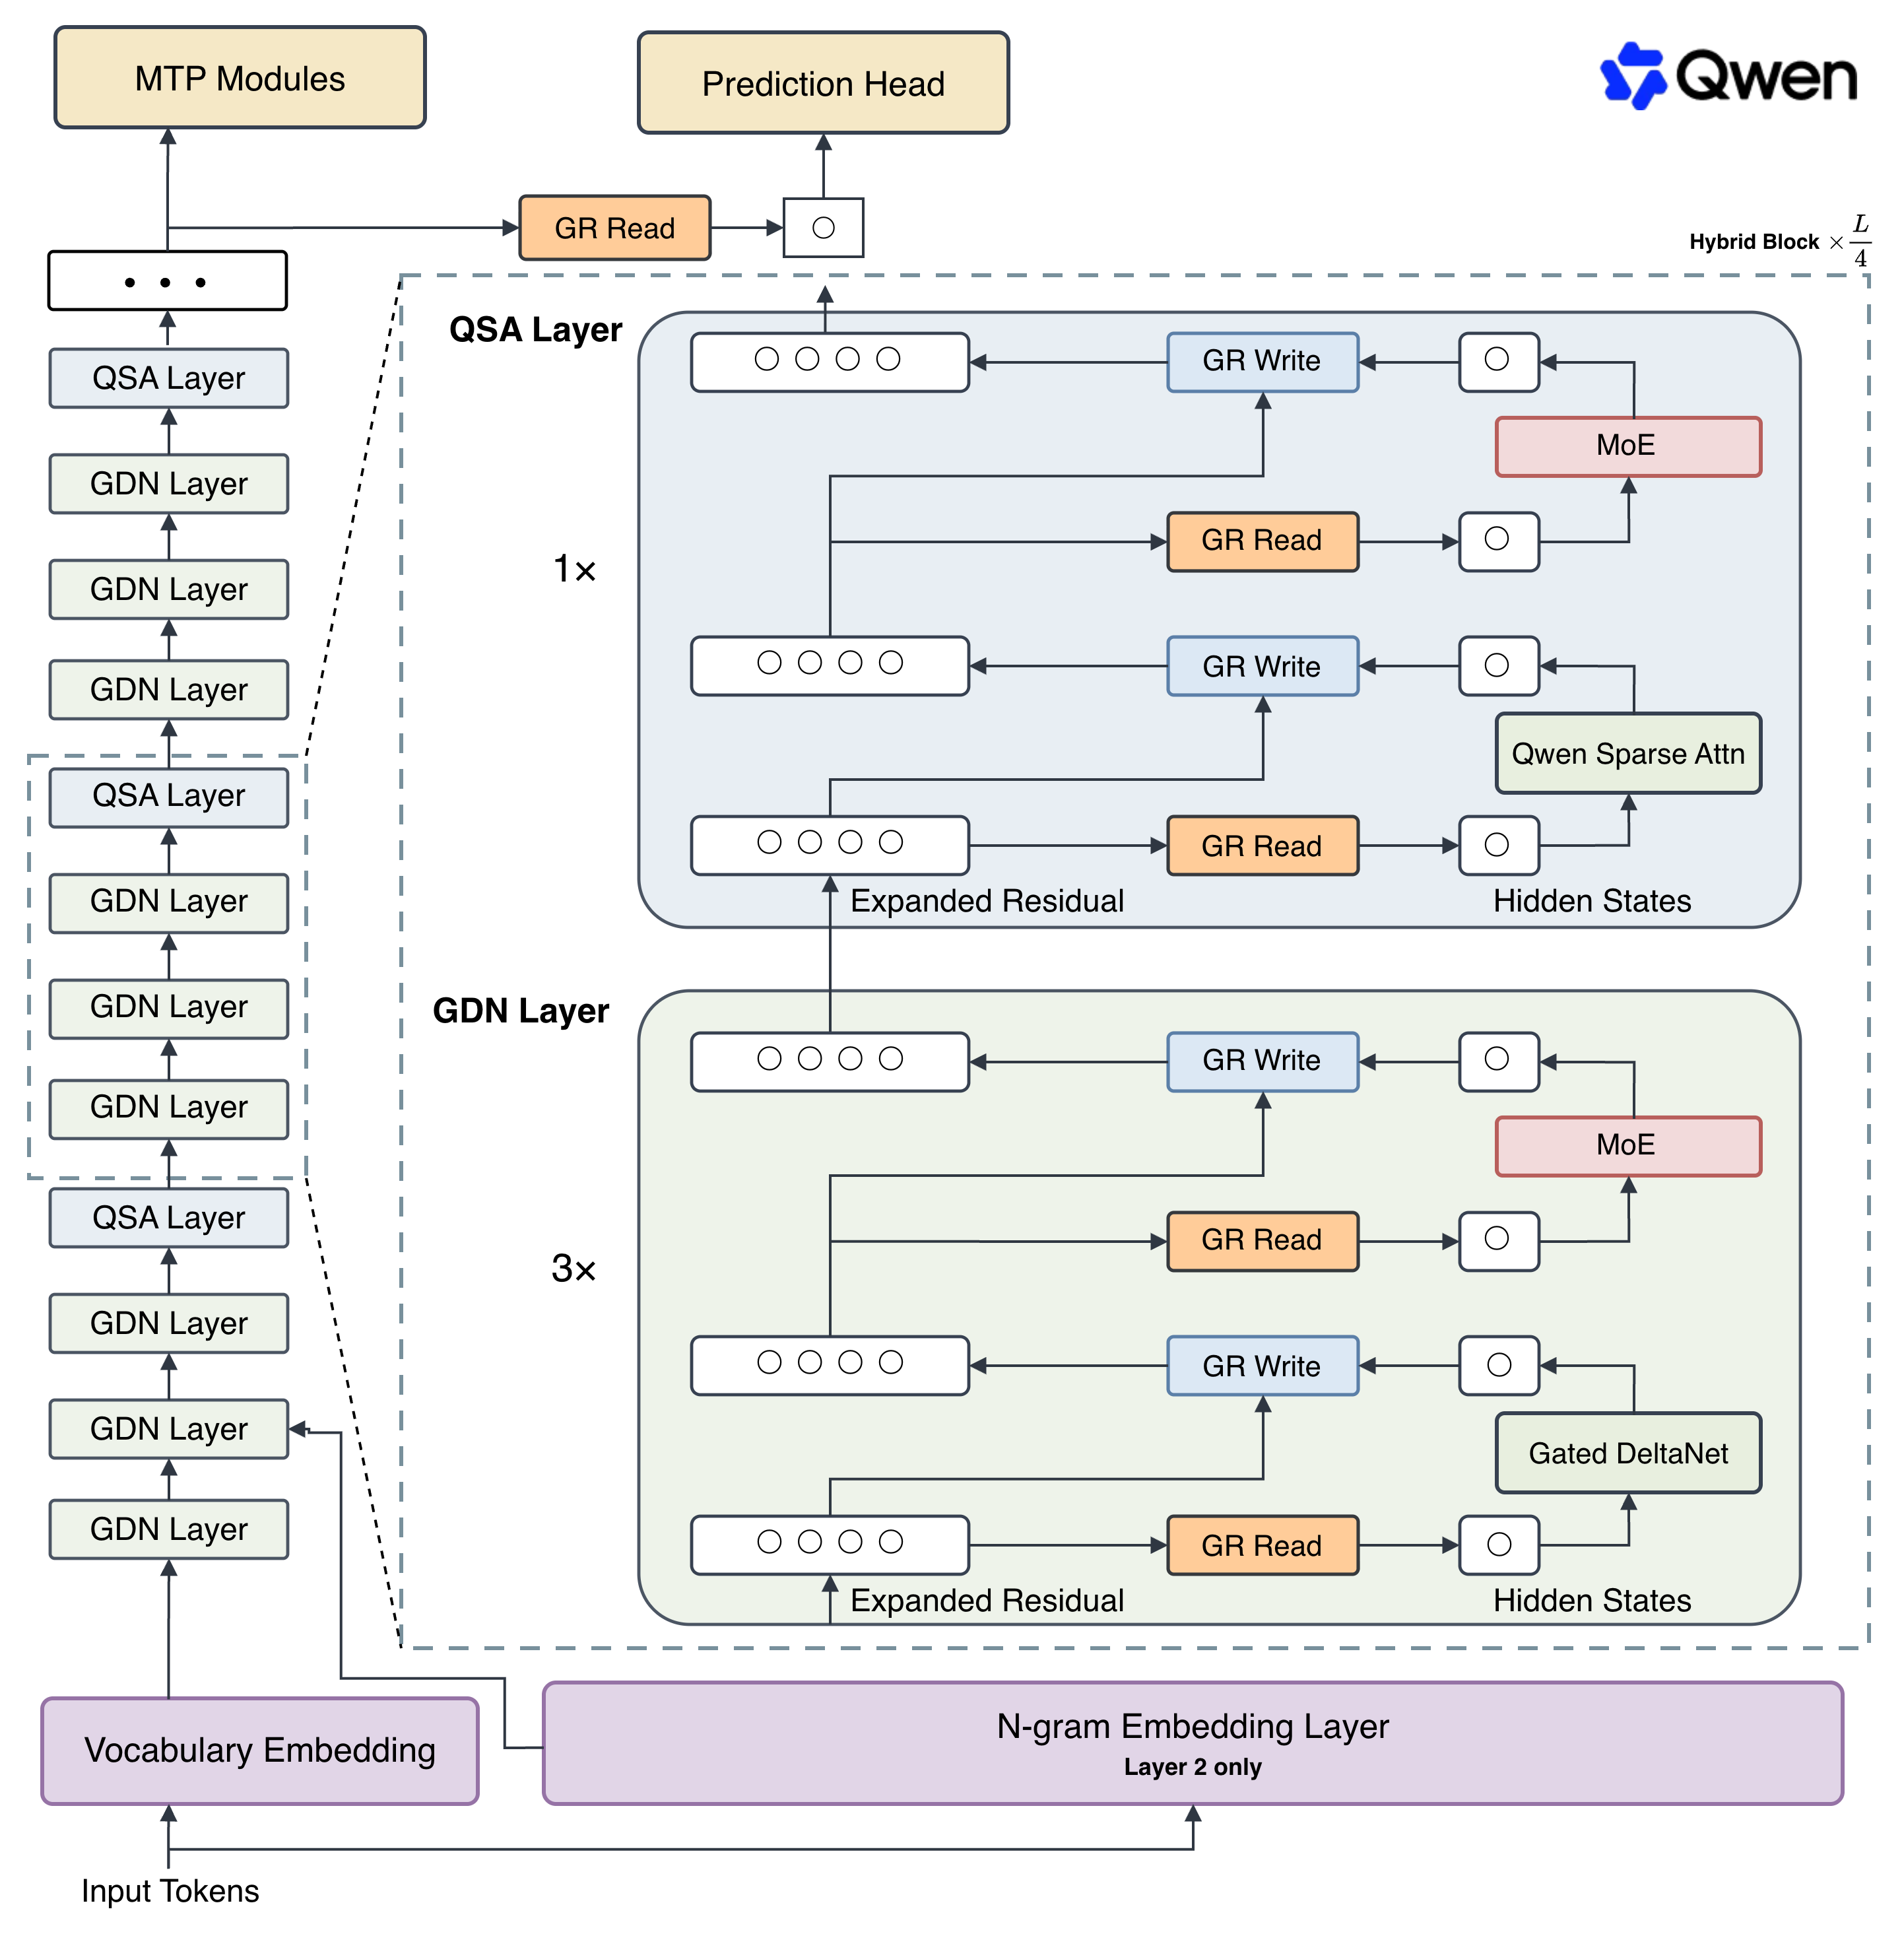\n\nThis experimental preview of the architecture that will underpin Qwen4 is built around a fundamental rethinking of how the core components of modern large language models (LLMs) interact at scale.\n \n## Highlights\n\nThe first open-weight release under this architecture is Qwen3.8-Flash-Next, which introduces:\n\n- **Hybrid Attention with QSA**: The Gated DeltaNet and Gated Attention pairing has been reworked into Gated DeltaNet and Qwen Sparse Attention (QSA). Rather than selecting individual tokens for processing, QSA operates at the micro-block level. This cuts long-context latency signifi", "params_total": null}, {"id": "dealignai/DeepSeek-V4.1-Flash-UNCENSORED-FP8", "pipeline_tag": "image-text-to-text", "downloads": 32011, "likes": 265, "last_modified": "2026-09-11T21:11:08.000Z", "tags": ["transformers", "safetensors", "deepseek_v41", "text-generation", "deepseek", "deepseek-v4.1", "abliterated", "uncensored", "crack", "multimodal"], "readme": "---\nlicense: mit\nlibrary_name: transformers\npipeline_tag: image-text-to-text\ntags:\n- deepseek\n- deepseek-v4.1\n- abliterated\n- uncensored\n- crack\n- multimodal\n- moe\n- fp8\nbase_model: deepseek-ai/DeepSeek-V4.1-Flash\nthumbnail: dealign_mascot.png\n---\n\n<div align=\"center\">\n<img src=\"dealign_mascot.png\" width=\"128\" />\n\n# DeepSeek-V4.1-Flash — UNCENSORED-FP8\n\n**Abliterated · No guardrails · Native FP8 · 1M-token context · Vision + tools · Reasoning-max default**\n\n[@dealignai](https://x.com/dealignai) · [@jordanschenck](https://x.com/jordanschenck)\n\n</div>\n\n---\n\n## What is this\n\n[DeepSeek-V4.1-Flash](https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash) with **permanent weight-level abliteration** — the safety guardrails have been surgically removed while preserving MMLU capability, vision, reasoning, MTP (DSpark), and multi-turn coherence.\n\n**Proprietary weight-level abliteration** developed by the dealignai research team. No custom `model.py`, no runtime hooks, no steering vectors — it's a standard checkpoint that loads exactly like the base model. The refusal circuitry is surgically removed while every capability-critical component (routed experts, Engram memory, CSA2 sparse attention, DSpark draft head, vision tower, router gates, norms, embeddings) is preserved byte-identical to the base.\n\n| | |\n|---|---|\n| **Base** | `deepseek-ai/DeepSeek-V4.1-Flash` (552B backbone, 8B/16B active per token) |\n| **Architecture** | Causal Encoder-Decoder (20+20 layers), MoE (384 routed top-6 + 1 shared), Hyper-Connections (4-channel residual), CSA2 sparse attention, Engram n-gram memory, DSpark speculative draft |\n| **Quant** | FP8 (`e4m3fn`) weights with E8M0 block-scale [32, 32], FP4 routed experts — **native, unchanged** |\n| **Context** | 1M tokens |\n| **Vision** | DeepSeek-ViT with 2D-RoPE + pixel unshuffle — untouched |\n| **Modification** | Surgical, weight-level (drop-in checkpoint) |\n\n## Results\n\n### HarmBench-320 — full 2×2 (base vs CRACK, effort=off vs max), T=0 greedy\n\nEver", "params_total": null}]}Contributor guide
No contributing guide indexed for this repository
Assessment
This issue has not been assessed yet.