ChenRocks / ChenRocks/fast_abs_rl
"too many values to unpack (expected 2)" in train_abstractor: src,target = sample
- Dominant language
- Python
- Stars
- 624
- Forks
- 183
- PR merge metrics
- No merged PRs in 30d
Description
I have been banging my head against a wall to get this working with my own dataset. I have successfully trained the word2vec model and the extraction labels but run into the too many values to unpack issue.
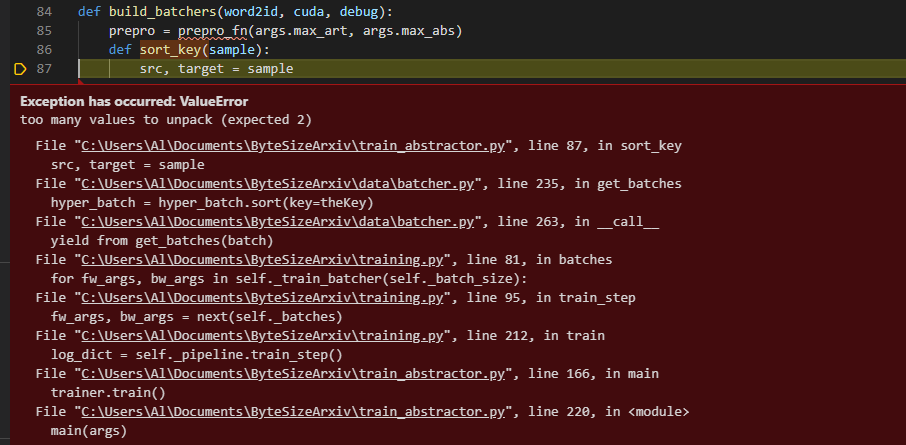
The contents of "sample" are an array of sentences from randomly concatenated 'highlights' which I assume is the 'target' portion but have not been able to confirm.
**possible related issues:**
- **made change in first line of main from** `with open(join(DATA_DIR,'vocab_cnt.pkl'), 'rb') as f` to `join(DATA_DIR,'train', 'vocab_cnt.pkl')` because after training there is no single vocab only one in each 'test' 'train' and 'val' folders (**I think this is the main issue here, what should the data directory be??**)
- "Warning: METEOR is not configured" while making extraction labels
- word2vec model trained in <4 seconds on 800,000 words
- differing versions (below)
**python 3.6.10
pytorch 1.5.0
cytoolz 0.10.1**
Contributor guide
No contributing guide indexed for this repository
Research direction
Start at the train_abstractor entry point and the `src,target = sample` unpacking, then trace how `sample` is created for the custom dataset. Compare the reported `vocab_cnt.pkl` locations in the train, test, and val folders; done means training reaches this step without the unpacking error and uses the intended dataset structure.
Written by the indexing model from the issue text.
Assessment
- Tech stack
- python, pytorch
- Domain
- data, machine-learning
- Issue type
- Bug
- Difficulty
- 4/5
- Estimated time
- 3-5 days
- Activity status
- Stale
- Clarity
- Needs clarification
- Newbie friendliness
- 25/100